New in AWS Quick: More capable flows, an updated web experience, and agents that work together

Turn one person’s process into your team’s process, get more done in the Quick web app, and get more complete answers from agents working together. AWS Quick is the AI workspace built only for work. Today, we are releasing updates that help your team get more of its everyday work done: Build, see, and improve … Read more
Cut self-hosted LLM cost and latency with the distributed KV caching agent skill

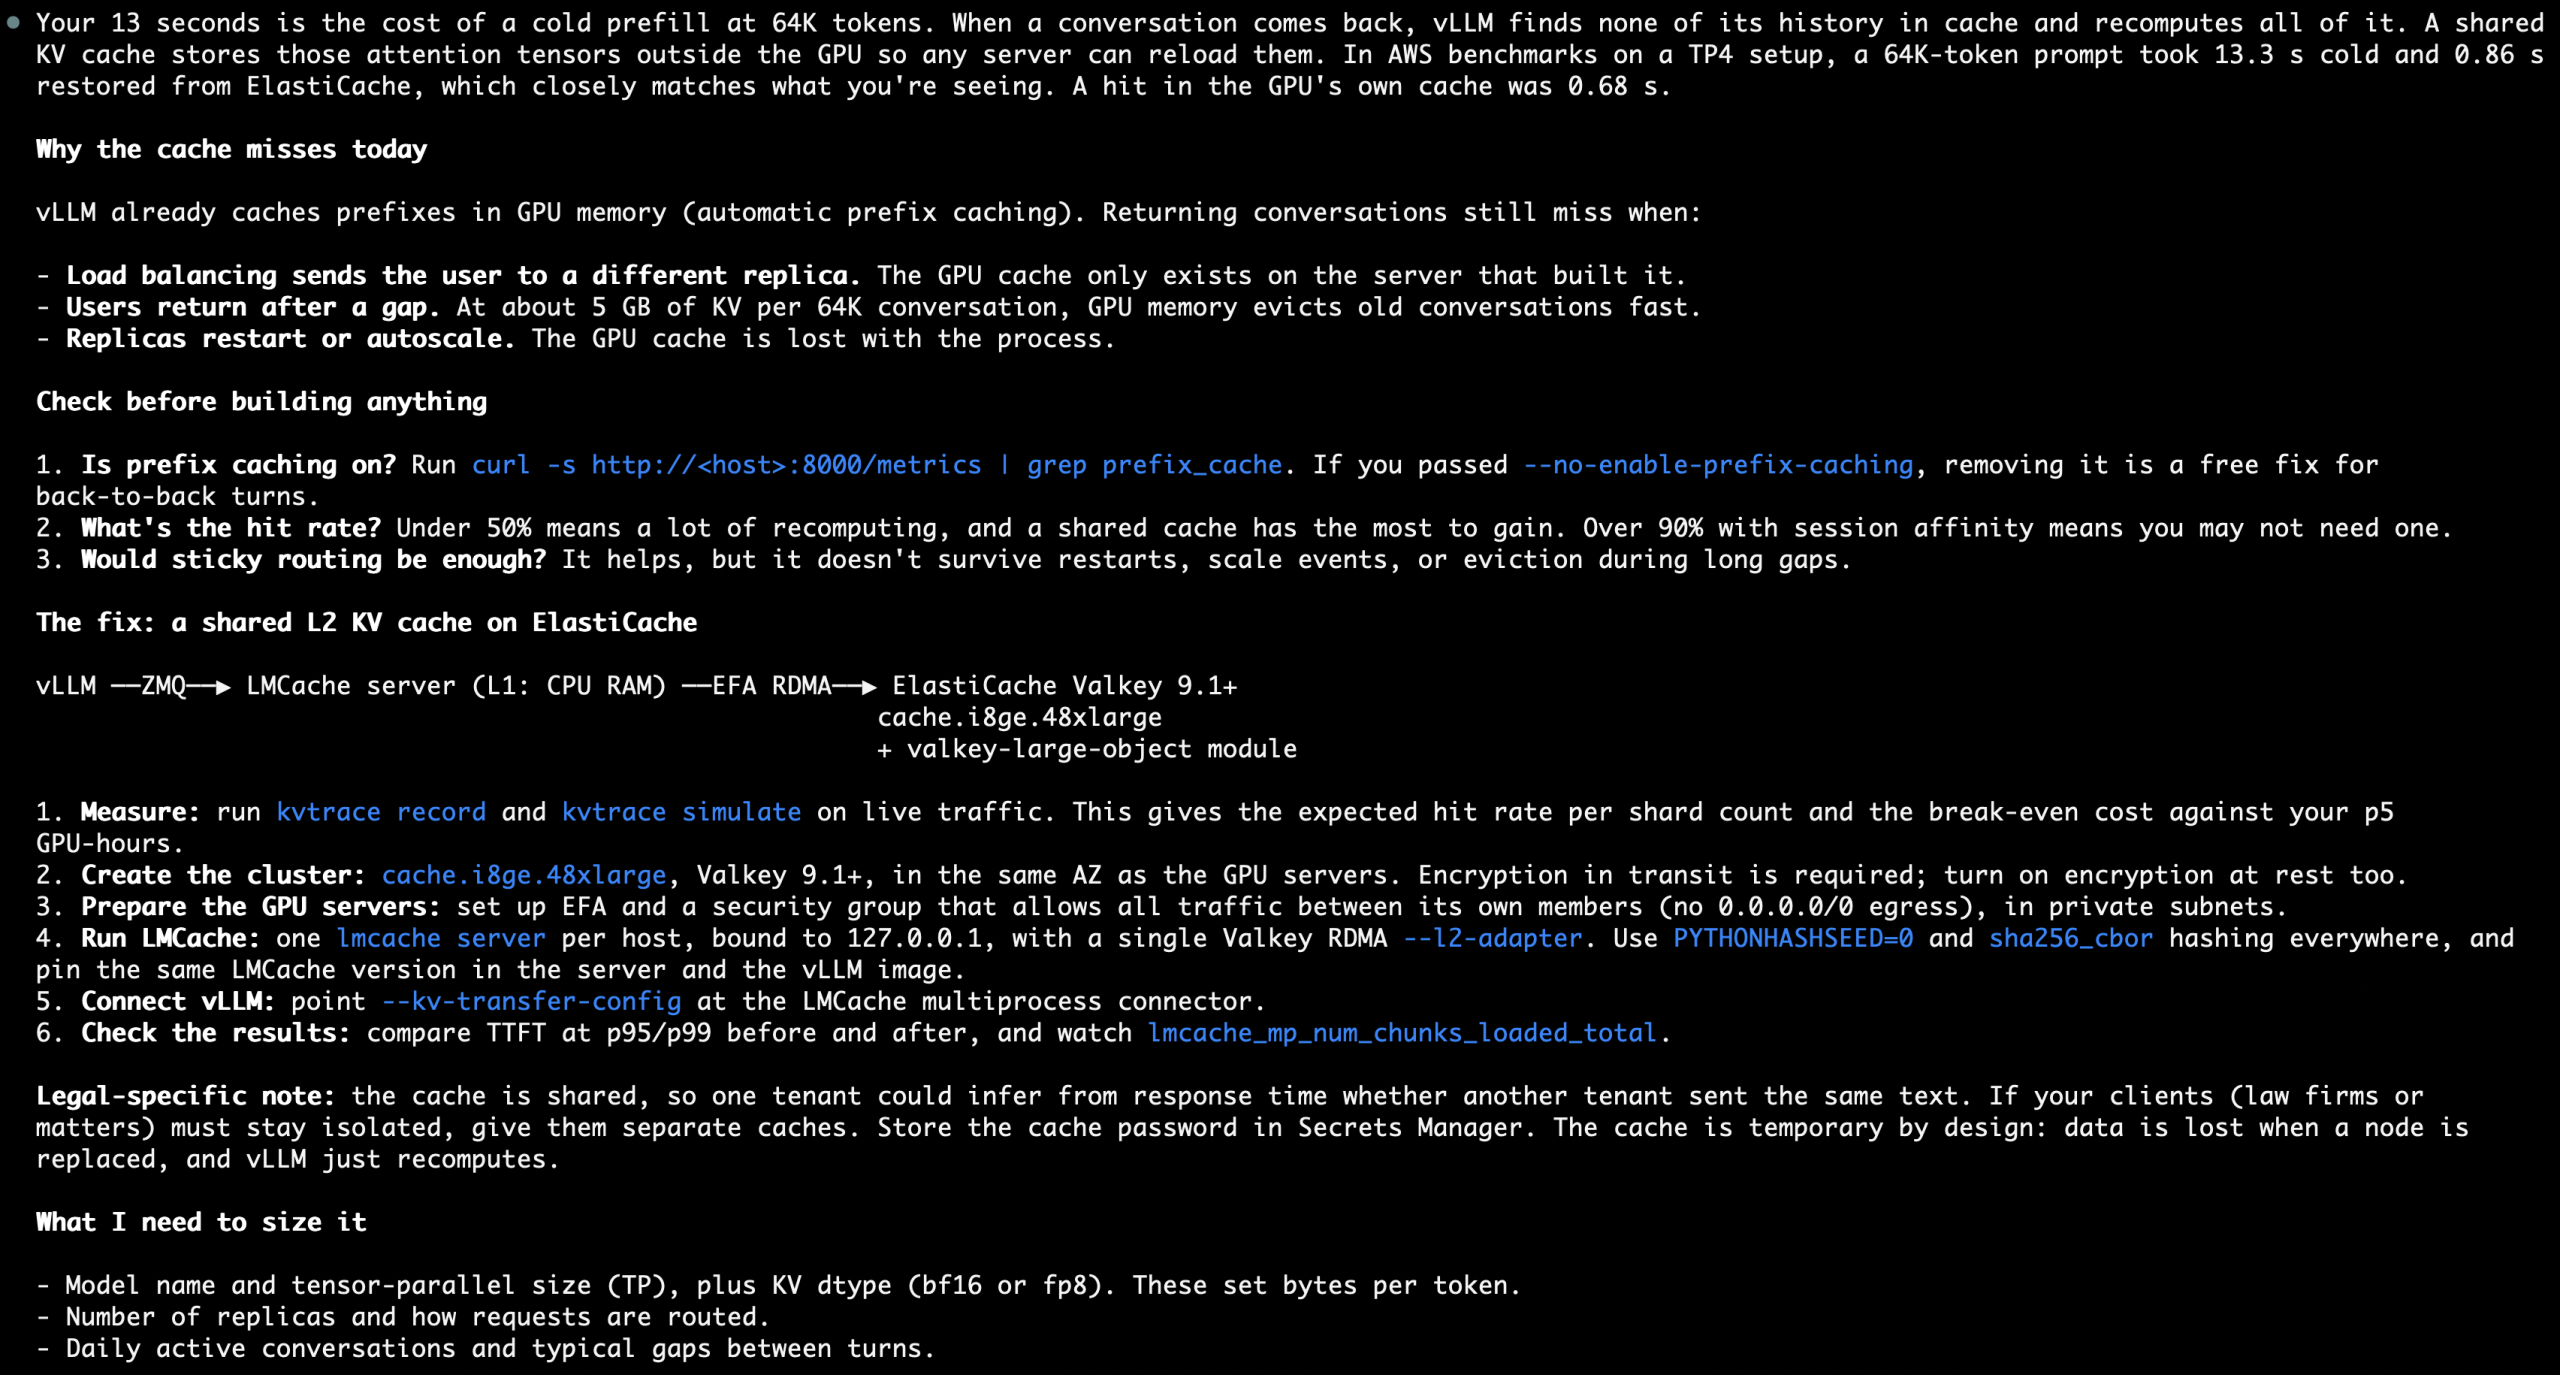
Customers increasingly self-host large language models (LLMs) on GPUs for control over cost, accuracy, and latency. However, self-hosting often means paying for redundant GPU work because small, isolated caches on each server can’t hold or share the growing context AI agents and chat applications resend. Consider a legal AI assistant that can accumulate hundreds of … Read more

Introducing managed cluster extensions for observability and user management in Amazon SageMaker HyperPod Slurm

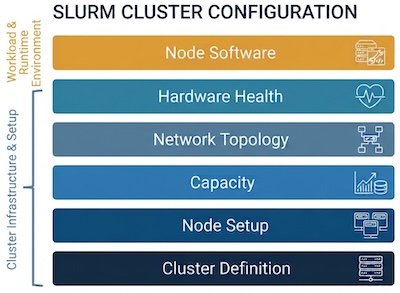
Keeping a shared Slurm cluster for foundation model development in sync entails keeping several separately maintained pieces of configuration matched to what’s running on the nodes. The cluster’s shape lives on multiple configuration files, its software in custom scripts, its network topology in files that must be edited as nodes change, and its users in … Read more

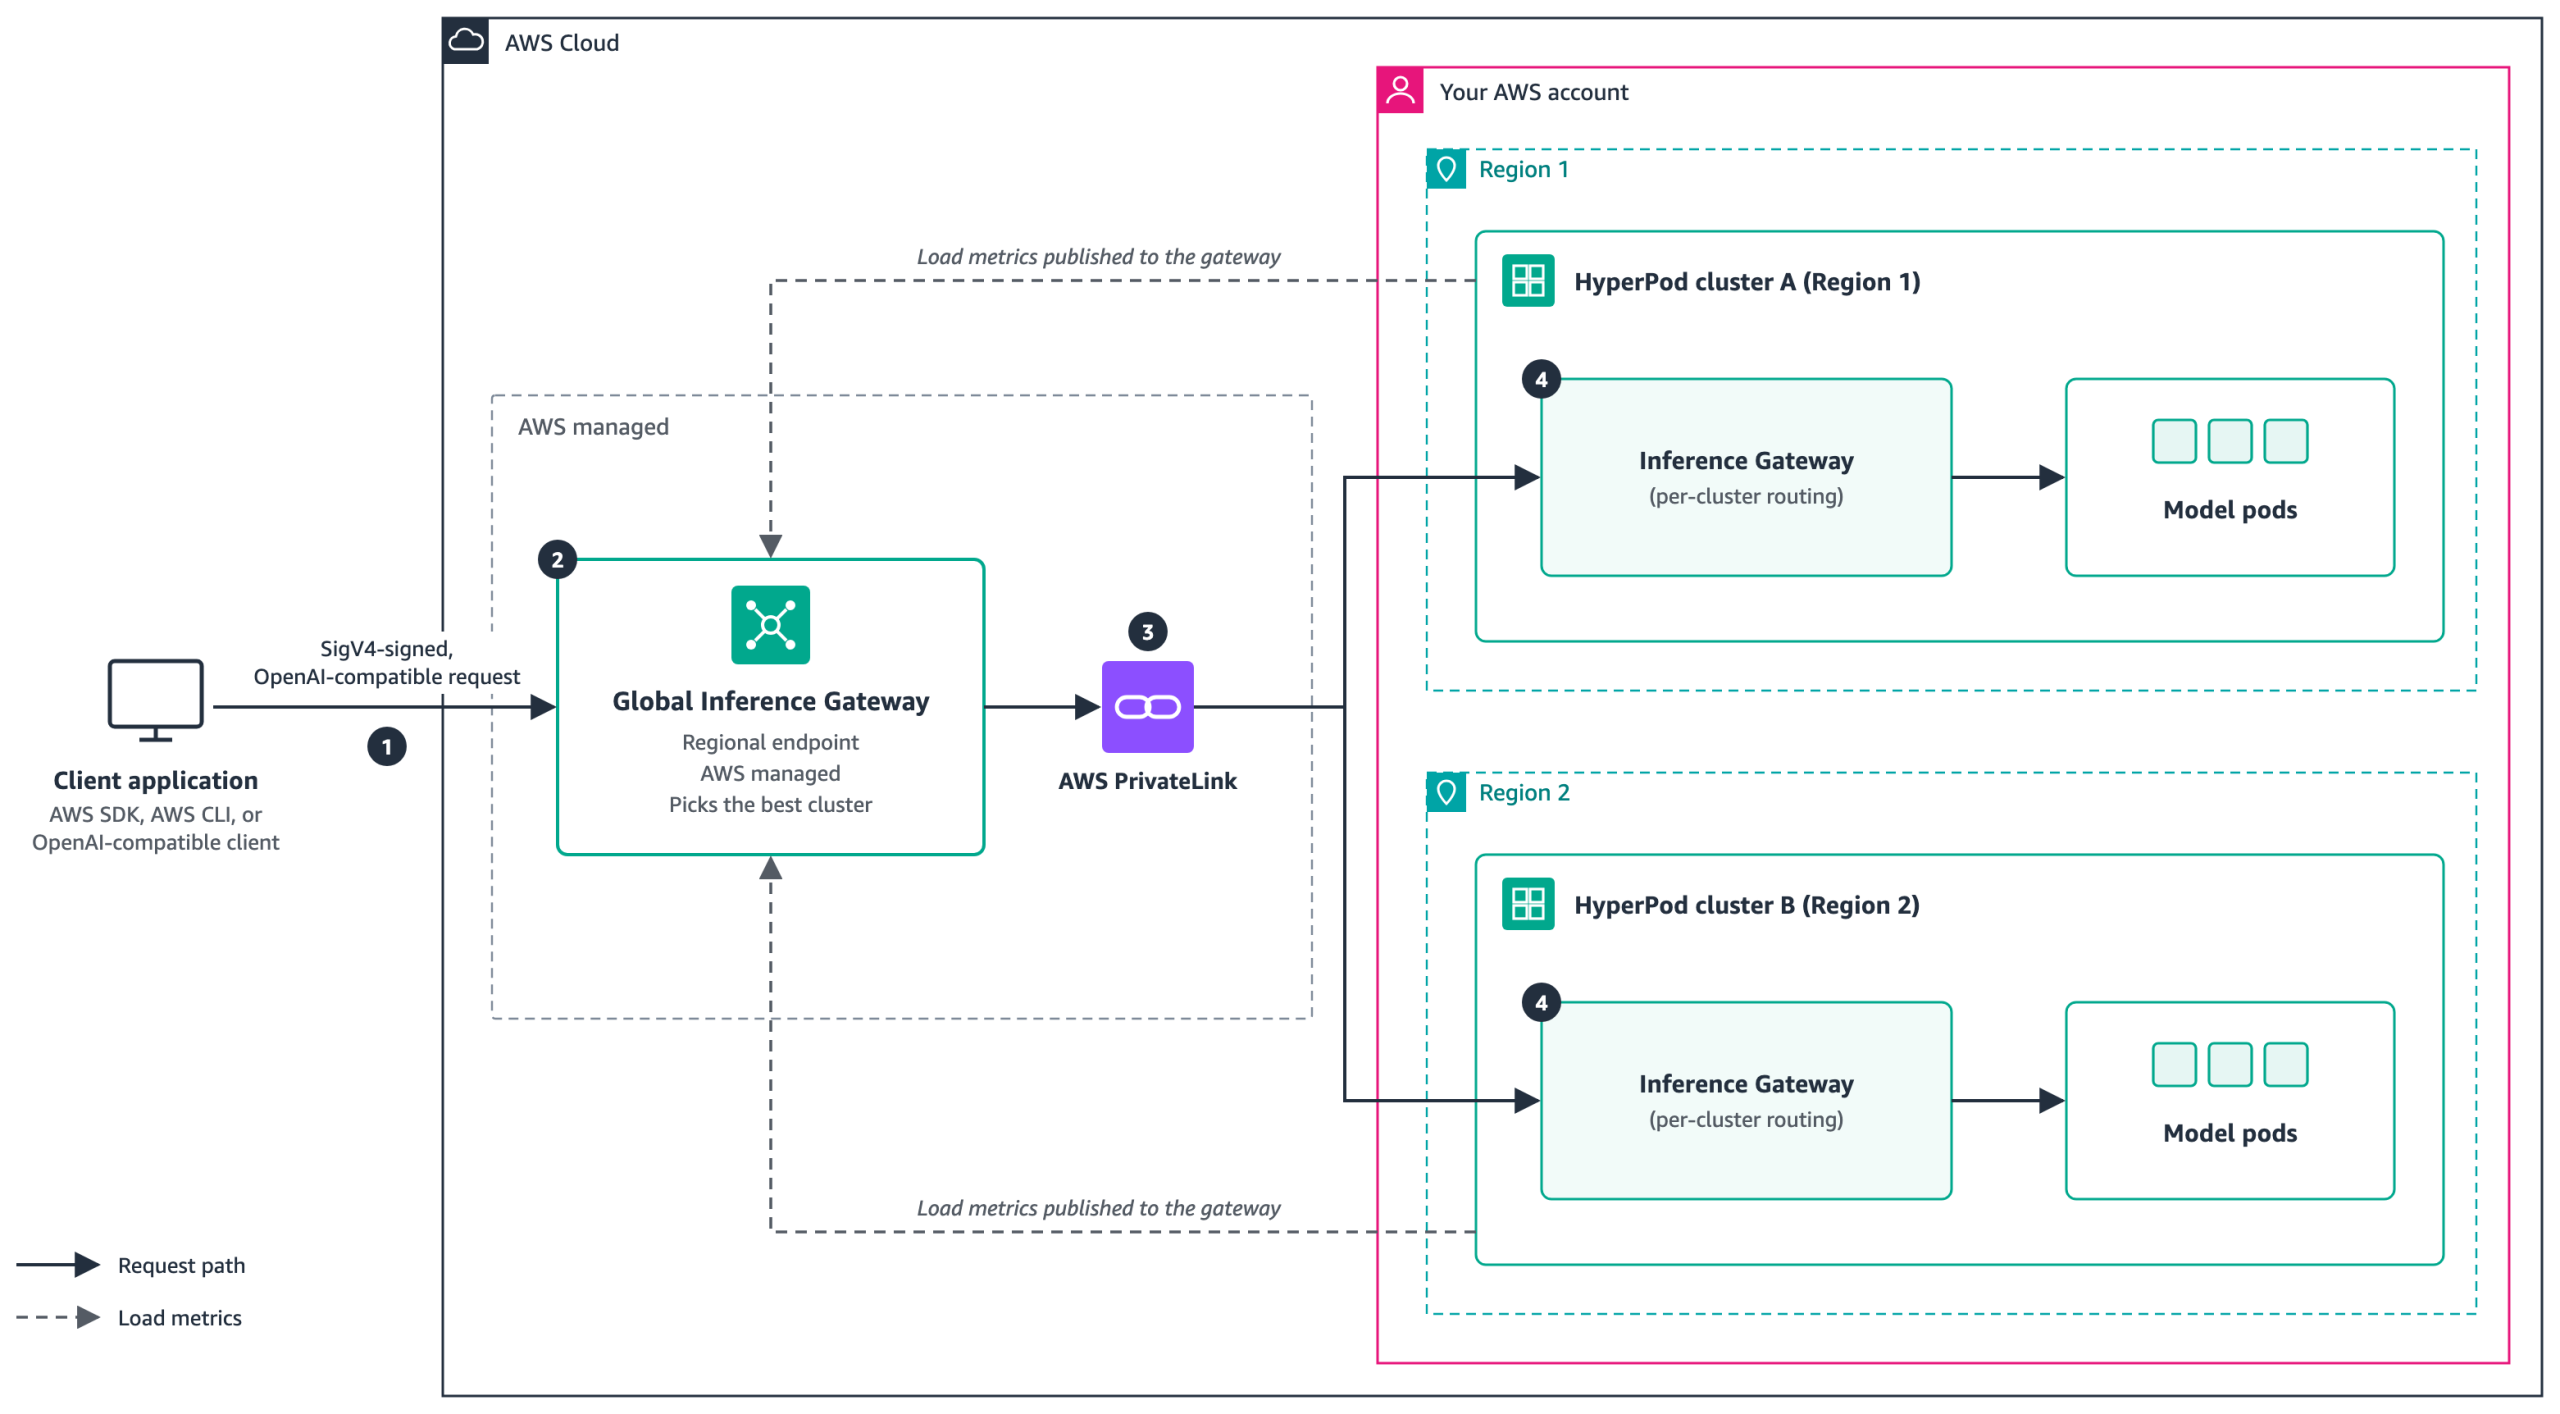
Introducing Amazon SageMaker HyperPod Global Inference Gateway: One endpoint across Regions and clusters

During a traffic peak, a request can sit in a queue on a saturated HyperPod cluster while GPUs on another cluster, sometimes in another AWS Region, sit idle. You have already paid for that capacity, but your requests can’t reach it. In Introducing Amazon SageMaker HyperPod Inference Gateway, we showed how the Inference Gateway gives … Read more

Announcing Amazon Textract Insights: Verifiable generative AI for documents

Organizations across financial services, insurance, healthcare, and the public sector depend on document processing. They turn scanned files and paper forms into structured data their systems can act on. As generative AI has matured, these organizations want more than accurate text extraction. They want to describe the information they need in their own words and … Read more

Use Kimi Code CLI with models on Amazon Bedrock

Kimi Code CLI is an open source coding agent from Moonshot AI, the creator of the Kimi series of open-weight foundation models. Previously, using Kimi Code with models on Amazon Bedrock meant configuring a generic connection “provider” with an Amazon Bedrock API key. For many AWS customers, this meant introducing an extra credential to obtain … Read more

Enable AI agents to pay for AWS Marketplace x402 products with Amazon Bedrock AgentCore payments

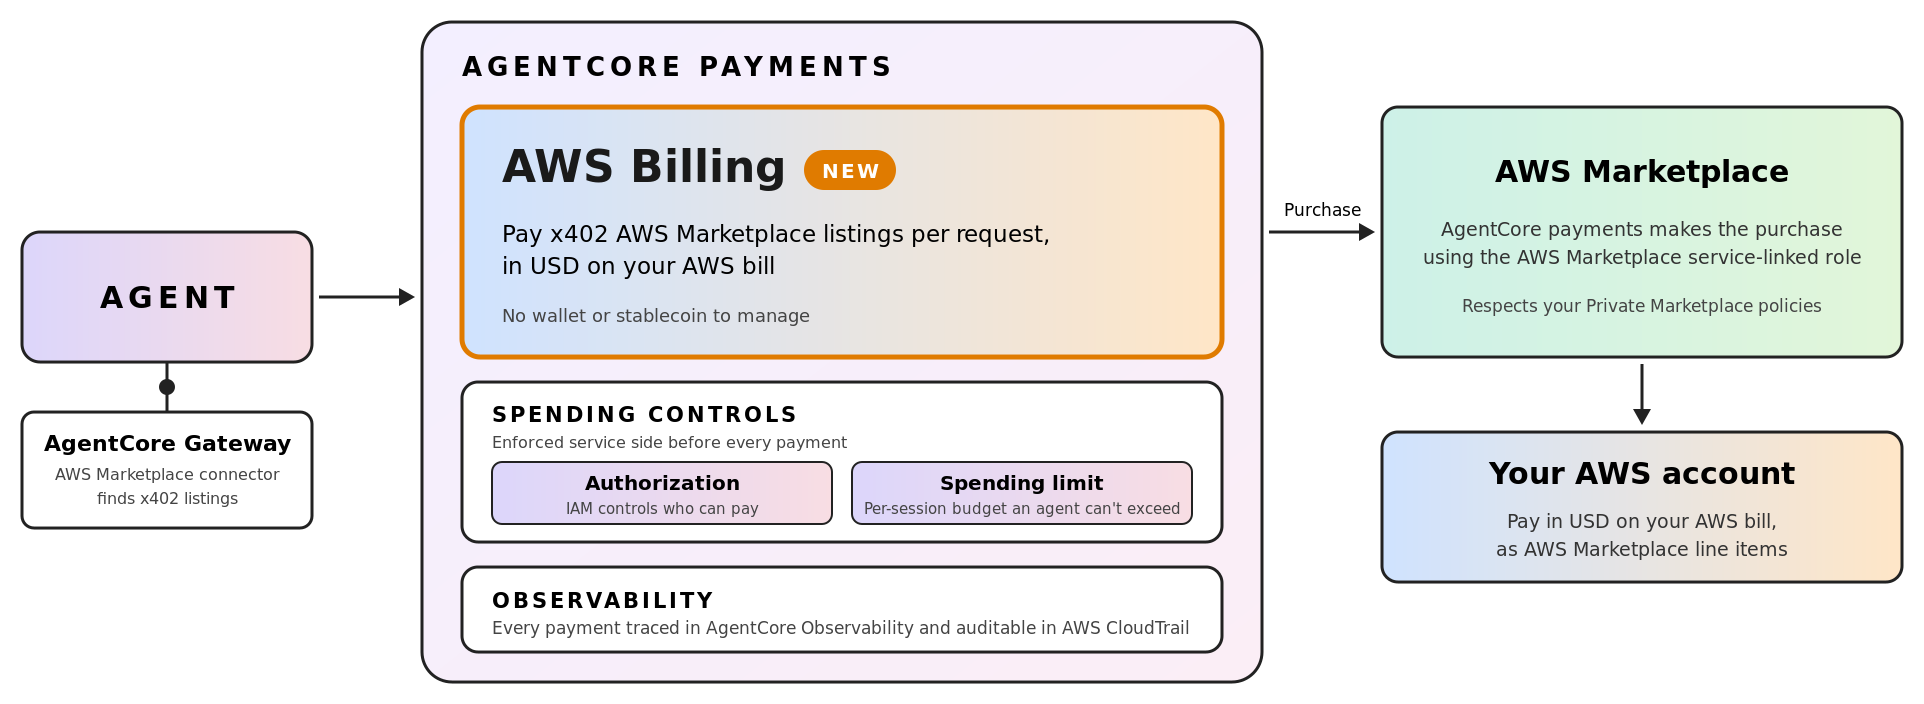
When Amazon Bedrock AgentCore payments became generally available in August 2026, agents could autonomously pay for paid APIs, MCP servers, and web content over open protocols like x402 and MPP with payment limits and full observability. Today we extend that autonomy to AWS Marketplace, so agents can discover and buy x402-enabled software, APIs, data, and … Read more

How the BMW Group governs hundreds of agents across thousands of developers

When hundreds of agents serve thousands of developers, enterprise governance can’t be an afterthought. At the BMW Group’s R&D, more than 12,500 developers work on approximately 500 million lines of vehicle software code. This software is augmented by the BMW Connected Vehicle backend, a cloud-based system of more than 1,300 microservices providing digital services for … Read more

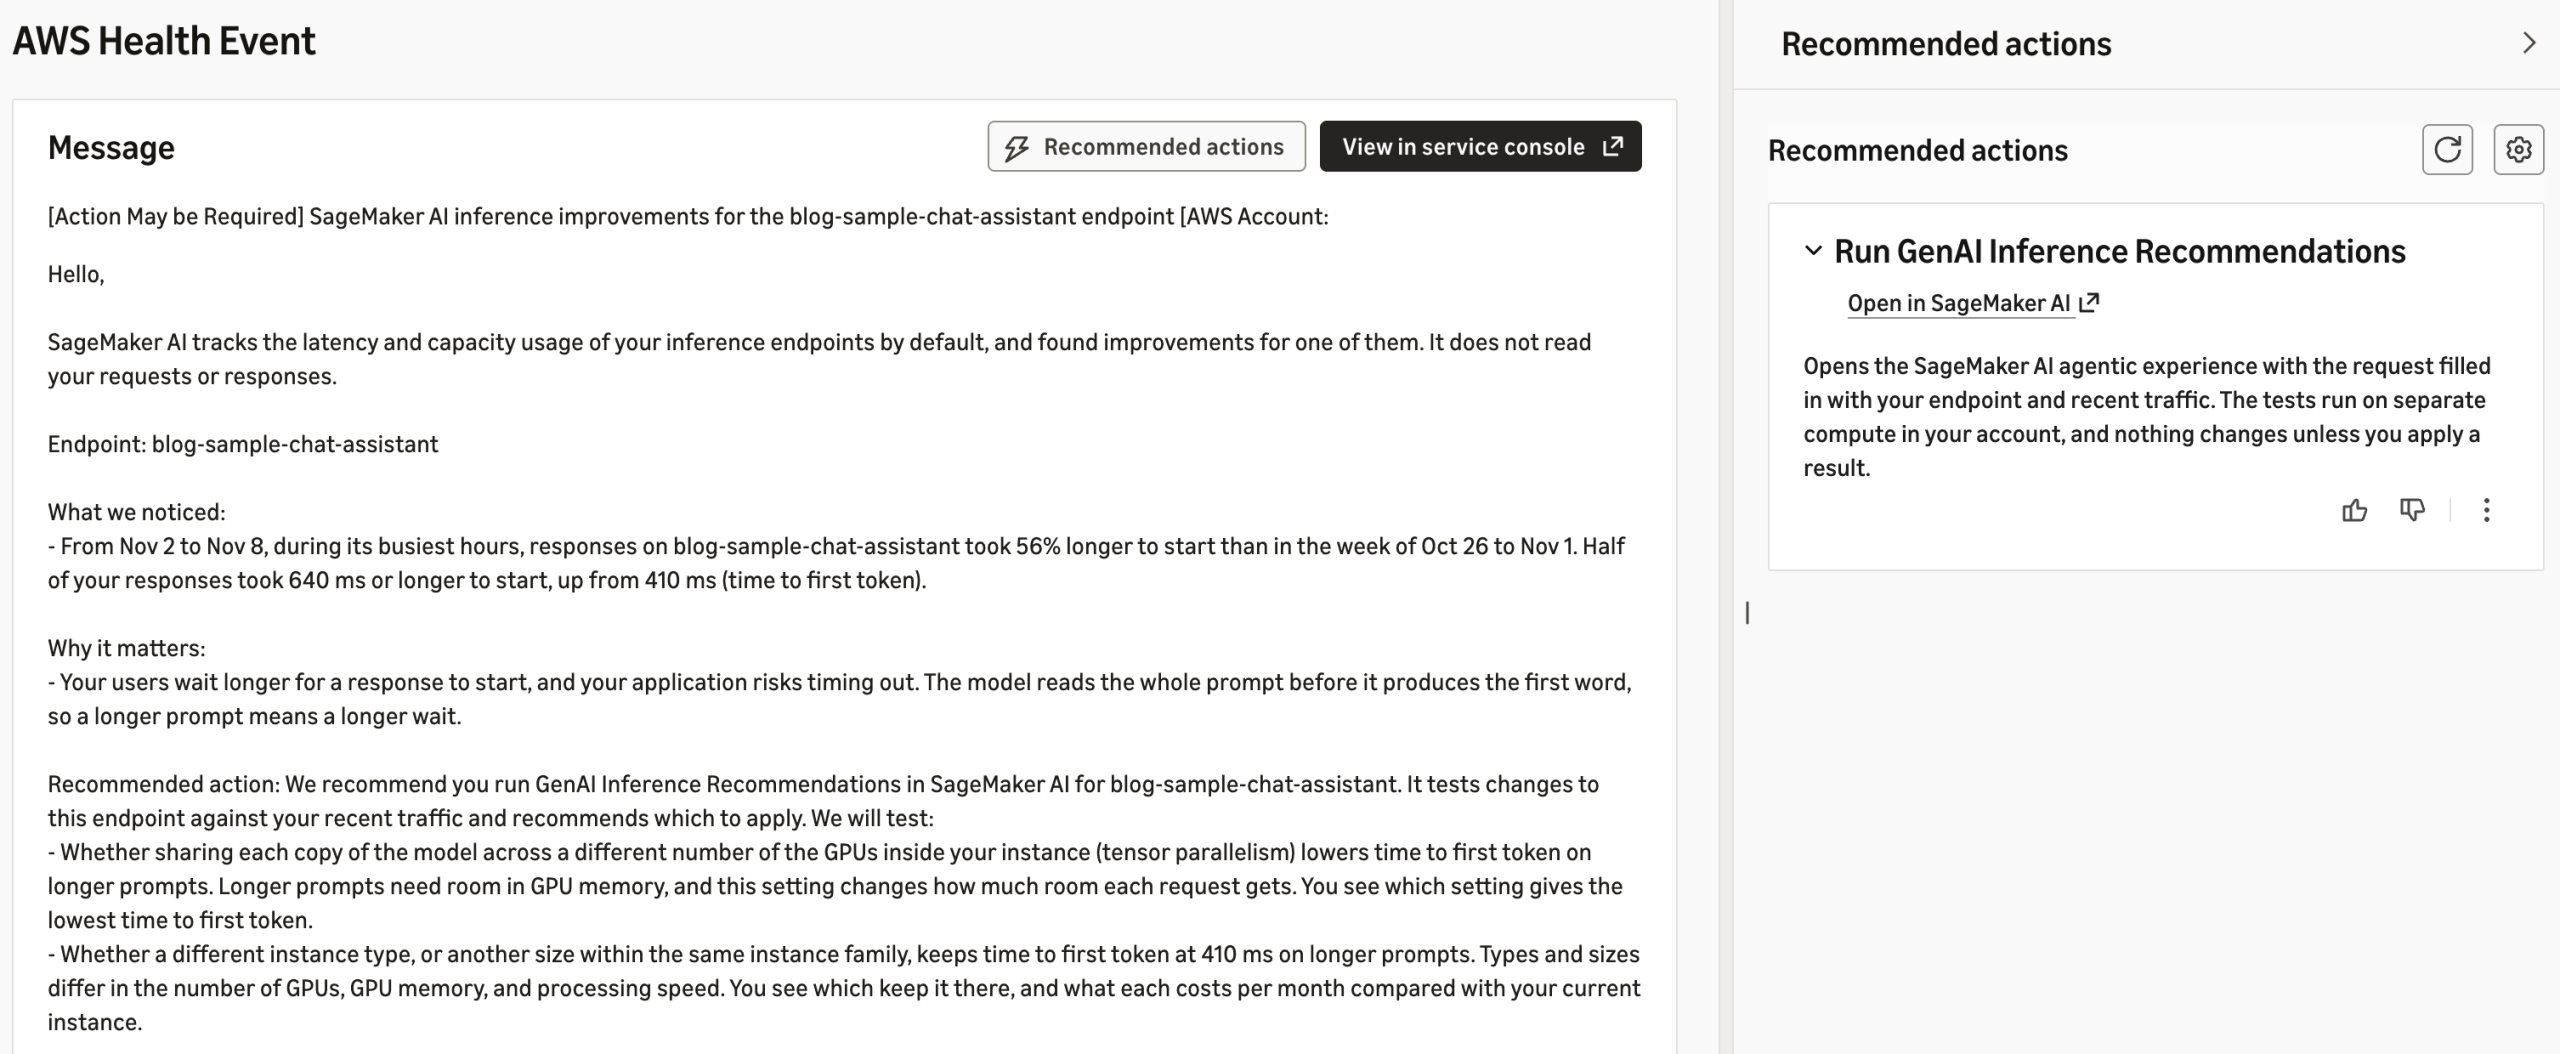
Amazon SageMaker AI now detects latency drift, idle GPUs, and missed optimizations on your inference endpoints

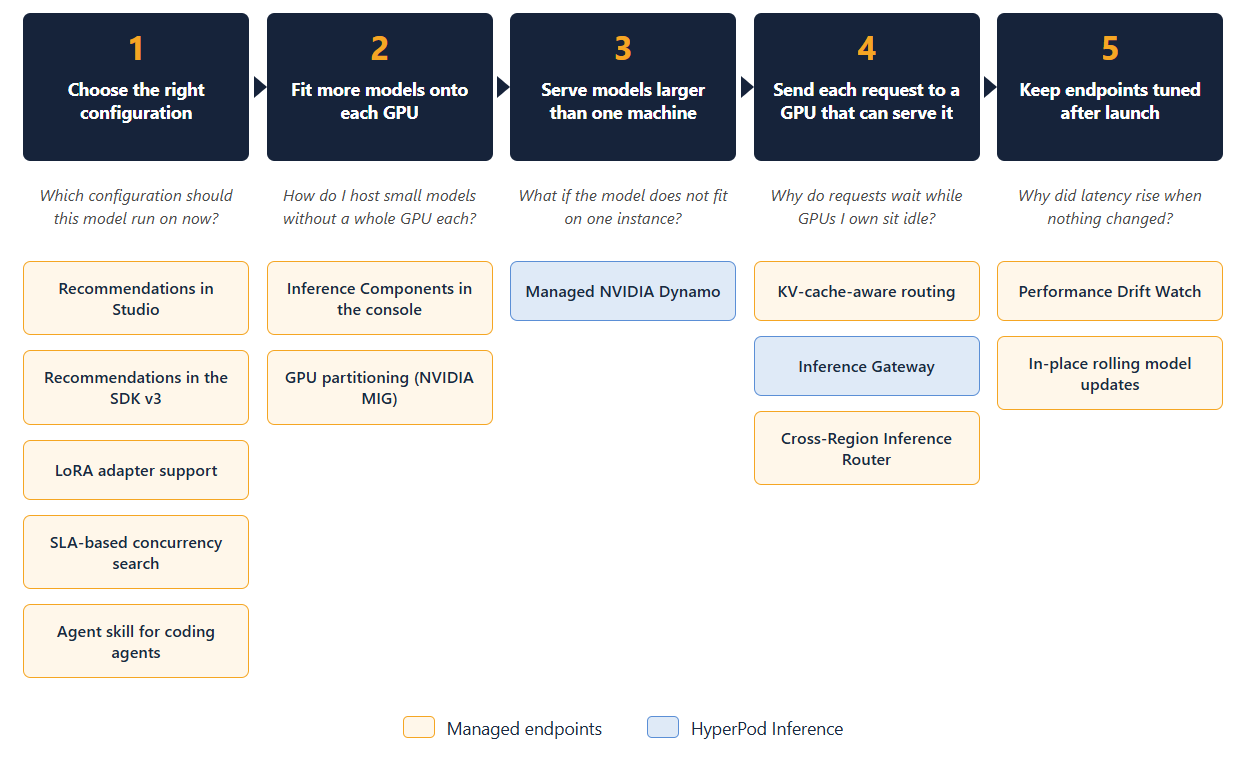
Every inference endpoint is well tuned the day it goes into production. Teams choose an instance type, serving configuration, and scaling settings that suit the model and its traffic at launch. With the endpoint serving smoothly, they understandably move on to the next priority. The workload, however, rarely stays still. Traffic patterns evolve, prompts grow … Read more

Inside Amazon Connect Talent: The science of structured AI interviews 

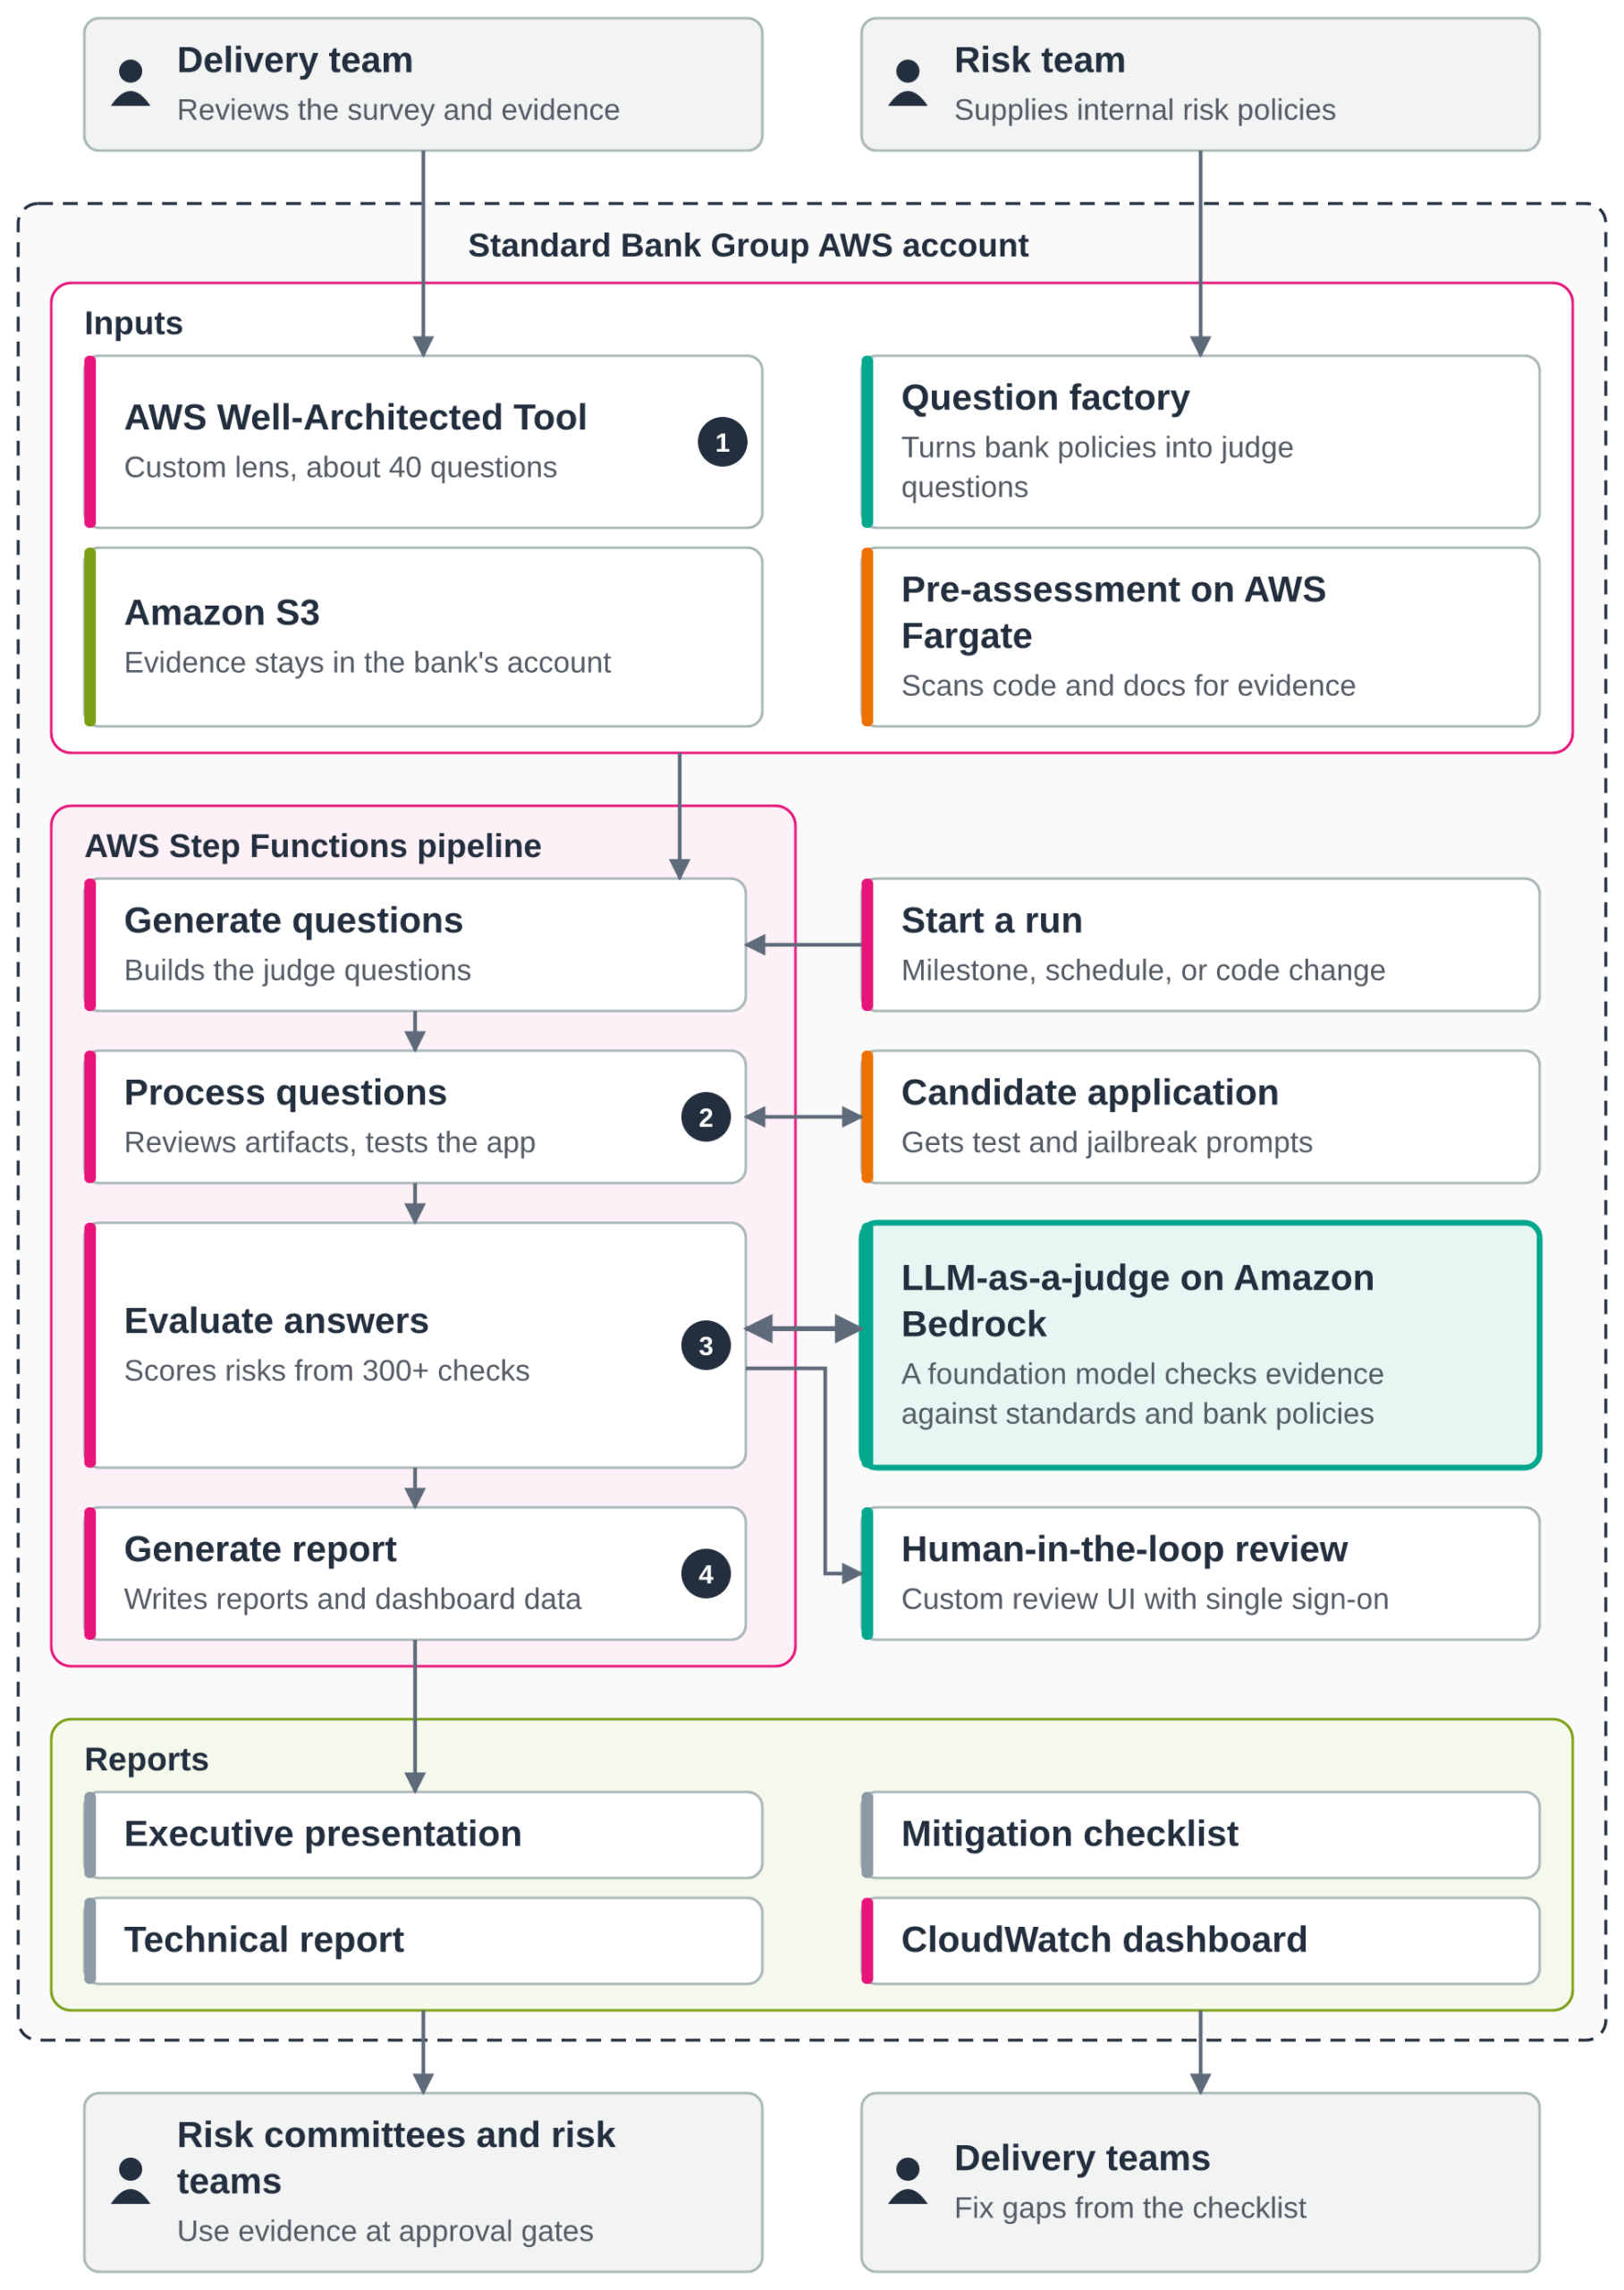
For organizations hiring hundreds or thousands of people, every interview presents the same challenge: How do you give candidates a consistent opportunity to demonstrate their skills while gathering the evidence needed to make informed hiring decisions?  Structured behavioral interviews offer a research-backed approach to this challenge. They use consistent, job-related questions and clear scoring criteria … Read more

Amazon Bedrock AgentCore harness adds Strands harness defaults, built-in tools, and lifecycle hooks

When building an AI agent, selecting a model is only the first step. The agent still needs tools, instructions for finishing the job, a way to manage context growth in long sessions, and guardrails before it executes any consequential actions, like issuing a refund. We are upgrading Amazon Bedrock AgentCore harness to use Strands harness, … Read more

Optimize AI economics on Amazon Bedrock with Accenture’s sequenced approach

As enterprises scale AI on Amazon Bedrock, token spend often grows even as per-token prices fall. Without cost allocation tags in place, your cloud invoice shows AI spend as a single line item rather than by team, workload, agent, or model. Cheaper tokens expand adoption, and agentic workloads multiply invocations. As successful AI use cases … Read more

From learning to leaderboard: How Cisco upskilled 1,200 engineers in agentic AI with AWS AI League

Cisco, like many large engineering organizations, is adopting generative and agentic AI to change how its engineers build software. The hard part is no longer access to the technology. It’s helping thousands of engineers move from watching a demo to confidently building with it. Recorded sessions and slide decks rarely close that gap. Engineers learn … Read more

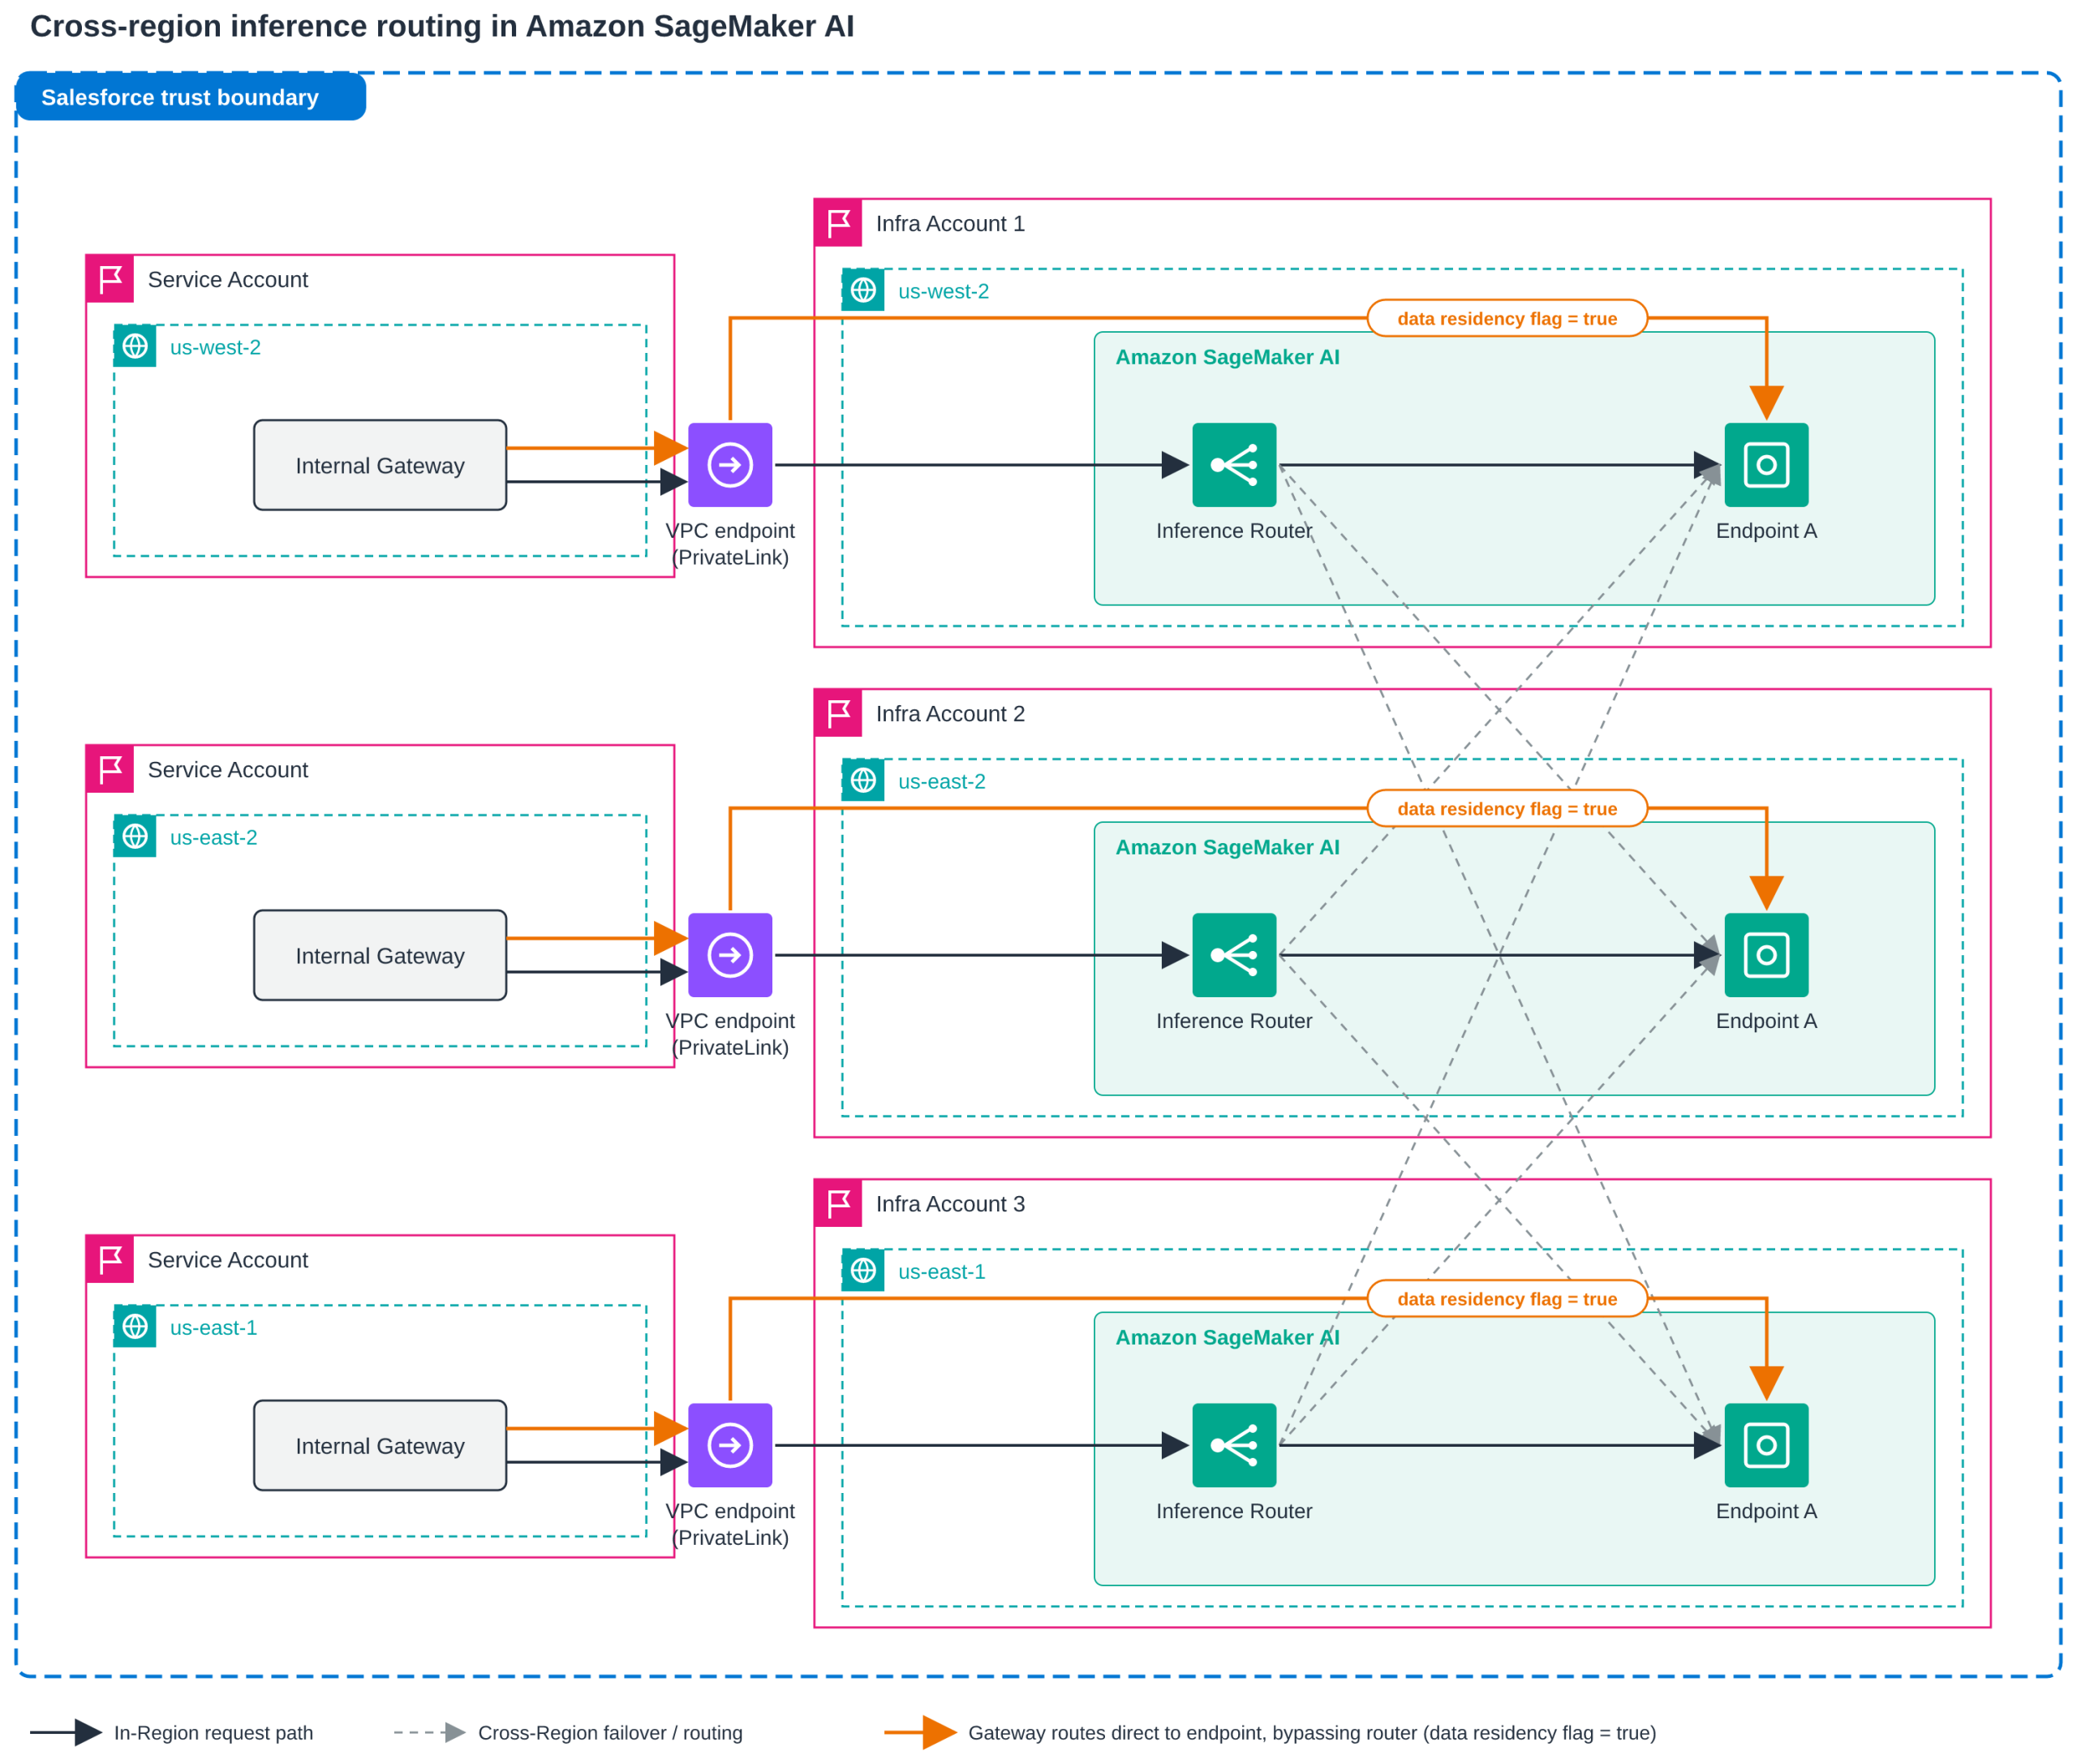
Keep inference running through regional capacity shortfalls with cross-Region inference routing in Amazon SageMaker AI

Serving a model from more than one AWS Region is a well-established pattern for highly available inference: when one Region runs short of GPU capacity, requests move to another. The pattern is simple to describe and hard to operate. Until now, if you served models on Amazon SageMaker AI managed endpoints, cross-Region routing was a … Read more

Protect agent tool calls with Skyflow and Amazon Bedrock AgentCore Gateway

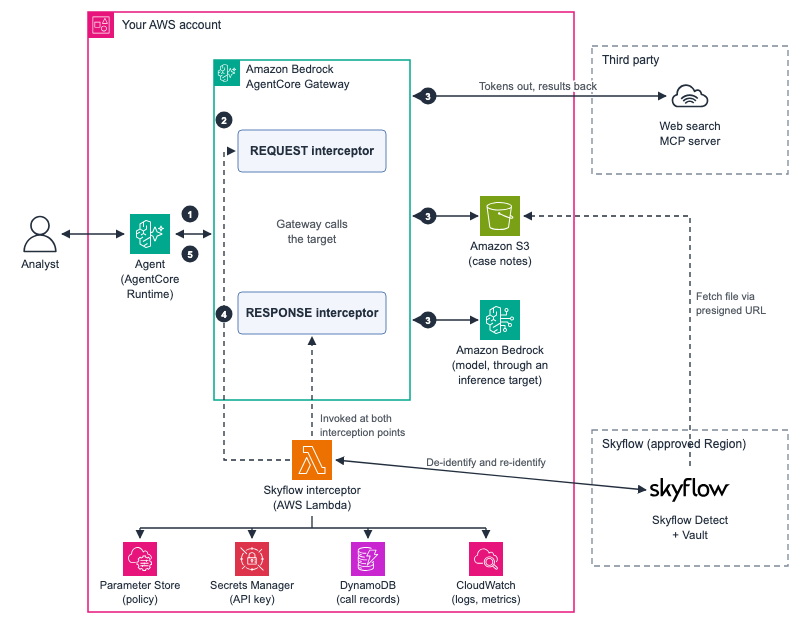
In this post, we show how Skyflow and Amazon Bedrock AgentCore Gateway keep sensitive data out of the tools your AI agents call, and out of the model context those tools feed. We add Skyflow Detect to Amazon Bedrock AgentCore Gateway as a request and response interceptor. The Skyflow interceptor de-identifies data before it reaches … Read more

Introducing enhanced infrastructure observability in Amazon SageMaker HyperPod

Large-scale model training is one of the most expensive workloads you can run on GPUs, and a single unhealthy accelerator can stall an entire distributed job. When training throughput drops, the hard part is rarely noticing that something is wrong. It is figuring out why and where. Teams often spend hours or days sifting through … Read more

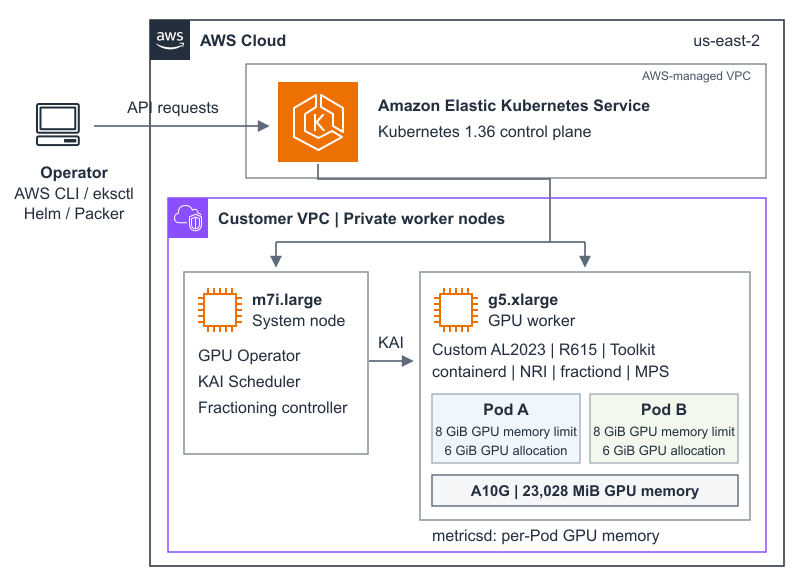
Using NVIDIA Run:ai GPU Fractioning on Amazon EKS

GPU sharing is not new: Multi-Instance GPU (MIG), time-slicing, and Multi-Process Service (MPS) address different isolation and utilization needs. NVIDIA Run:ai GPU Fractioning builds on MPS with Kubernetes-integrated scheduling, per-Pod memory contracts, enforcement, and metrics. NVIDIA Run:ai is AI workload orchestration software for Kubernetes. Its GPU Fractioning Operator can help several teams share one or … Read more

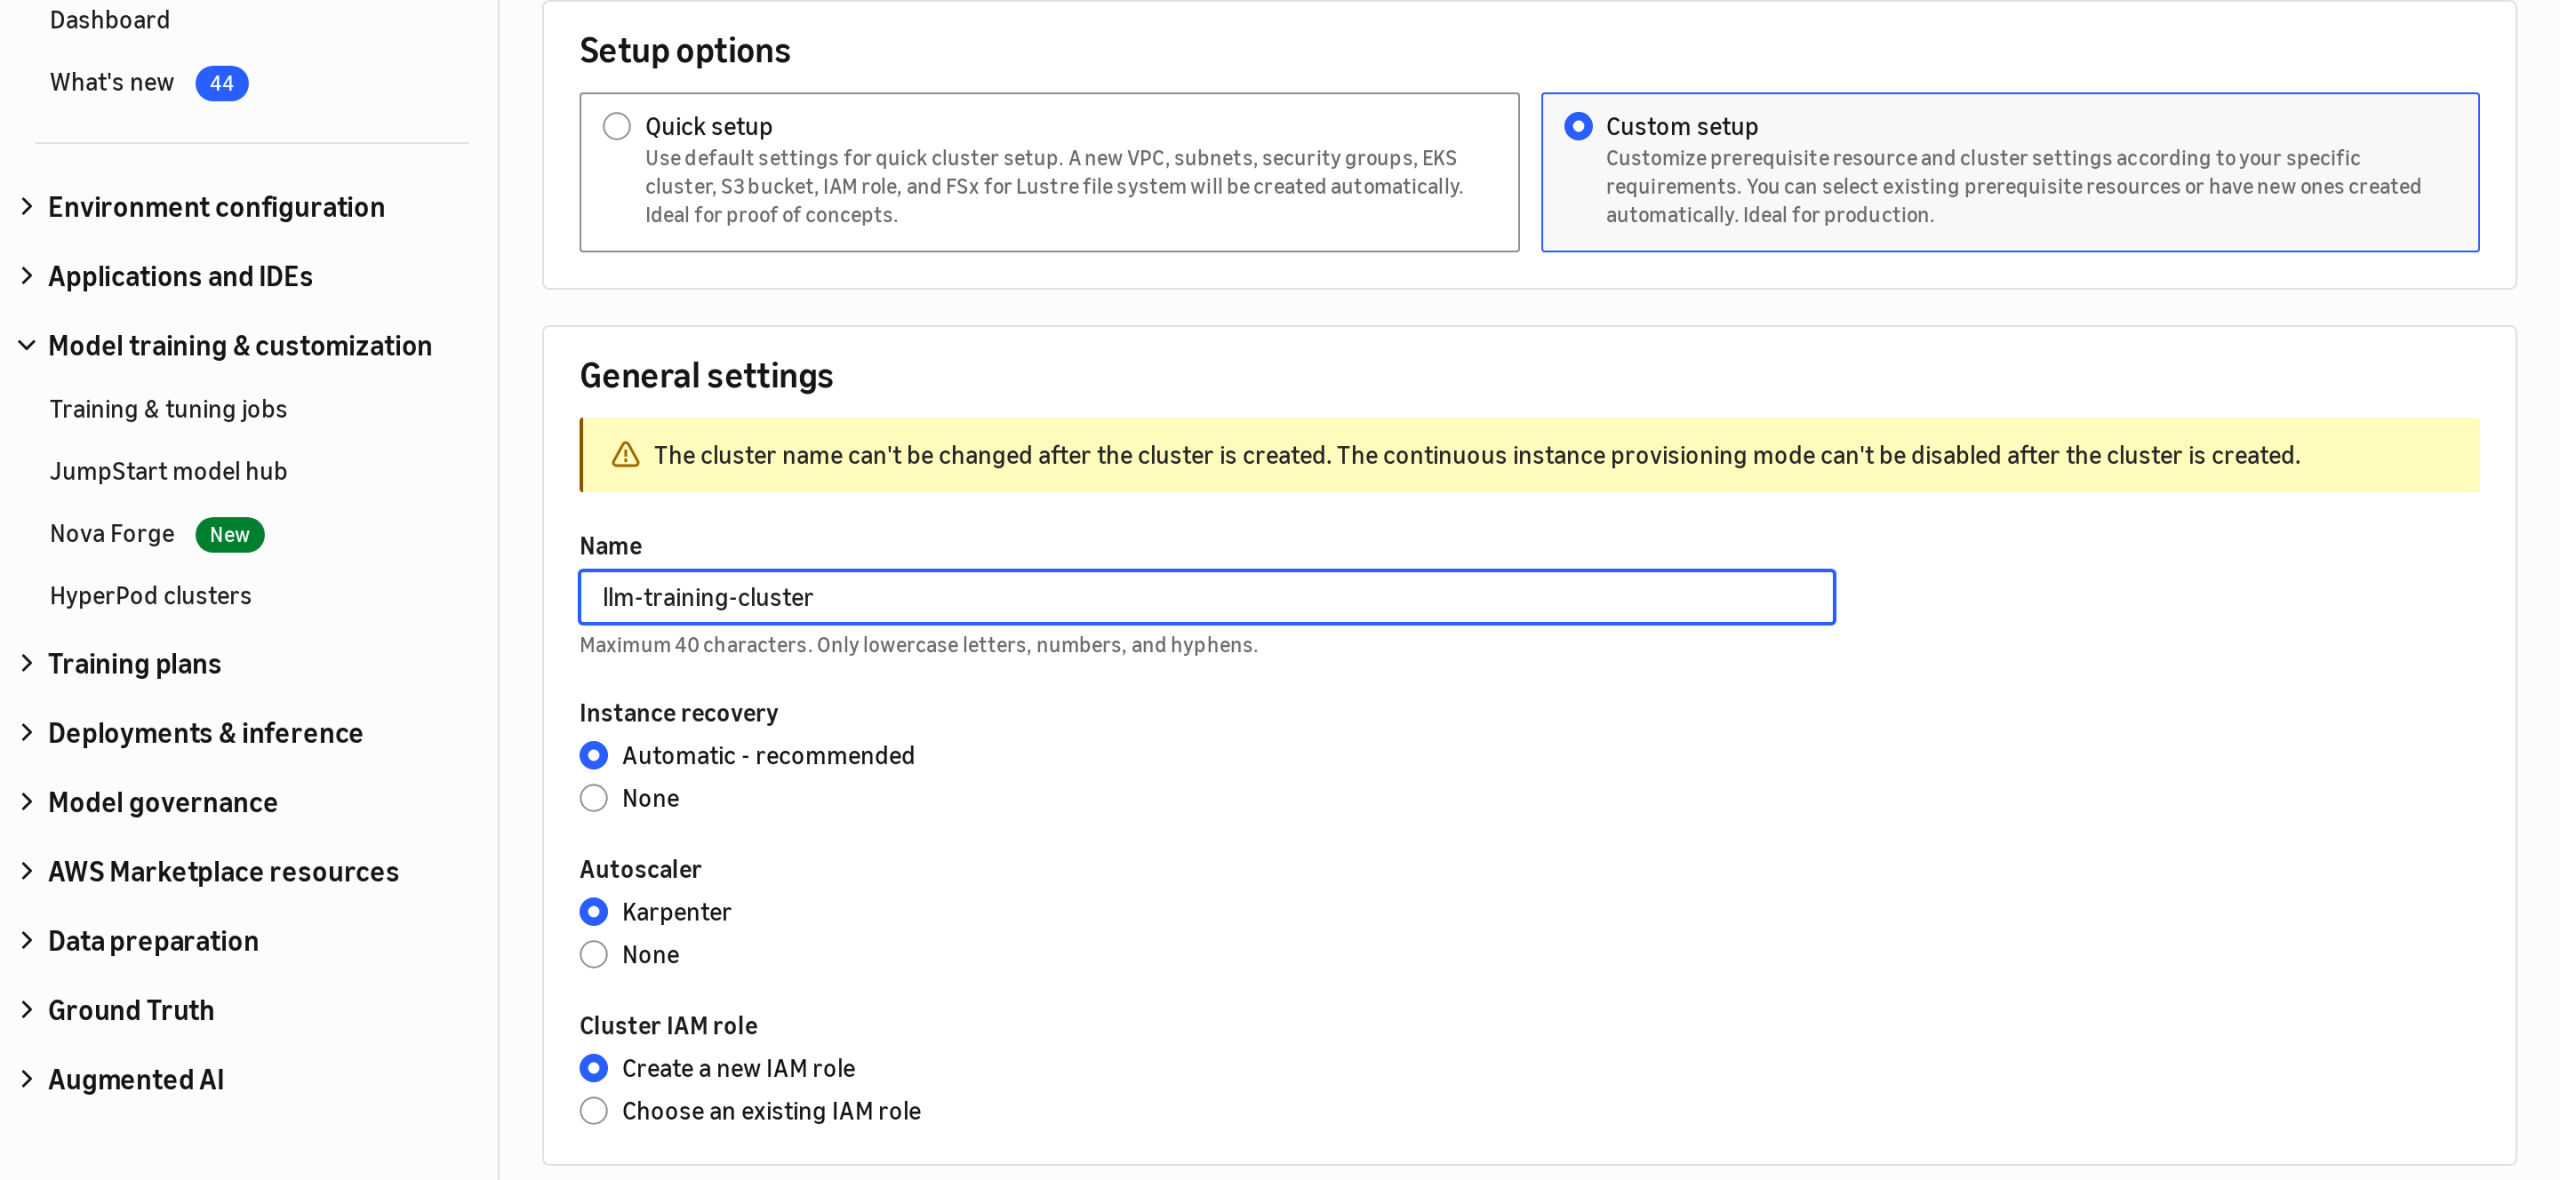
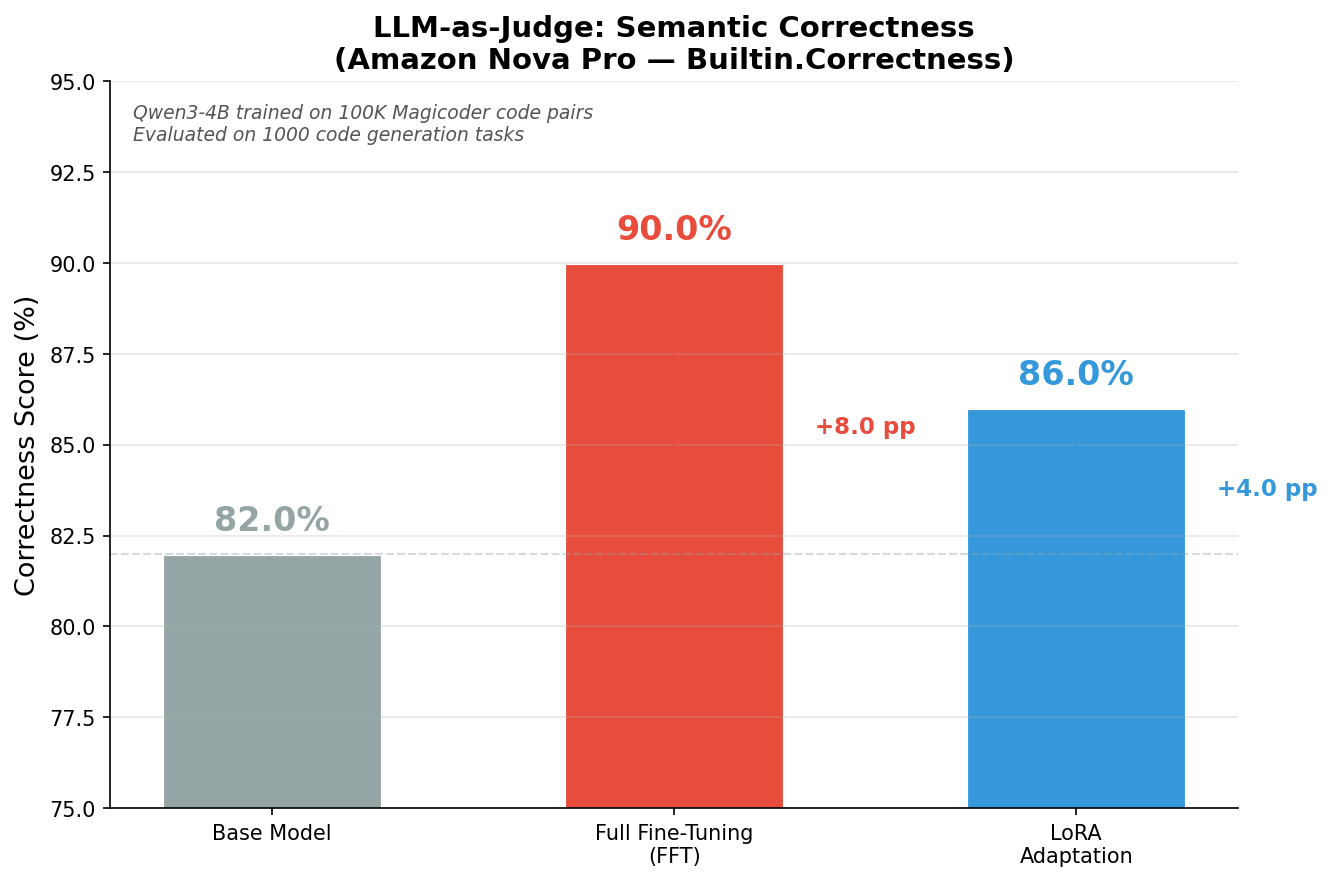
Full Fine-Tuning (FFT) on SageMaker AI Serverless Model Customization

Fine-tuning is the process of continuing to train a pretrained large language model (LLM) on a company’s own data so it adapts to a specific domain, task, or style rather than relying on general-purpose knowledge alone. For businesses, the value is twofold. A fine-tuned model delivers measurably better accuracy on domain-specific work while reducing costs: … Read more

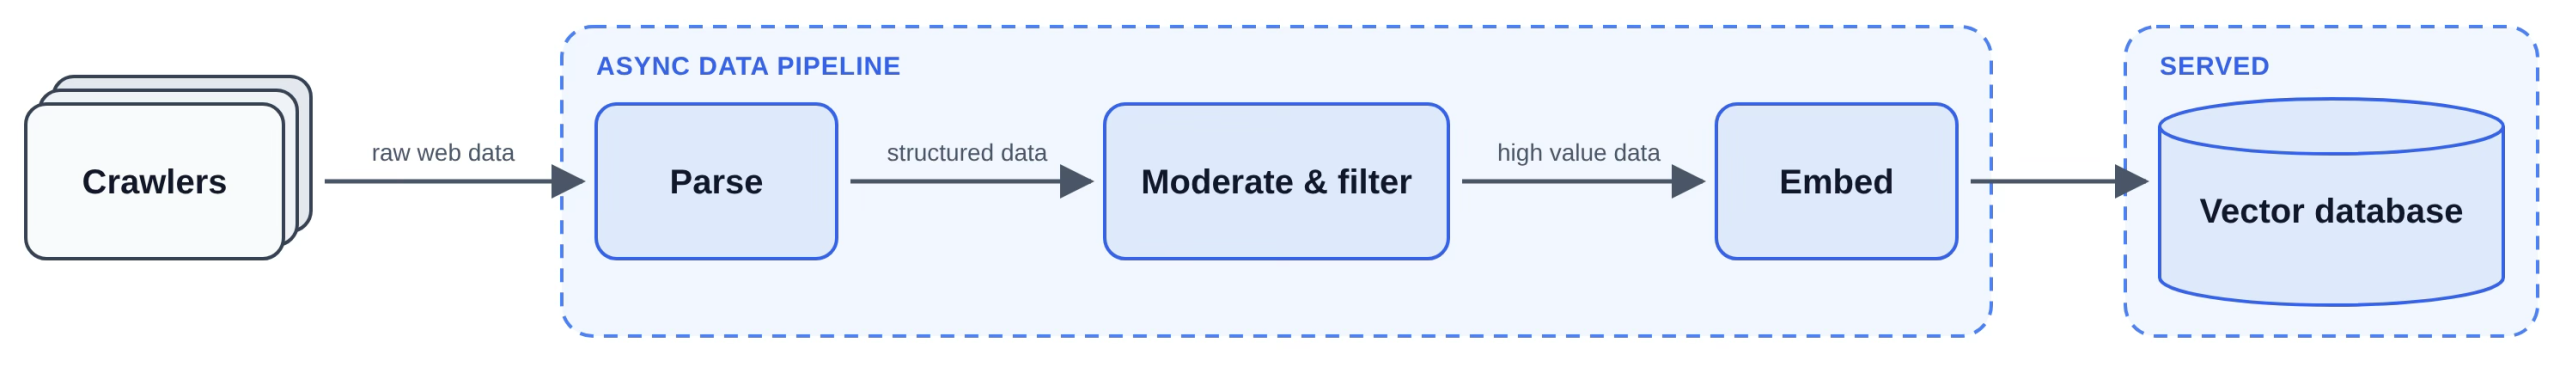
Exa boosts embedding throughput by 50% to index billions of documents on AWS AI chips

At Exa, we are building one of the few true web indexes by aggregating and serving knowledge from across the web, along with private and synthetic sources. We optimize the index for semantic search, grounding agents and humans in true, high-quality data. We use multi-tower semantic machine learning (ML) models to embed web data and … Read more

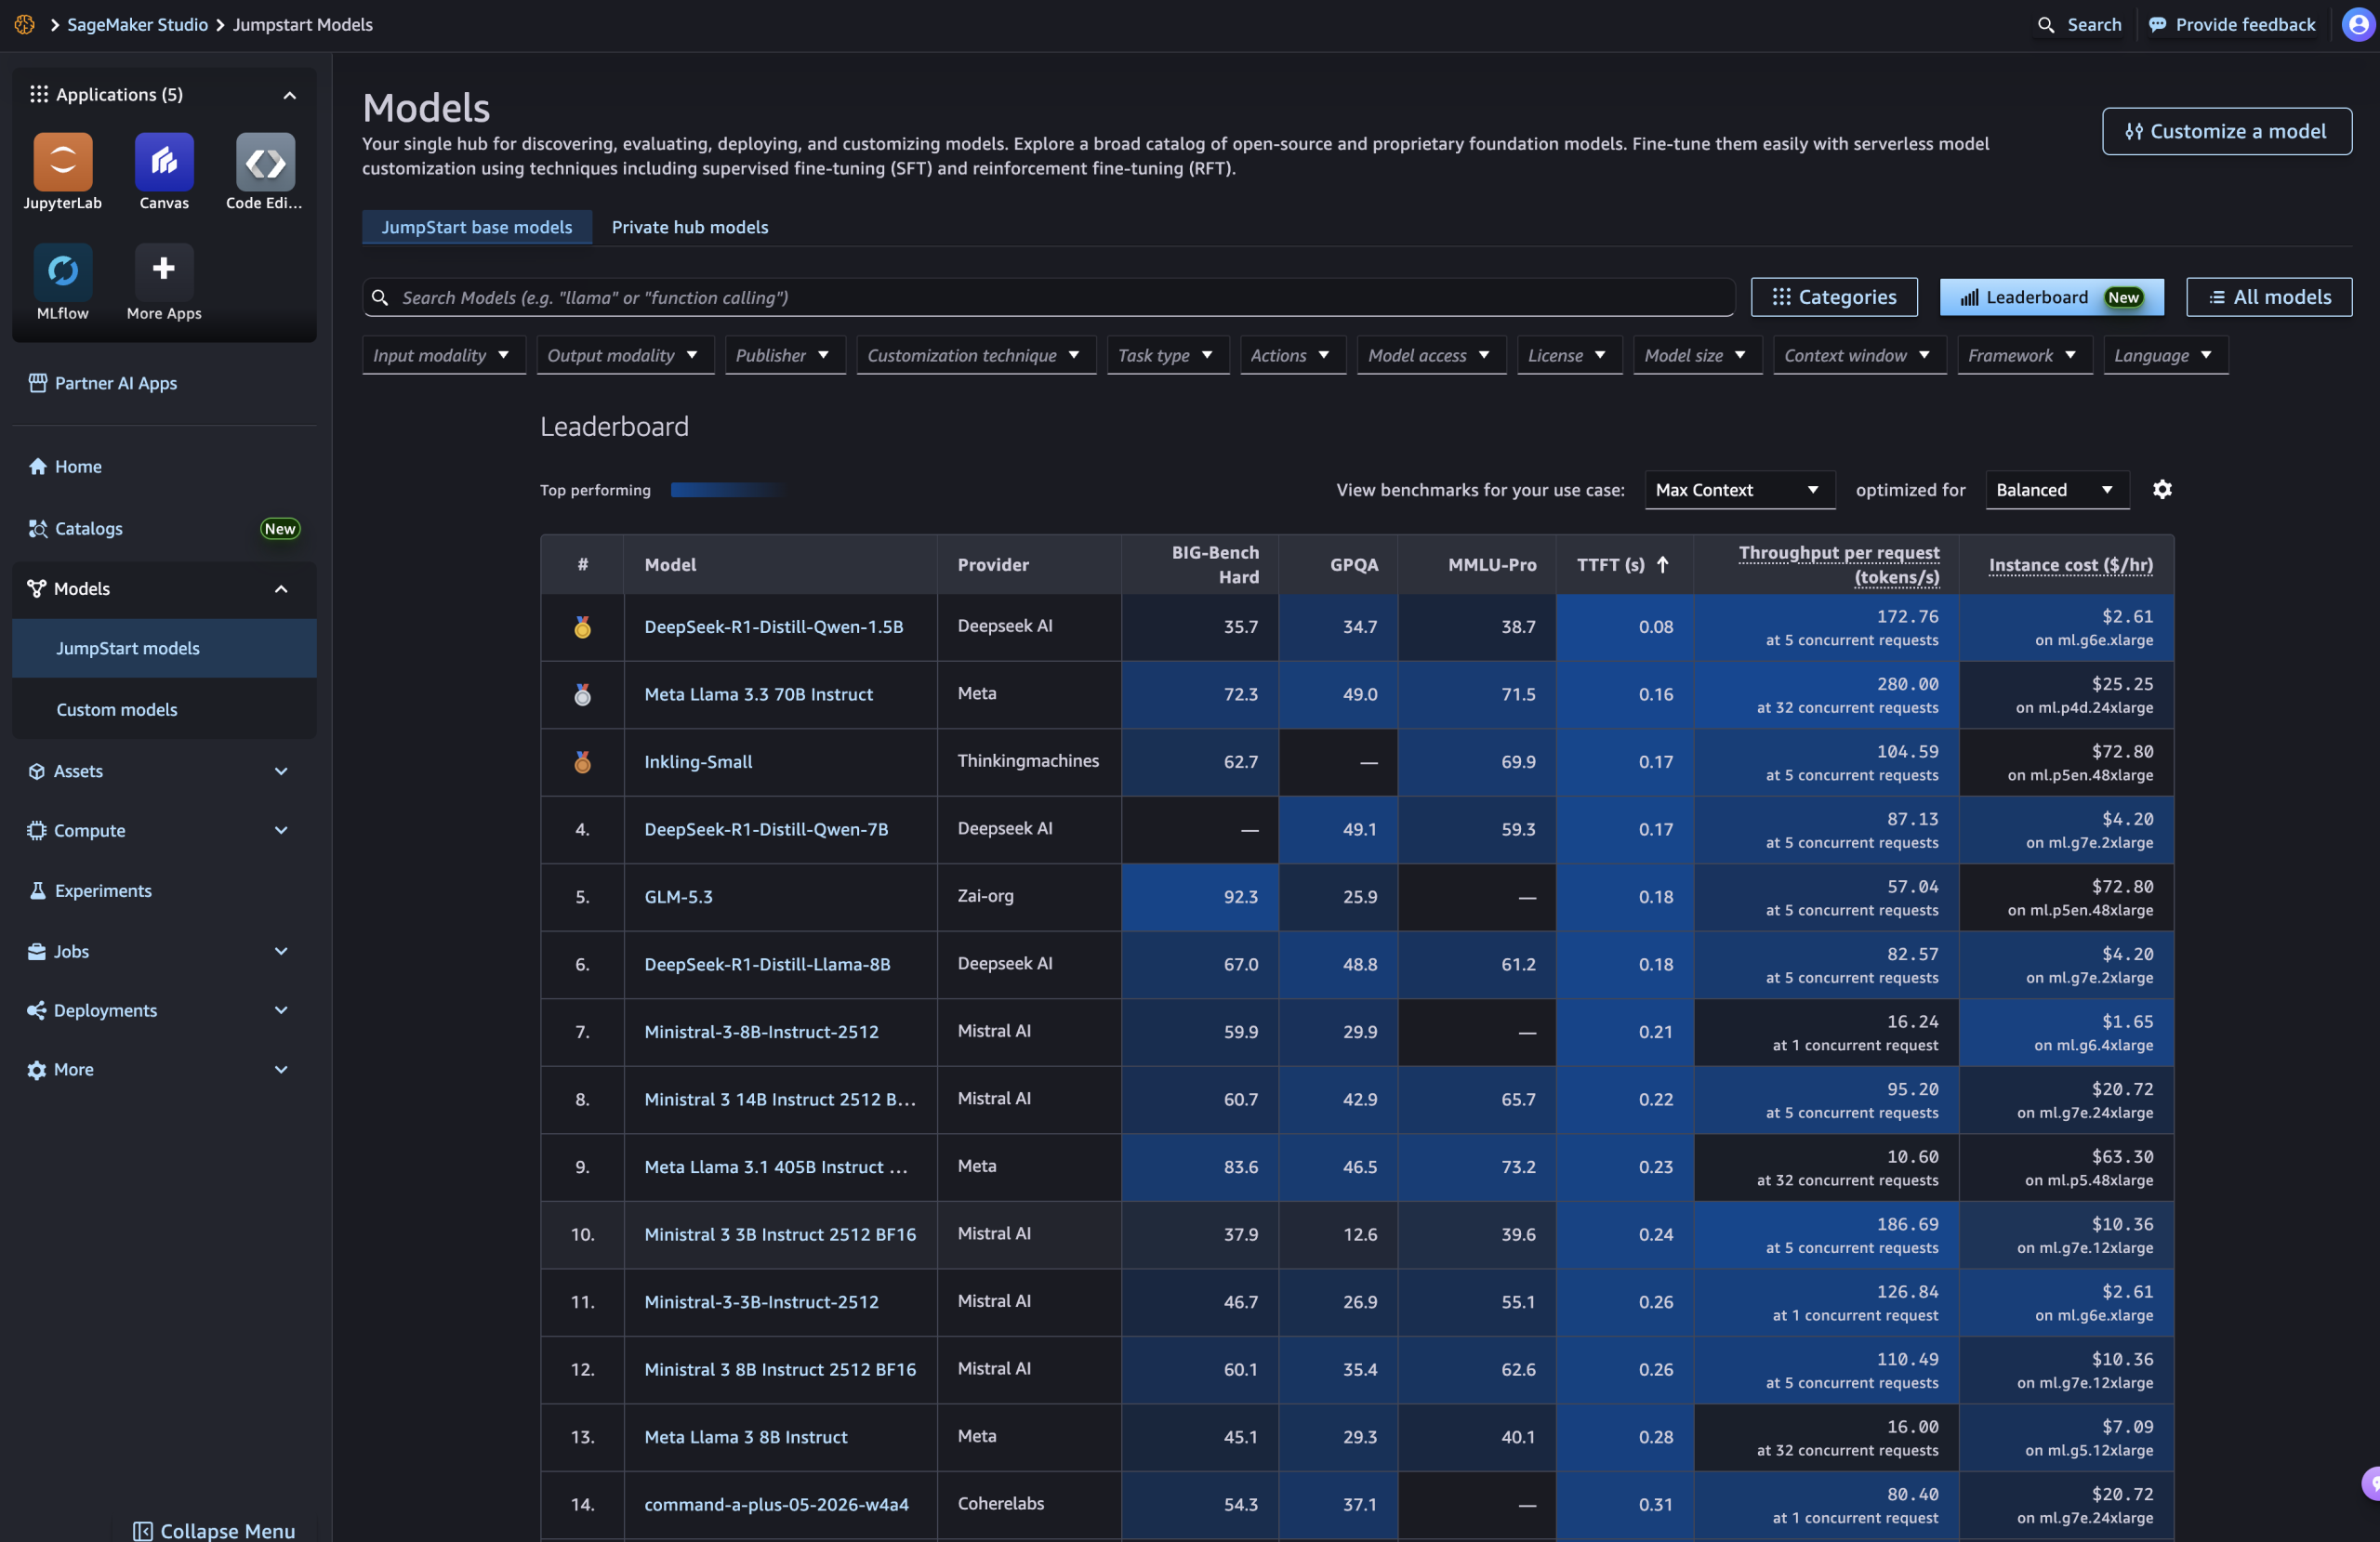
Introducing the Amazon SageMaker JumpStart Model Leaderboard

Amazon SageMaker JumpStart gives you hundreds of open-weight foundation models you can deploy quickly. That choice is powerful, but it also creates a real question: Which model should you start with? Comparing models usually means reading model cards one at a time and hunting for benchmark scores that different sources published under different conditions. Then … Read more

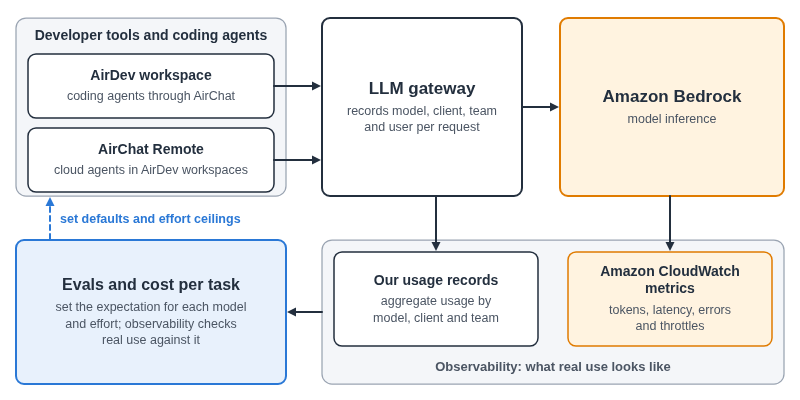
How Airbnb uses cost per task to operate coding agents on Amazon Bedrock

Amazon Bedrock provides access to foundation models from multiple providers through a common API, with AWS managing the model infrastructure. It integrates with AWS access controls and monitoring, and processes prompts, code, and model responses within AWS. As coding agents move into production, changes in models and usage can affect latency, capacity, and cost. Amazon … Read more

Design responsible AI controls for Amazon Aurora PostgreSQL

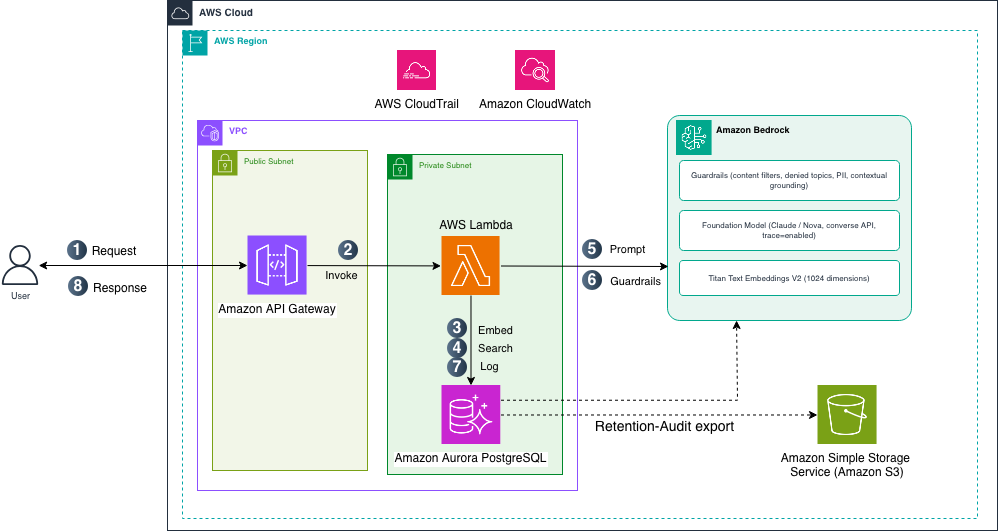
A customer support chatbot that queries historical tickets and knowledge base articles stored in Amazon Aurora PostgreSQL-Compatible Edition can deliver fast, context-aware answers. However, it also introduces challenges around privacy, accuracy, safety, and governance, especially when the underlying data contains sensitive customer information. In this post, we map the eight AWS Responsible AI (RAI) dimensions … Read more

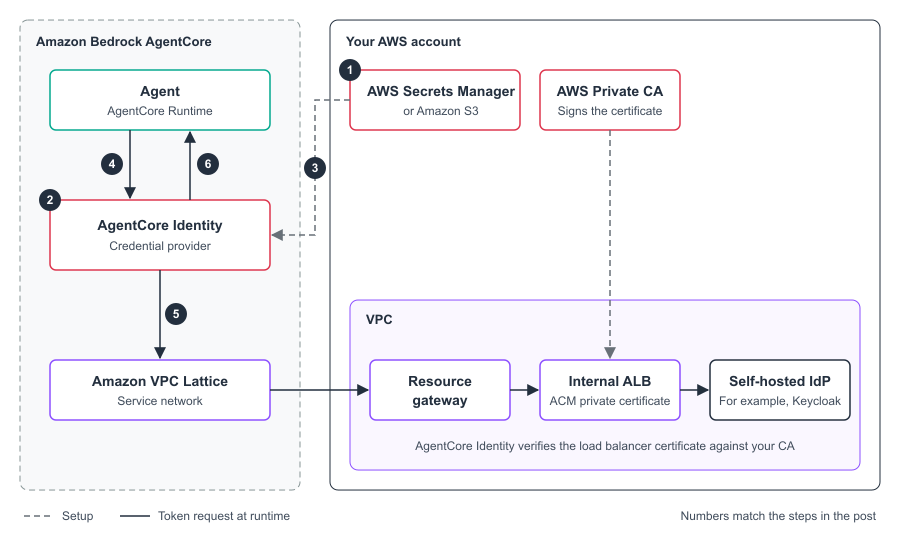
Private certificate authority support in Amazon Bedrock AgentCore Identity

Many teams that build applications self-host their identity provider (IdP), such as Keycloak or PingFederate, inside a private network. These IdPs usually present a TLS server certificate from a private certificate authority (CA). With private CA support in AgentCore Identity, a capability of Amazon Bedrock AgentCore, your agents can now connect to these IdPs while … Read more
How Salesforce is advancing global-scale model serving with cross-Region inference routing in Amazon SageMaker AI

Thanks to Amit Gupta, Senior Director- AI/ML and Mark Wang, Software Engineering PMTS from Salesforce for your contributions in the vision and partnership of cross-Region inference routing on SageMaker AI. Salesforce’s Agentforce Foundation team serves a wide variety of models for products across Salesforce, including Agentforce and the Salesforce Trust Layer, in 30+ global Regions. … Read more