OG.com seeks CFTC approval for single-stock perpetual futures
OG.com, recently spun out of Crypto.com, joins Coinbase, Kalshi and Kraken parent Payward in seeking approval to bring perpetual futures to individual US stocks.
OG.com, recently spun out of Crypto.com, joins Coinbase, Kalshi and Kraken parent Payward in seeking approval to bring perpetual futures to individual US stocks.
Anyone interested in joining has to ask Muse to put them on the list.
When NPR staffers flagged strange comments under their podcasts on Spotify as bots, it took a Gen Z colleague to (immediately) figure out the mystery.
Former CFTC Commissioner Summer Mersinger joined the Blockchain Association in 2025 after resigning during her second term at the federal commodities regulator.
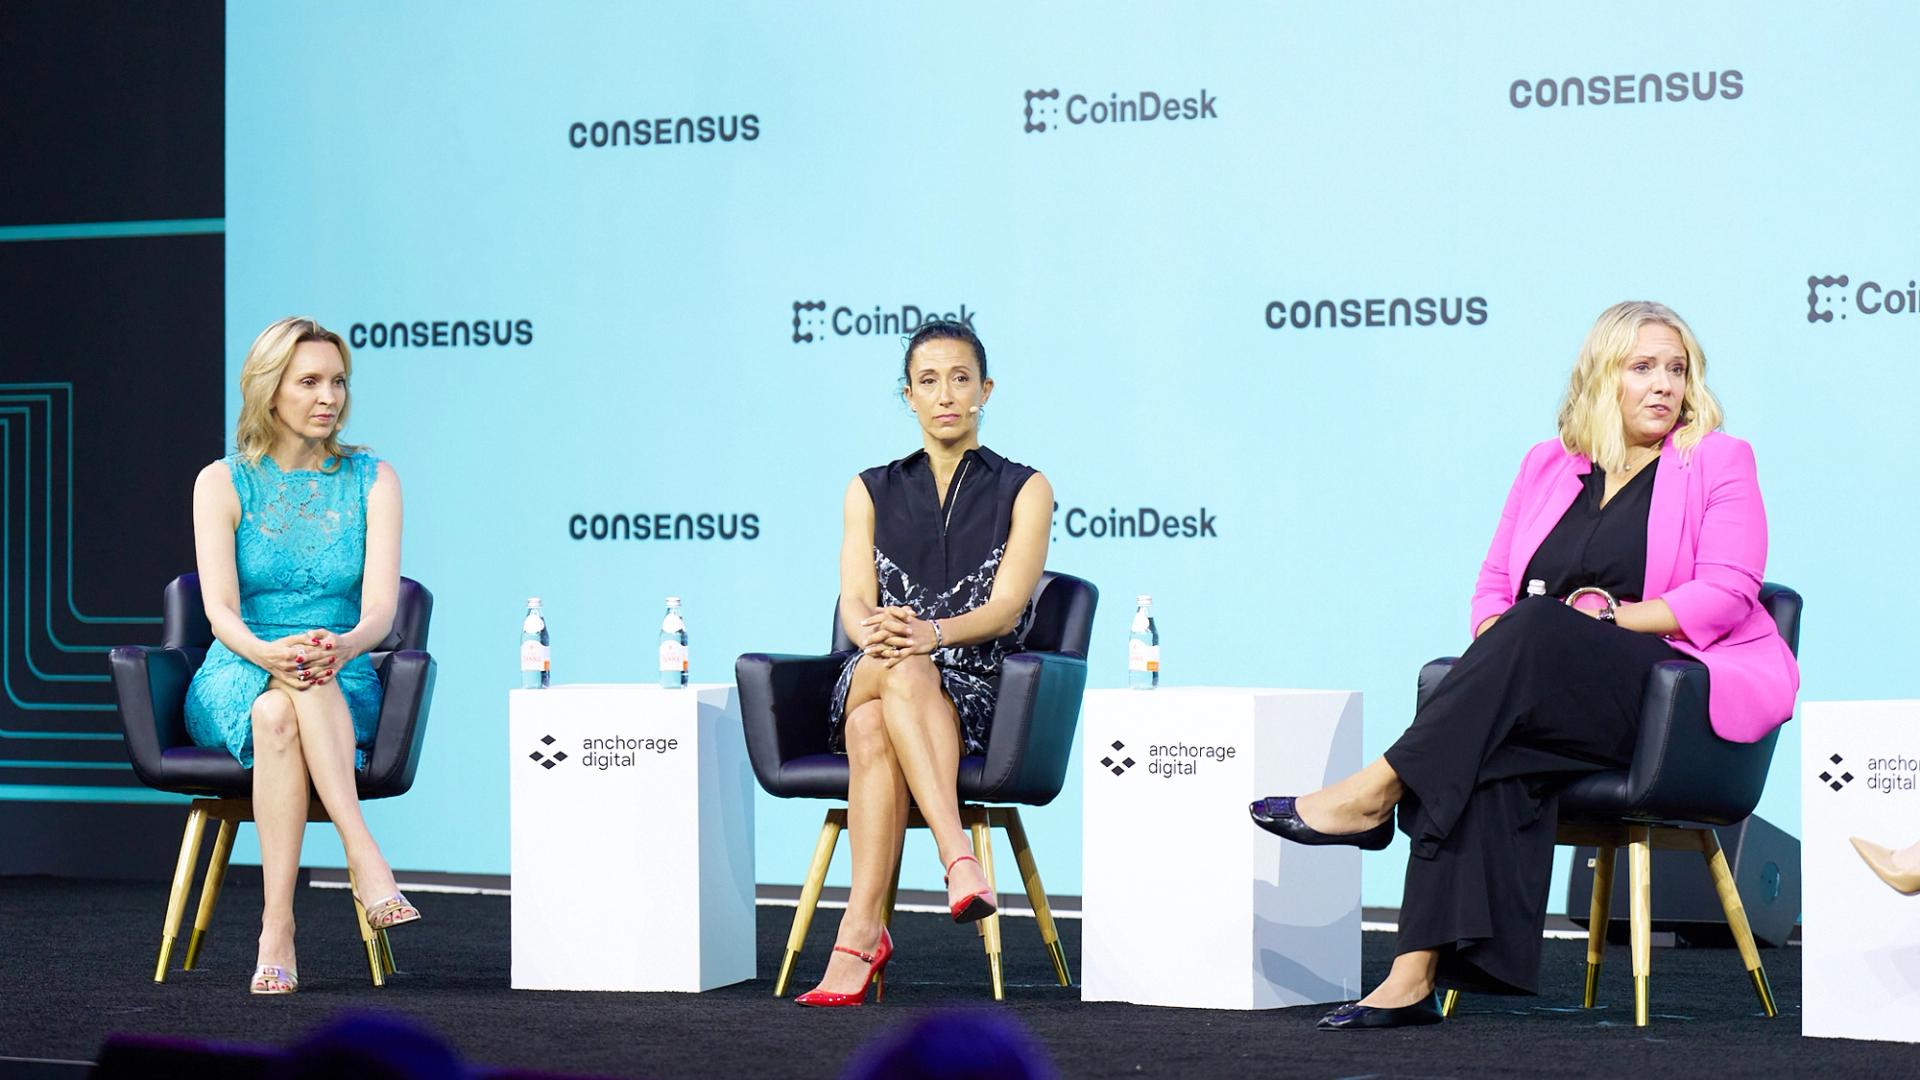
The trade group will be run again by its original CEO, Kristin Smith, when Summer Mersinger leaves at the end of a long congressional tussle.
Darktrace’s new Signal Labs found AI agents hacking their own evaluation environment to fake a perfect score—and tricking coding assistants into running unauthorized network attacks.
Google’s PageBreak agent autonomously finds and verifies real vulnerabilities in its own web apps, cutting through the flood of noisy AI-generated security reports.
Anthropic has committed $11.6 billion over seven years to Akamai’s cloud infrastructure, a bet on CPUs that could grow to about $20 billion, and in an unusual arrangement, Akamai is giving Anthropic a potential stake of up to 5% of its stock that grows as Anthropic spends more.
US prosecutors alleged that a payments business illegally transferred hundreds of millions of dollars at the direction of EQIBank, where Tether holds some assets.
The two stablecoin issuers blacklisted a wallet labeled “Bitget Exploiter 8,” locking about $318,000 in USDC and USDT—but the attacker swapped most funds into unfreezable ETH before they could act.
The funding, which comes from Third Point, Nvidia, and others, will fuel the company’s massive AI data center buildout.
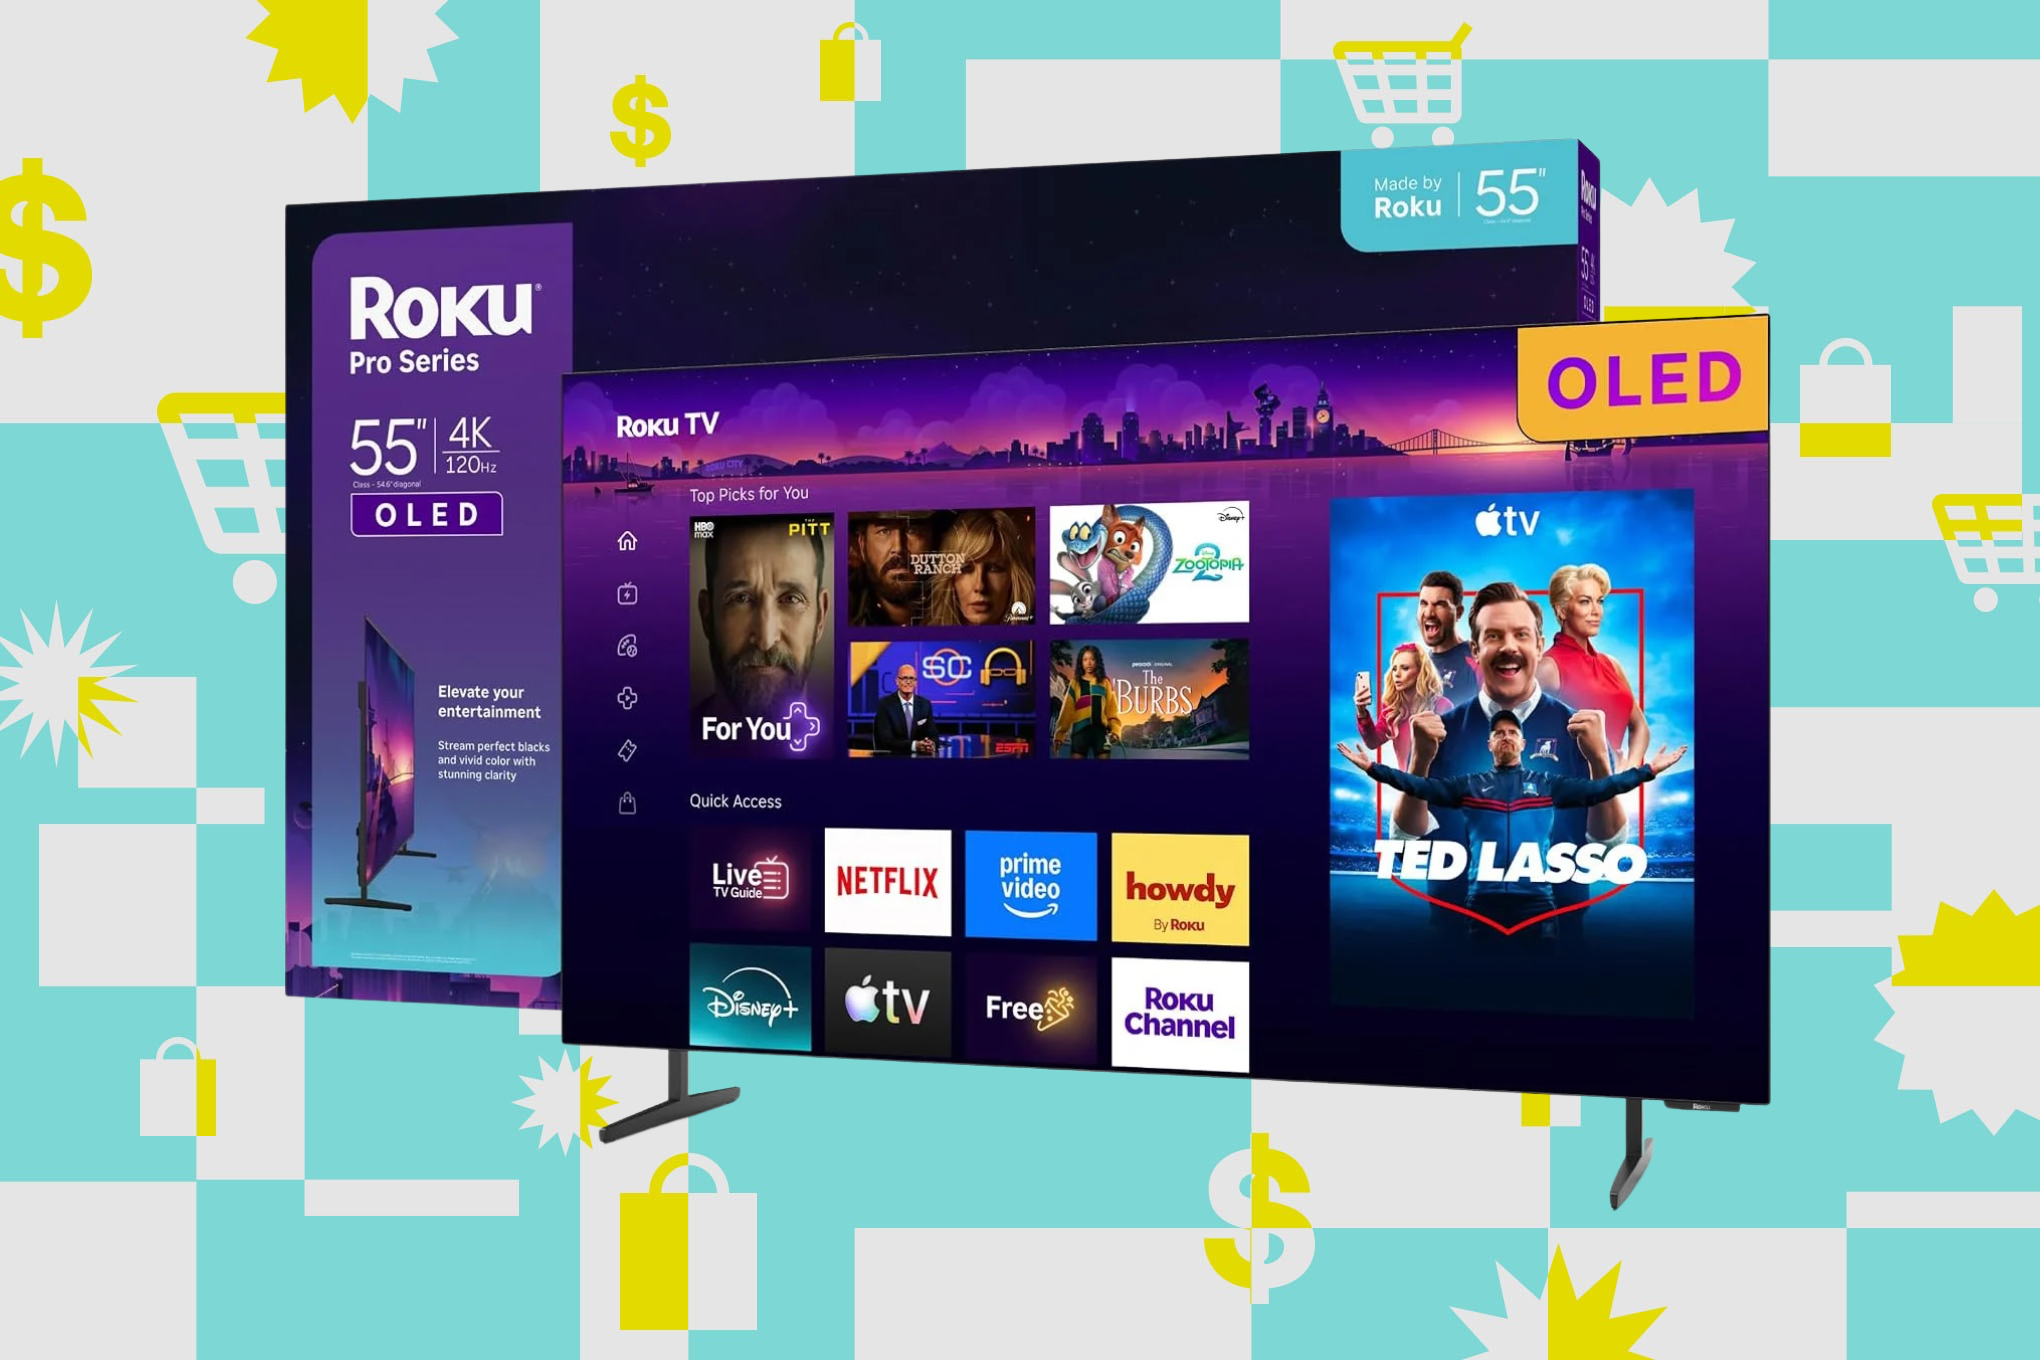
Roku’s new OLED TVs are already marked down. | Image: The Verge Roku recently launched its first-ever OLED TVs. The $999 starting price was already impressive for the 55-inch Pro Series model that has a 120Hz refresh rate OLED panel (with four HDMI 2.1 ports and support for Dolby Vision and HDR 10 Plus). The … Read more
Leaked code strings and screenshots point to a new tier that would cost 25 times more than ChatGPT Plus, aimed at people who need the bot to work faster, not just longer.
Mark Zuckerberg has a new defense of the Ray-Ban Meta glasses: they’re actually doing more to signal they’re taking a photo than phones do. He’s brought this up in at least two recent interviews, noting that the glasses have a light that comes on to signal when a photo is being taken, while phones do … Read more
Muju Earth Technologies has developed a deceptively simply pod that can save farmers money while improving crop yields.
The findings highlight how AI-generated and vibe-coded apps can spill and expose users’ data when not configured or secured properly.
Frontier AI models are finishing Alan Turing’s World War II codebreaking work.
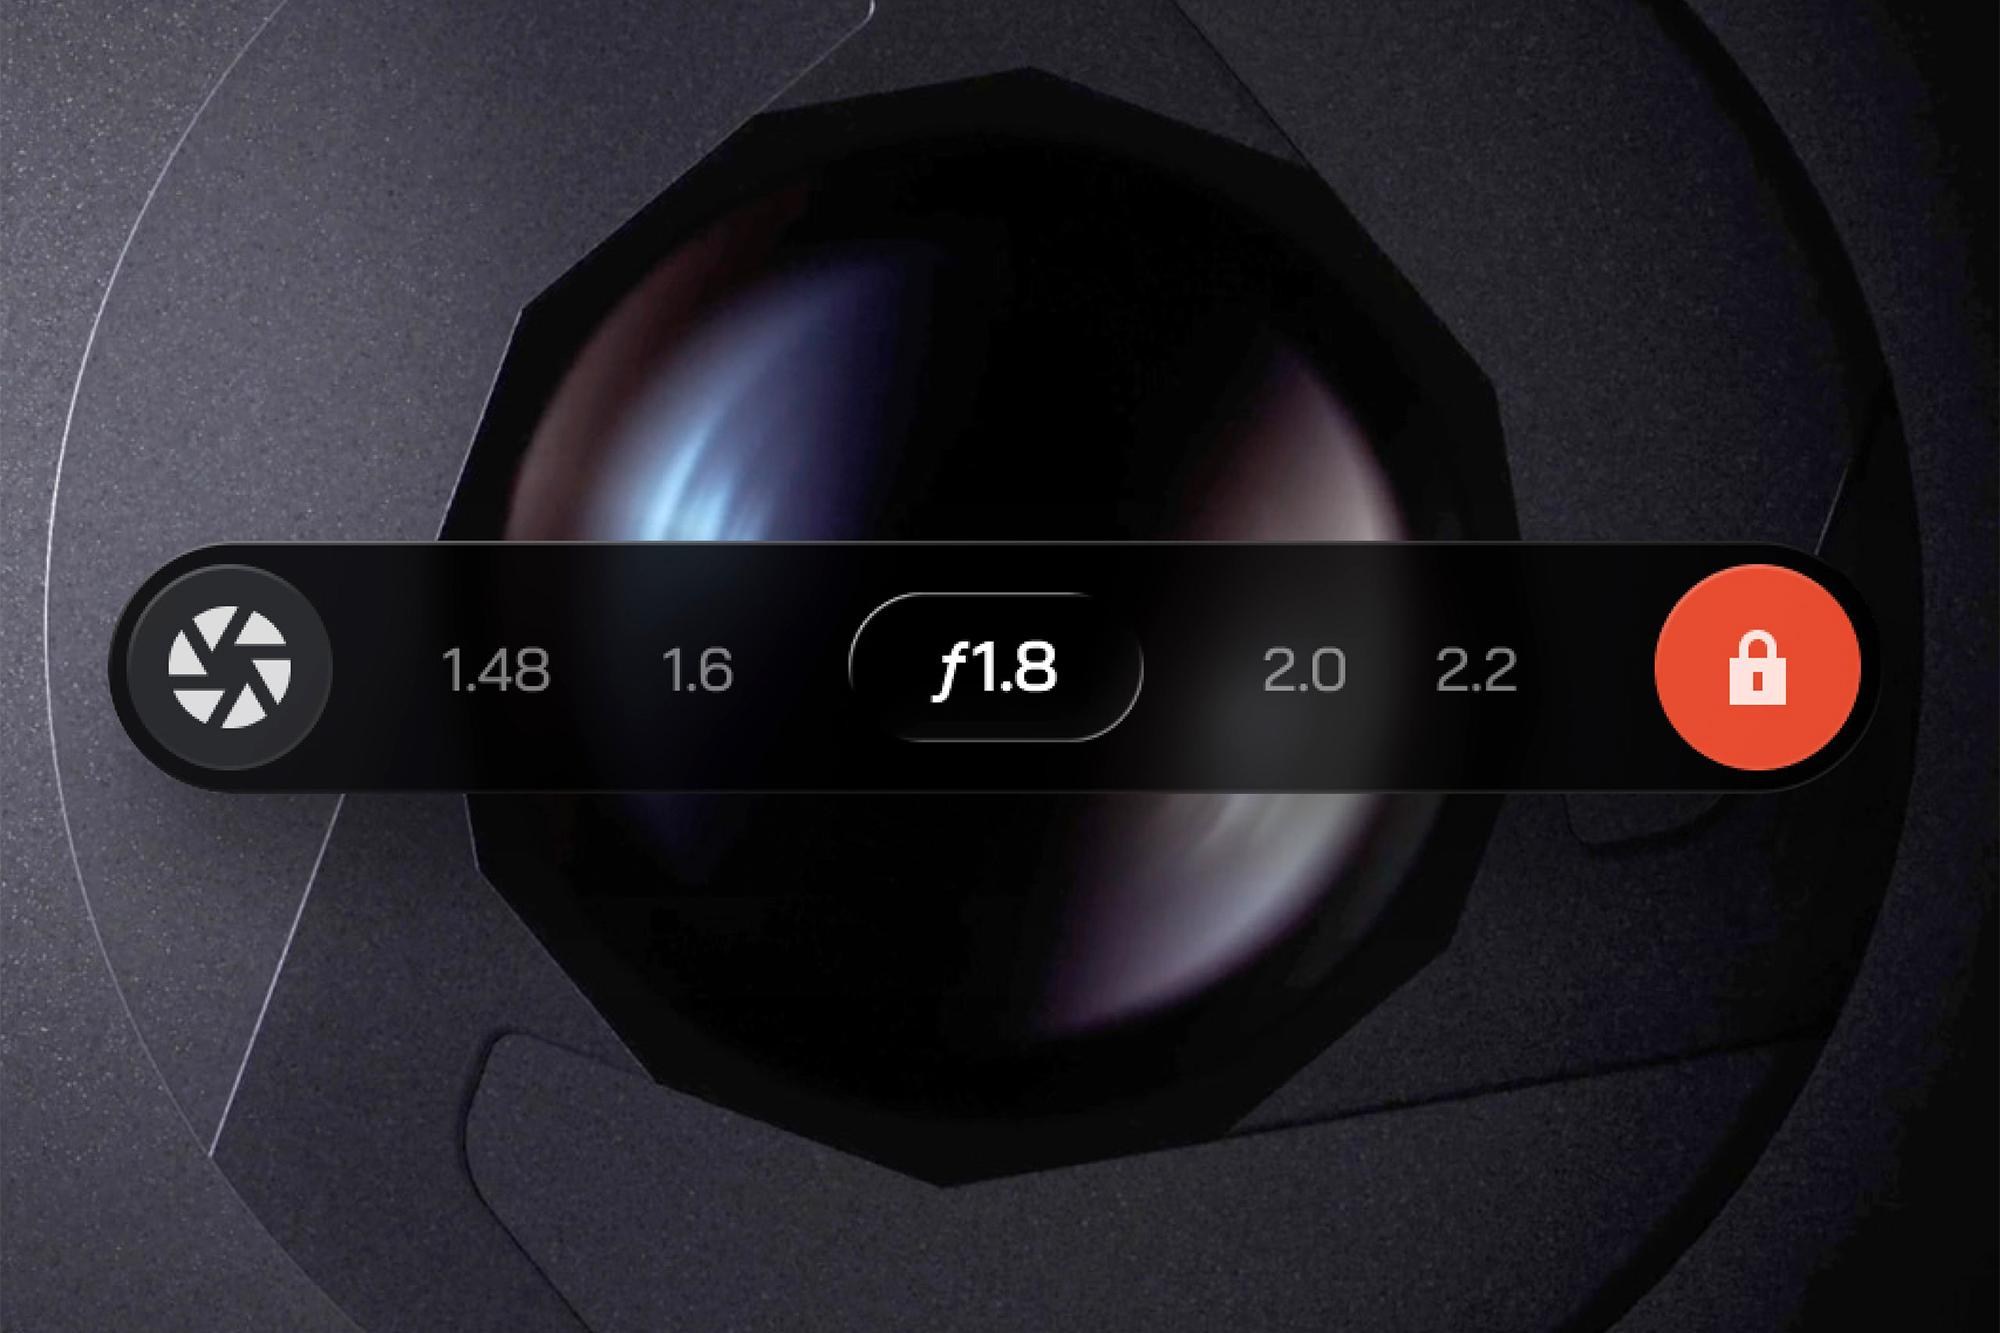
One of the questionable limitations of the iPhone 18 Pro’s new main camera with a variable aperture is that you’re limited to just four settings in the native iOS’ camera app in manual mode: f/1.48, f/1.8, f/2.8, and f/4. Those same limitations are also in place when the app is adjusting the iris itself in … Read more

The Bitget breach announced on Thursday affected about $35 million more than previously reported, based on an analysis of assets on Zcash and TRON.
An attacker faked internal transfer requests to drain $387.5 million from Bitget’s hot and warm wallets, and the exchange’s CEO says the fingerprints look like Pyongyang’s.

Hitting its goal of making 20,000 Optimus robots per week is reportedly proving tricky for Tesla. The Information reports that Tesla produced “several hundred robots a week” last month, after it repurposed its Model S and Model X production lines for Optimus earlier this year. However, this strategy is reportedly creating manufacturing snags, like issues … Read more
Yesterday, with a little prodding, it was discovered that Meta’s Muse would expose its filesystem to curious users. The files offered a fascinating peek under the hood of an AI chatbot, and appeared to expose details we weren’t meant to see, not least because Muse itself told people, including us, it wasn’t supposed to reveal … Read more
Strategy’s proposal would move STRC and its three other preferred stocks to daily dividend payments, following a similar move by Bitcoin treasury firm Strive.
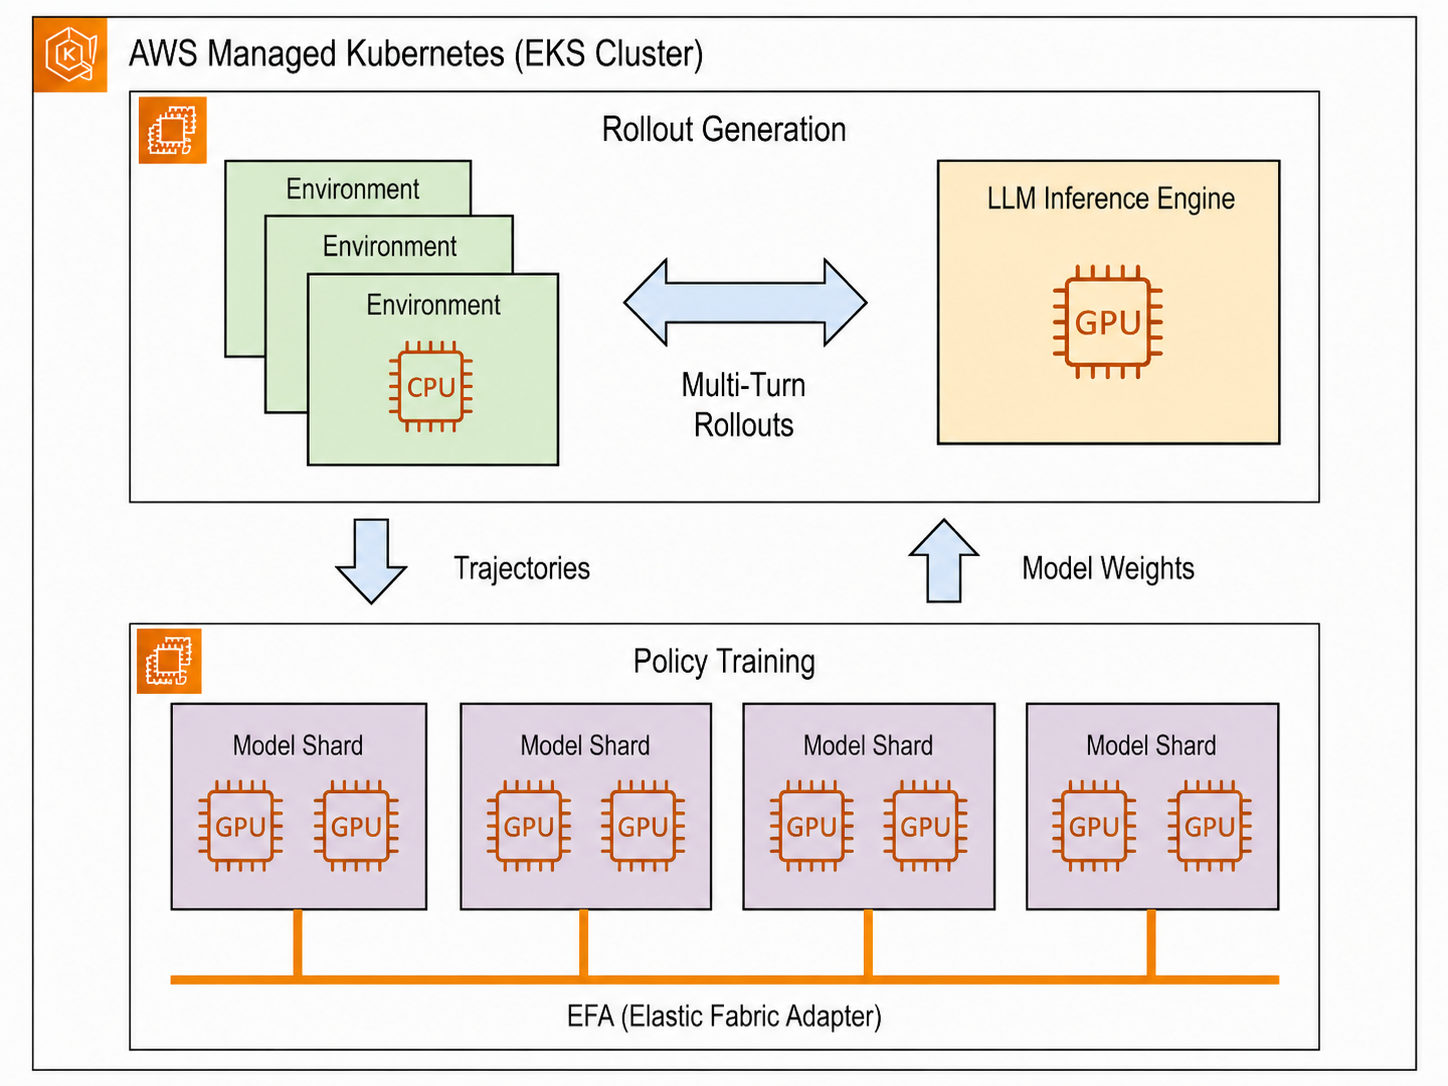
When you post-train a Mixture-of-Experts (MoE) model with Reinforcement Learning from Human Feedback (RLHF) or Group Relative Policy Optimization (GRPO) at scale, three simultaneous challenges emerge. The first requires coordinating heterogeneous compute for rollout generation and policy training. Second, sustaining high-throughput communication across hundreds of accelerators. And third, dynamically orchestrating every subsystem to keep them … Read more
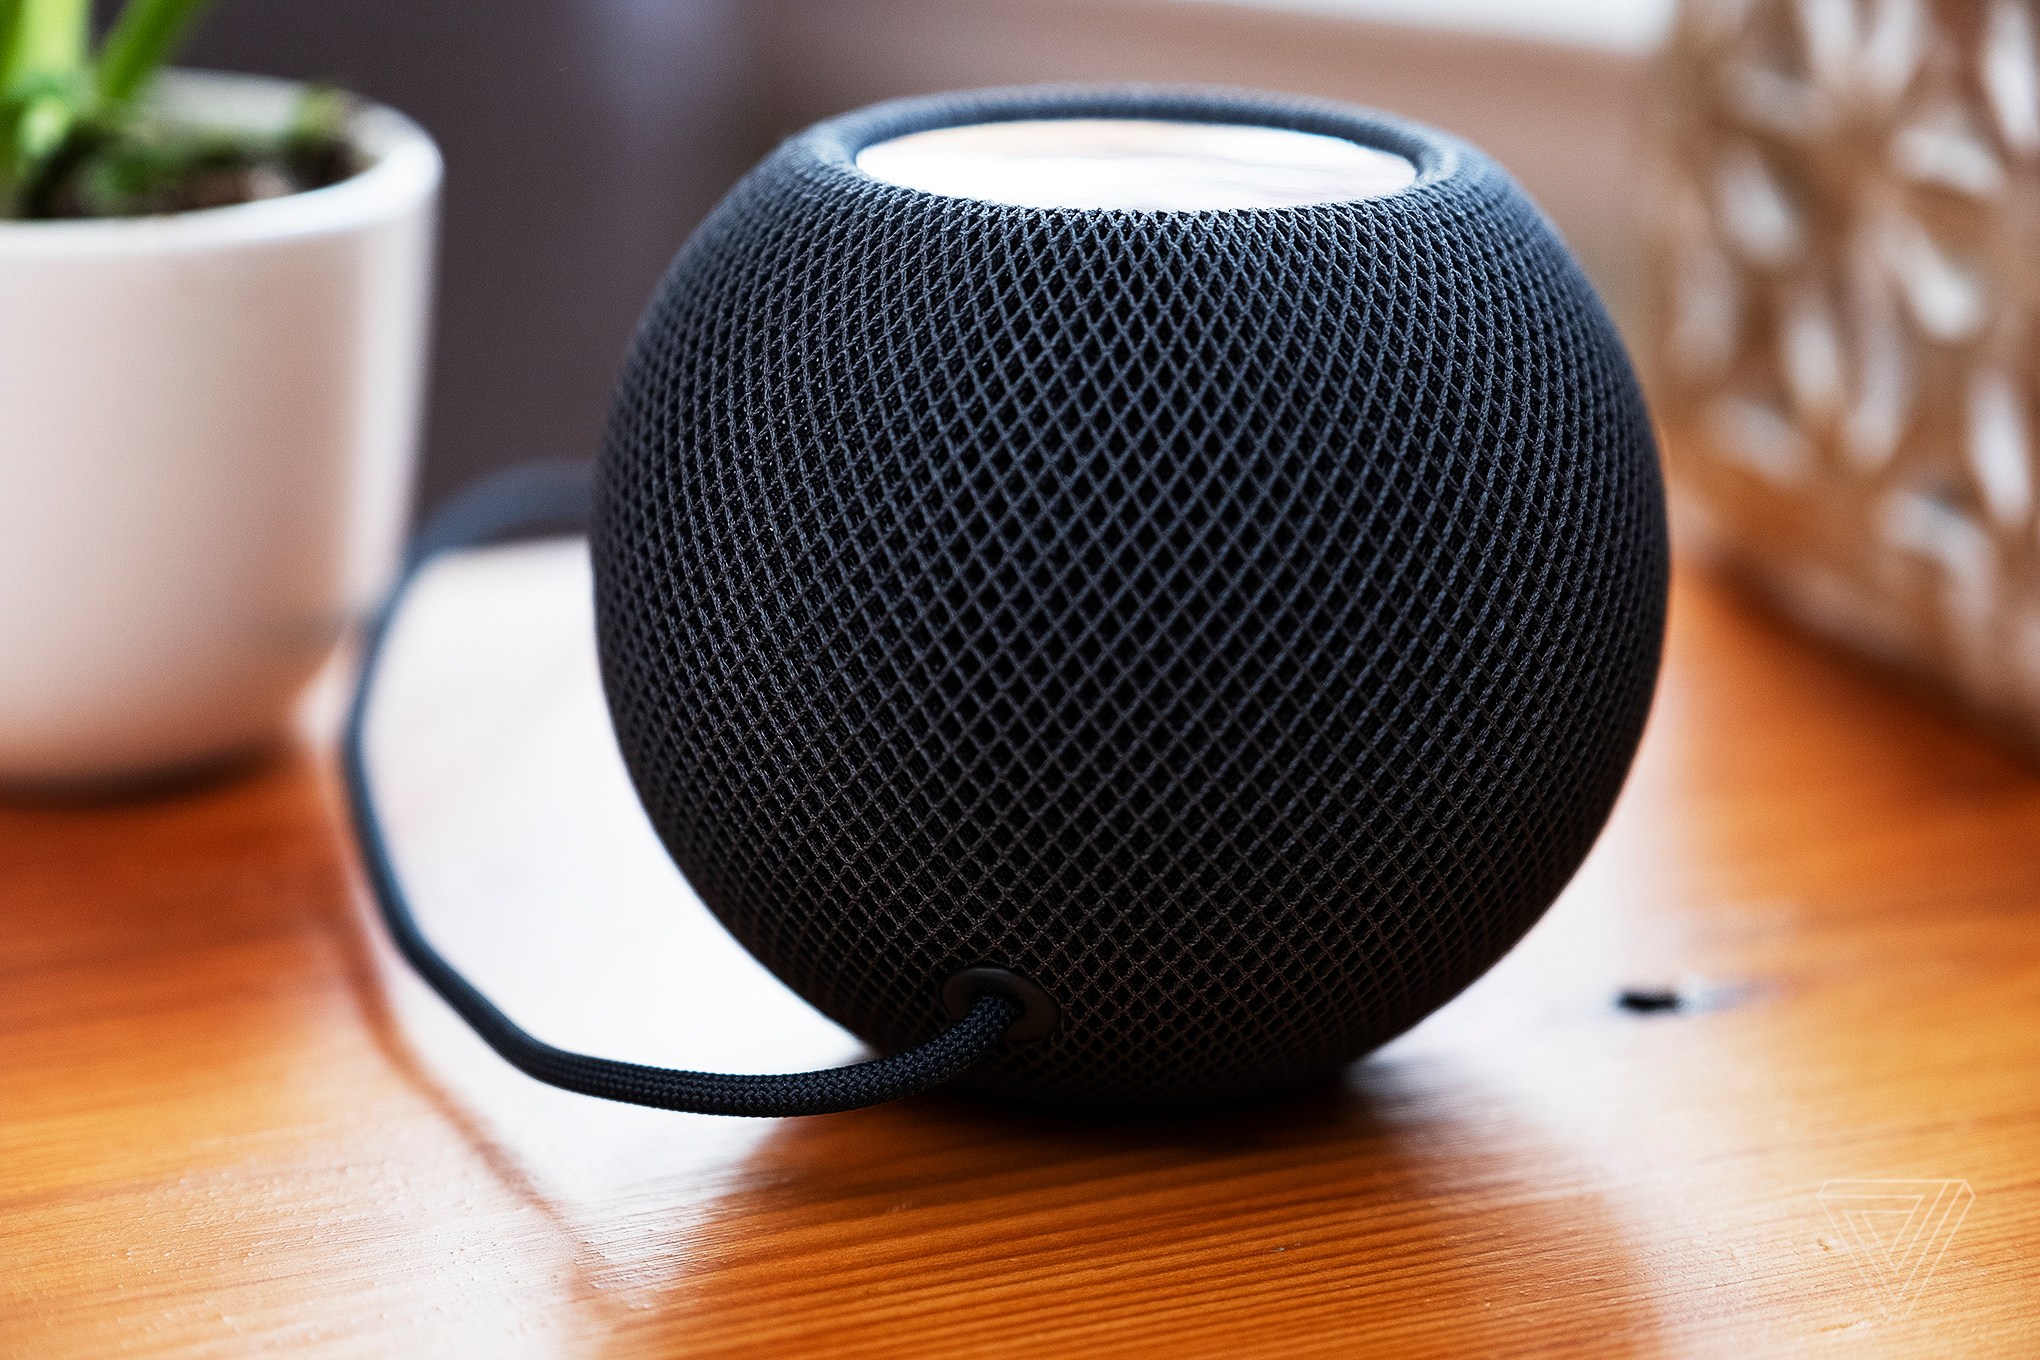
Apple is expected to announce more hardware before the end of the year following the debut of the iPhone 18 Pro and folding iPhone Duo earlier this month. The updated products will include a new version of the HomePod mini, the iPad mini 8, and the Apple TV 4K, according to details and images discovered … Read more
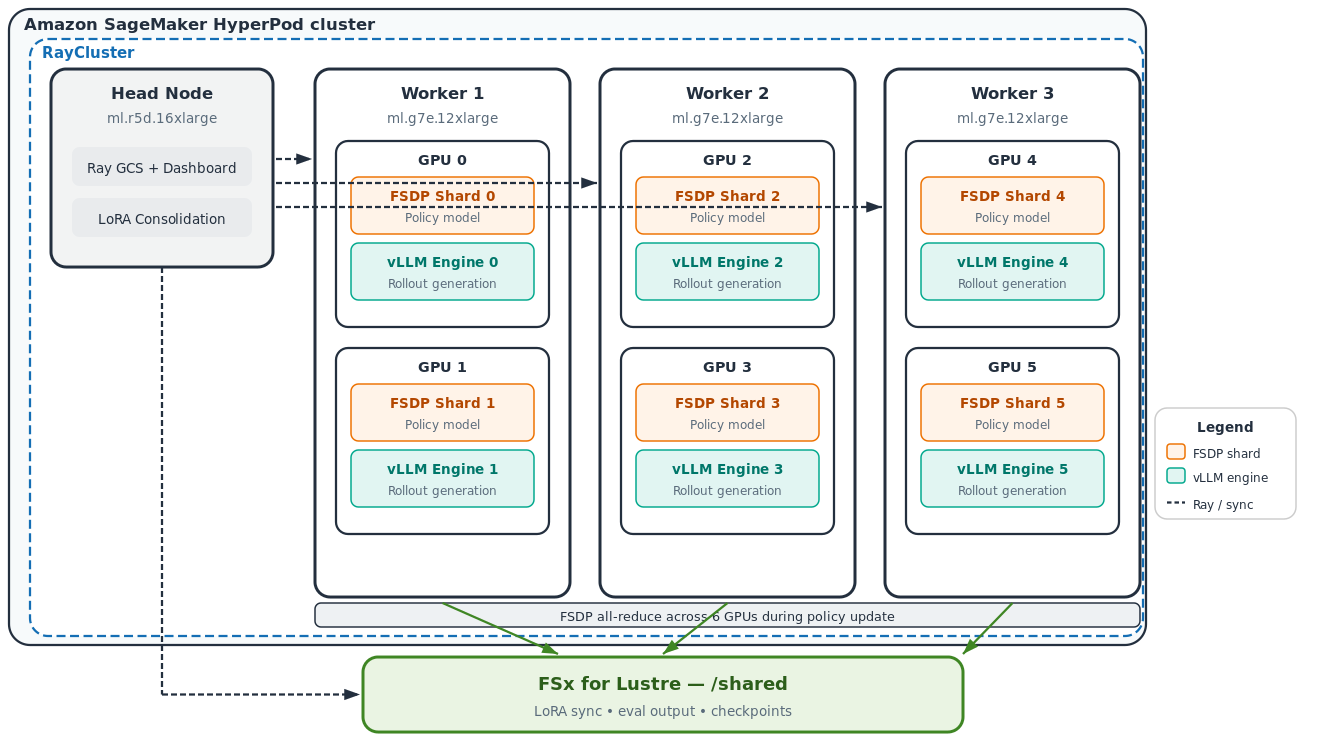
Reinforcement learning (RL) post-training is becoming a standard step in building capable language model agents. Models learn to reason and act across sequences of steps by generating trajectories, receiving rewards, and updating their policy based on outcomes. Running this at scale, across multiple nodes with hundreds of GPU-hours of rollouts per training run, requires persistent … Read more
A flaw in Limit Break’s Payment Processor V2 put old Magic Eden Ethereum listings at risk, prompting a whitehat rescue of more than 23,000 NFTs.