Stop guessing auto scaling targets for TTS on Amazon SageMaker AI
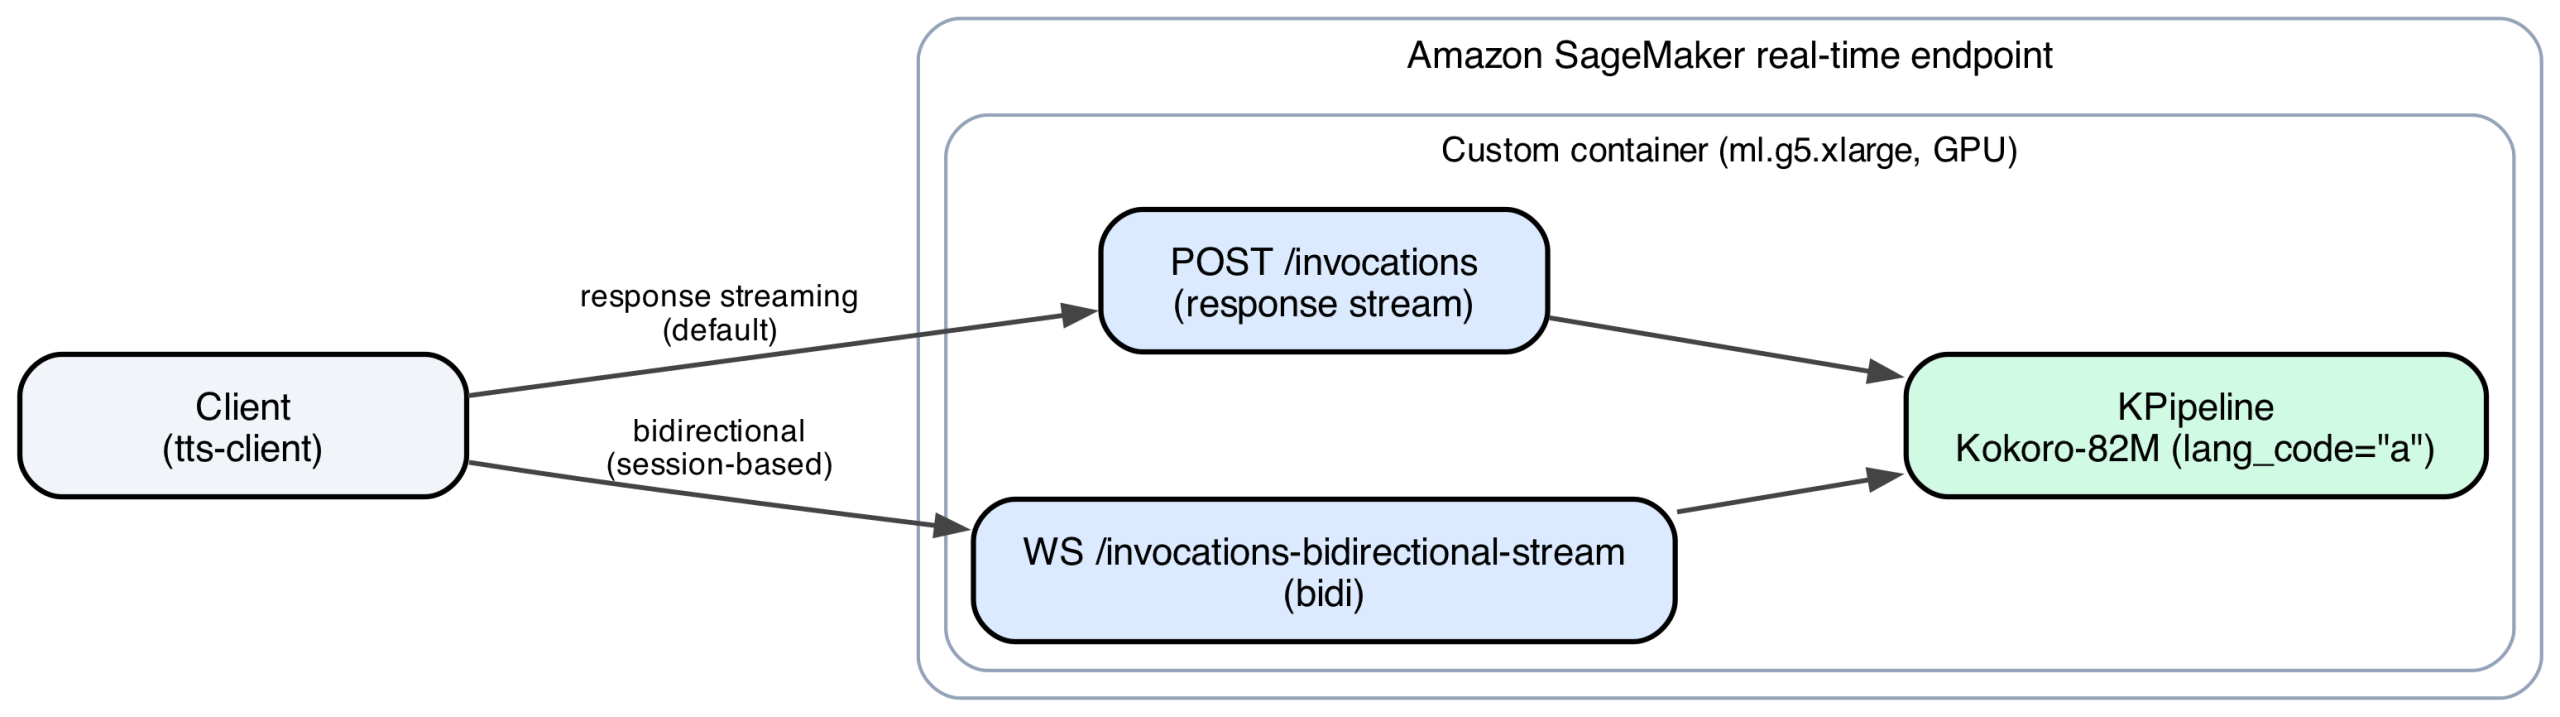
A traffic spike hits your self-hosted text-to-speech (TTS) endpoint, and requests start queueing. Latency climbs past your service level objective (SLO) right when the most callers are listening. The auto scaling policy behind that endpoint was supposed to prevent this, but the target value it scales on was a guess, and guesses like that fail … Read more
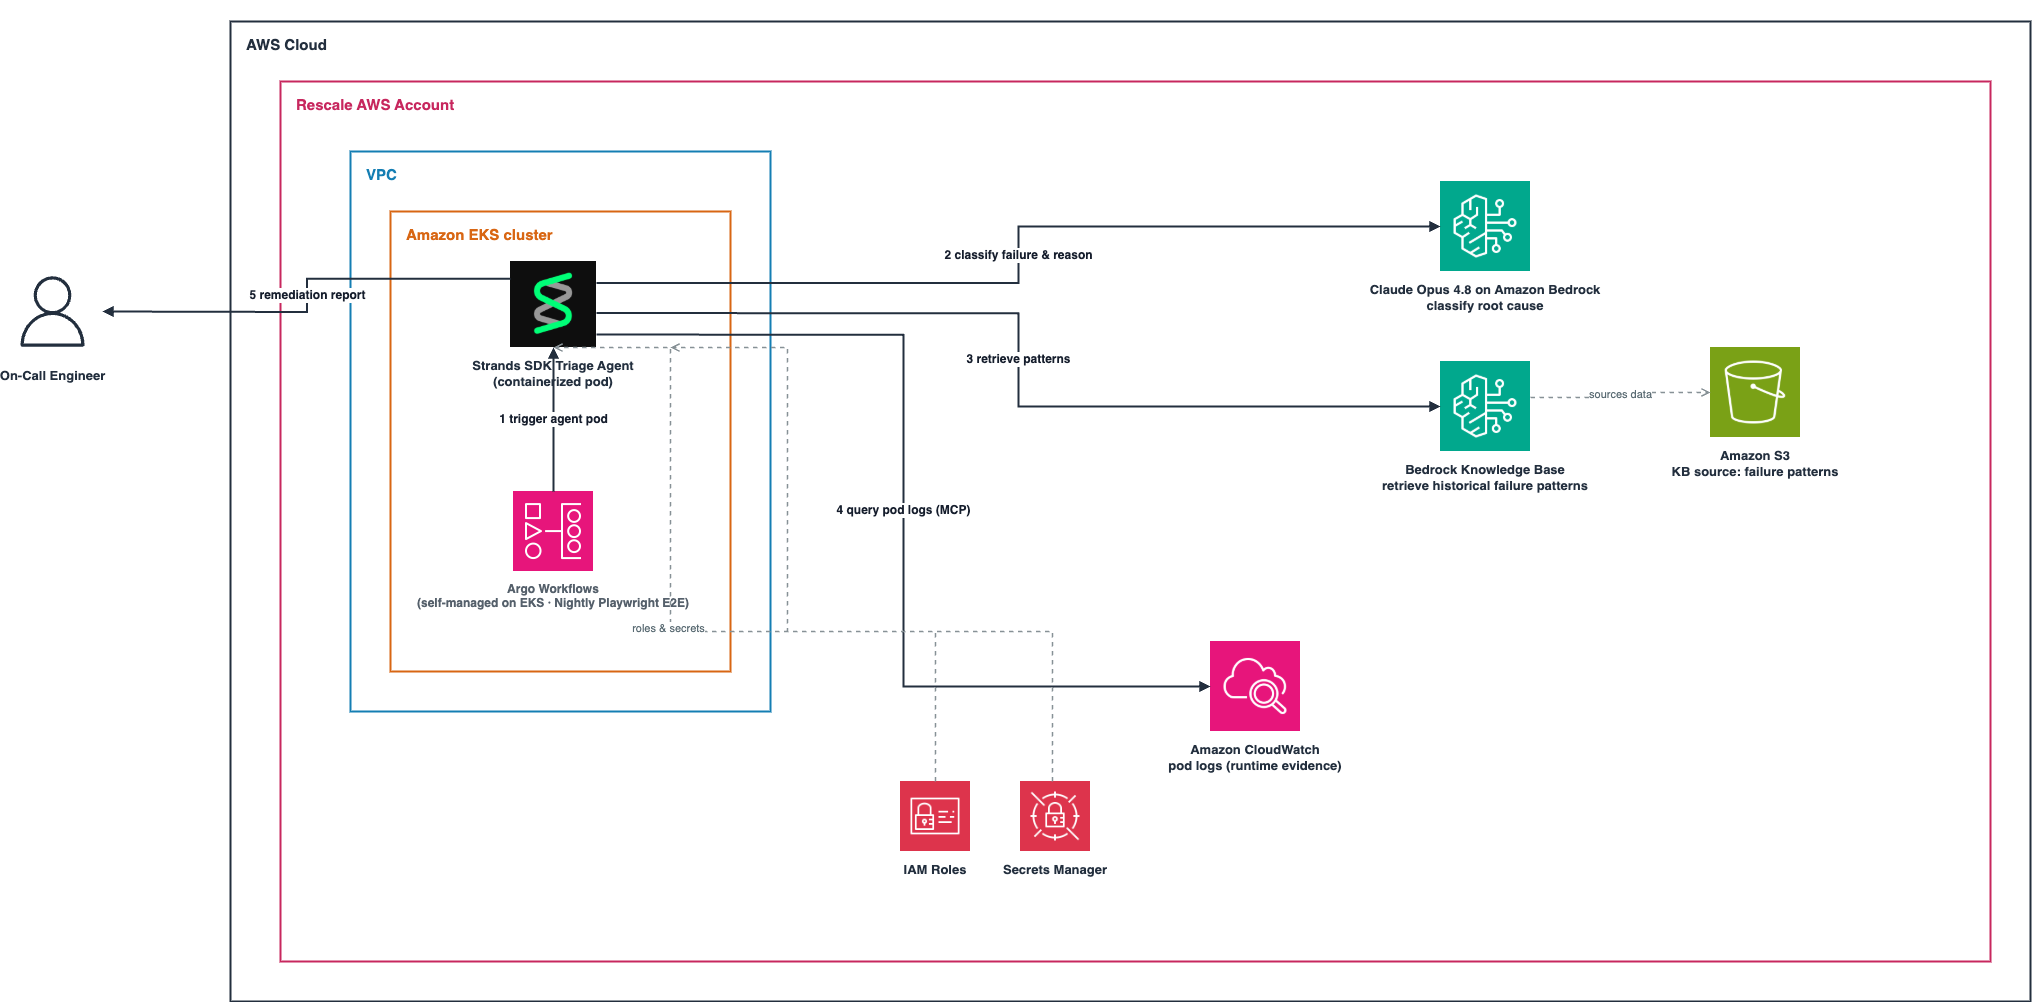
How Rescale built an AI triage agent with Strands Agents and AI-DLC

Every engineering team knows the ritual, and Rescale was no exception. A nightly test suite fails. An on-call engineer pulls the logs, classifies the root cause, and routes it to the right team, only to repeat the process the next morning. At scale, across distributed services and dozens of repositories, this ritual becomes a full-time job … Read more
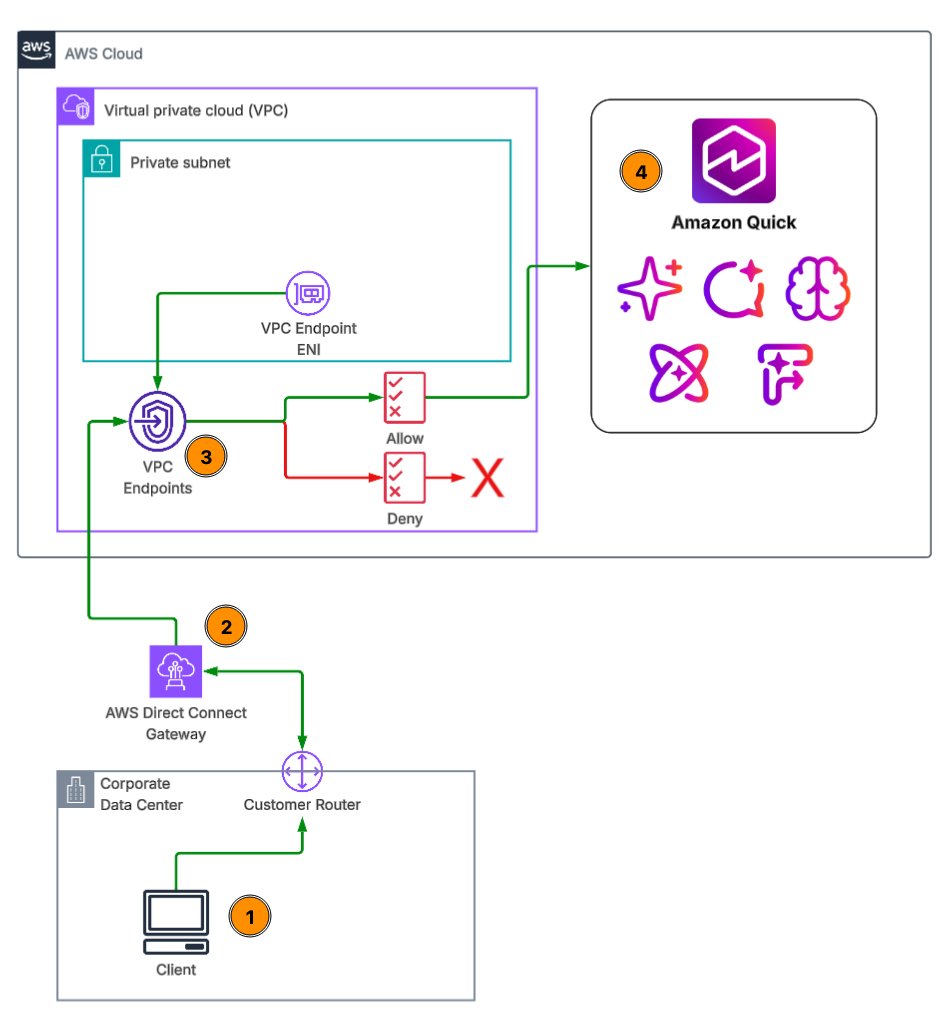
Securing Quick access from corporate networks with AWS PrivateLink

When enterprise data sits behind a corporate firewall or in a private on-premises data center, there’s no direct network path from AWS, even though the AI agents and dashboards in Amazon Quick can query virtually any data source. Administrators must make sure their sensitive enterprise data isn’t exposed to the public internet while being accessible … Read more

Adaptive agentic intelligence framework using Strands Agents

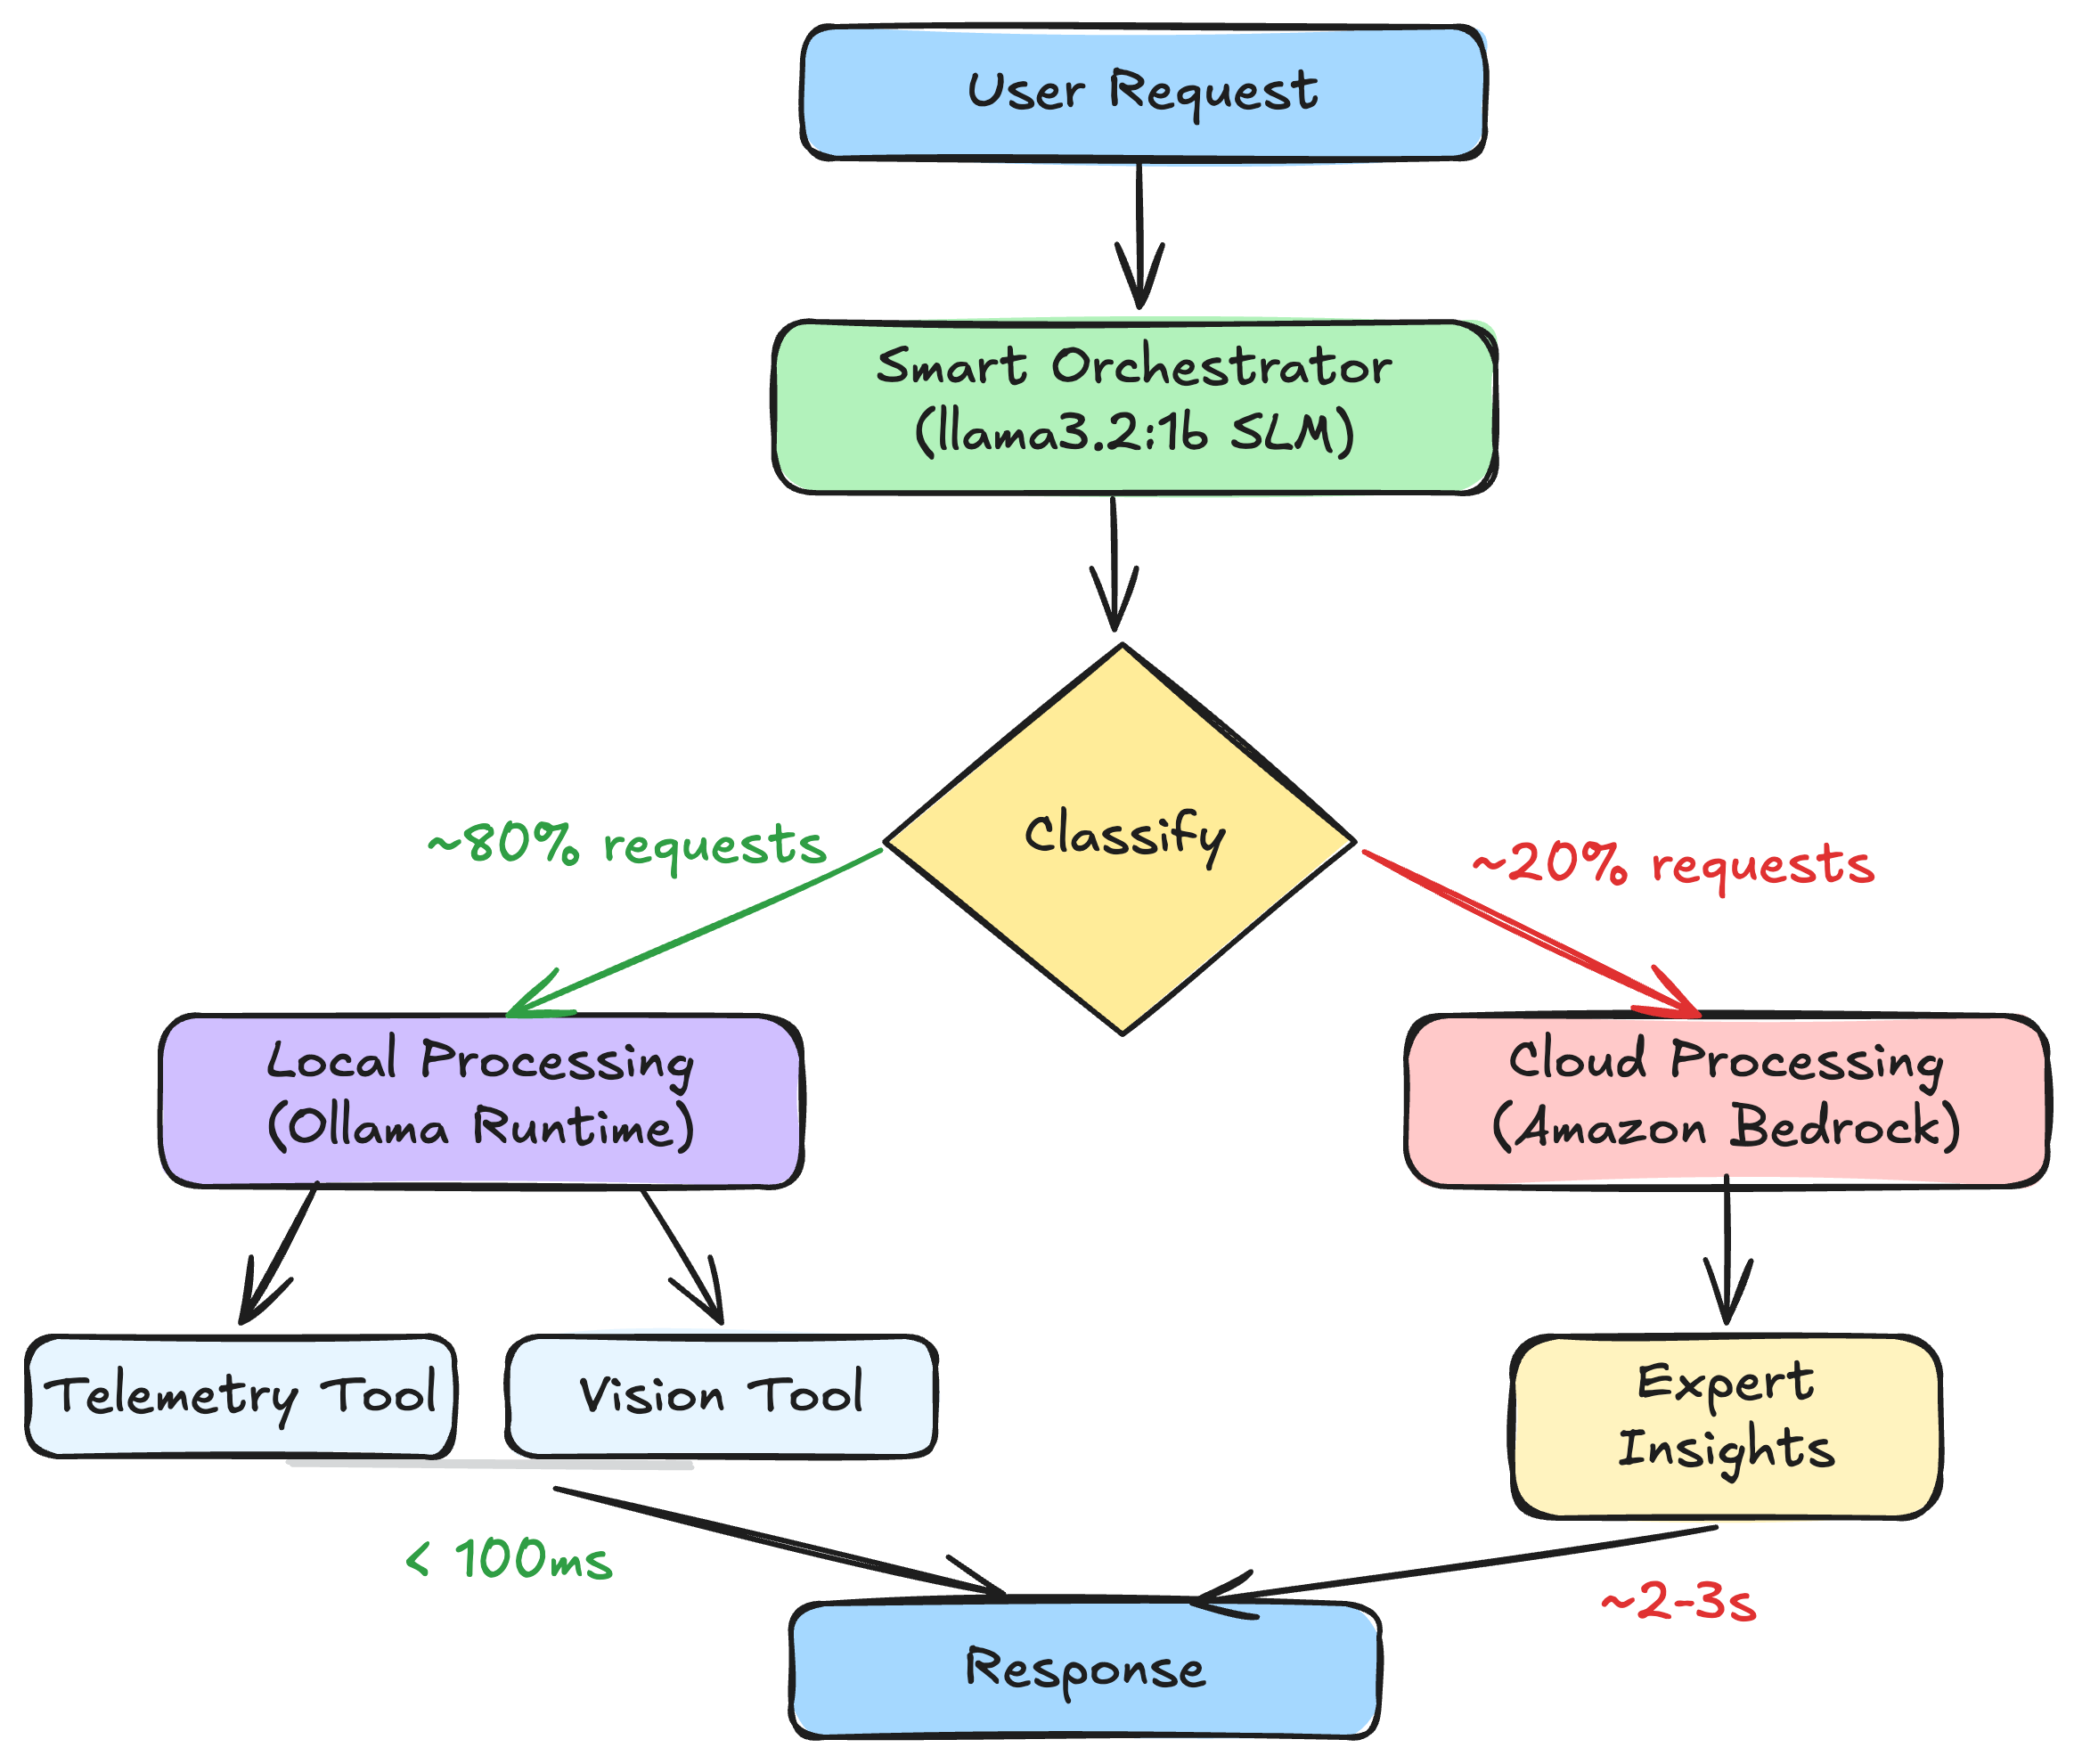
Organizations building AI agents face a common challenge: Every request, whether a routine status check or complex analysis, typically gets routed to a single large, expensive model. This one-size-fits-all approach can drive up API costs, introduce unpredictable latency, and remove the possibility of offline operation. Even routine queries that could resolve locally end up requiring … Read more

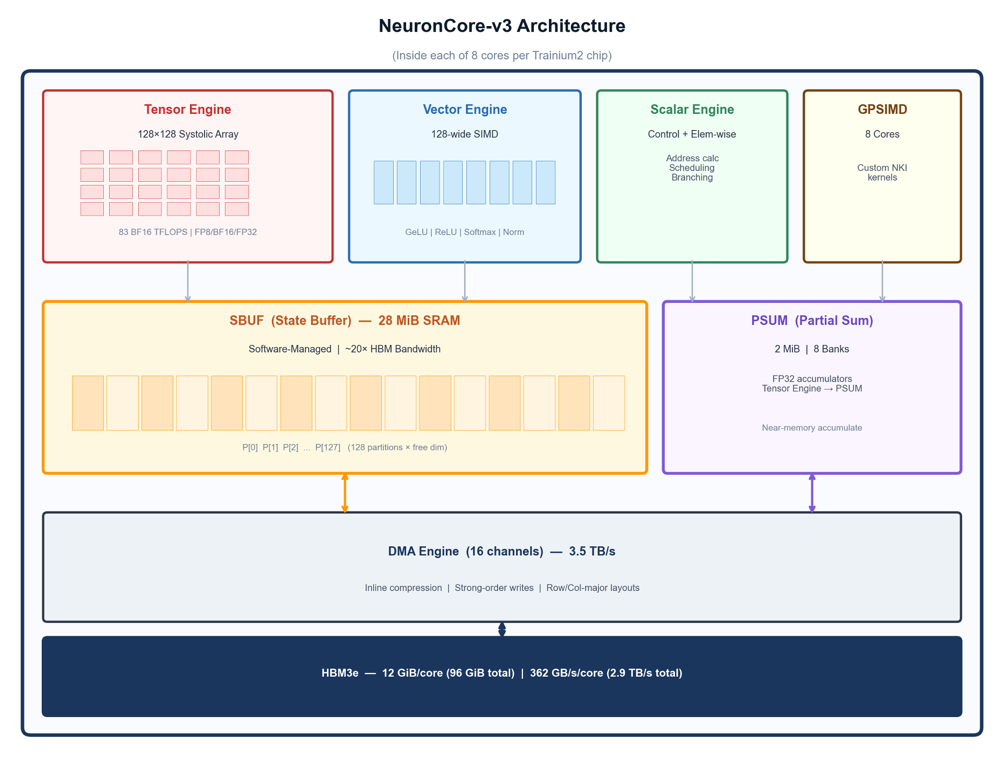
Train Qwen3 on AWS Trainium with torchtitan

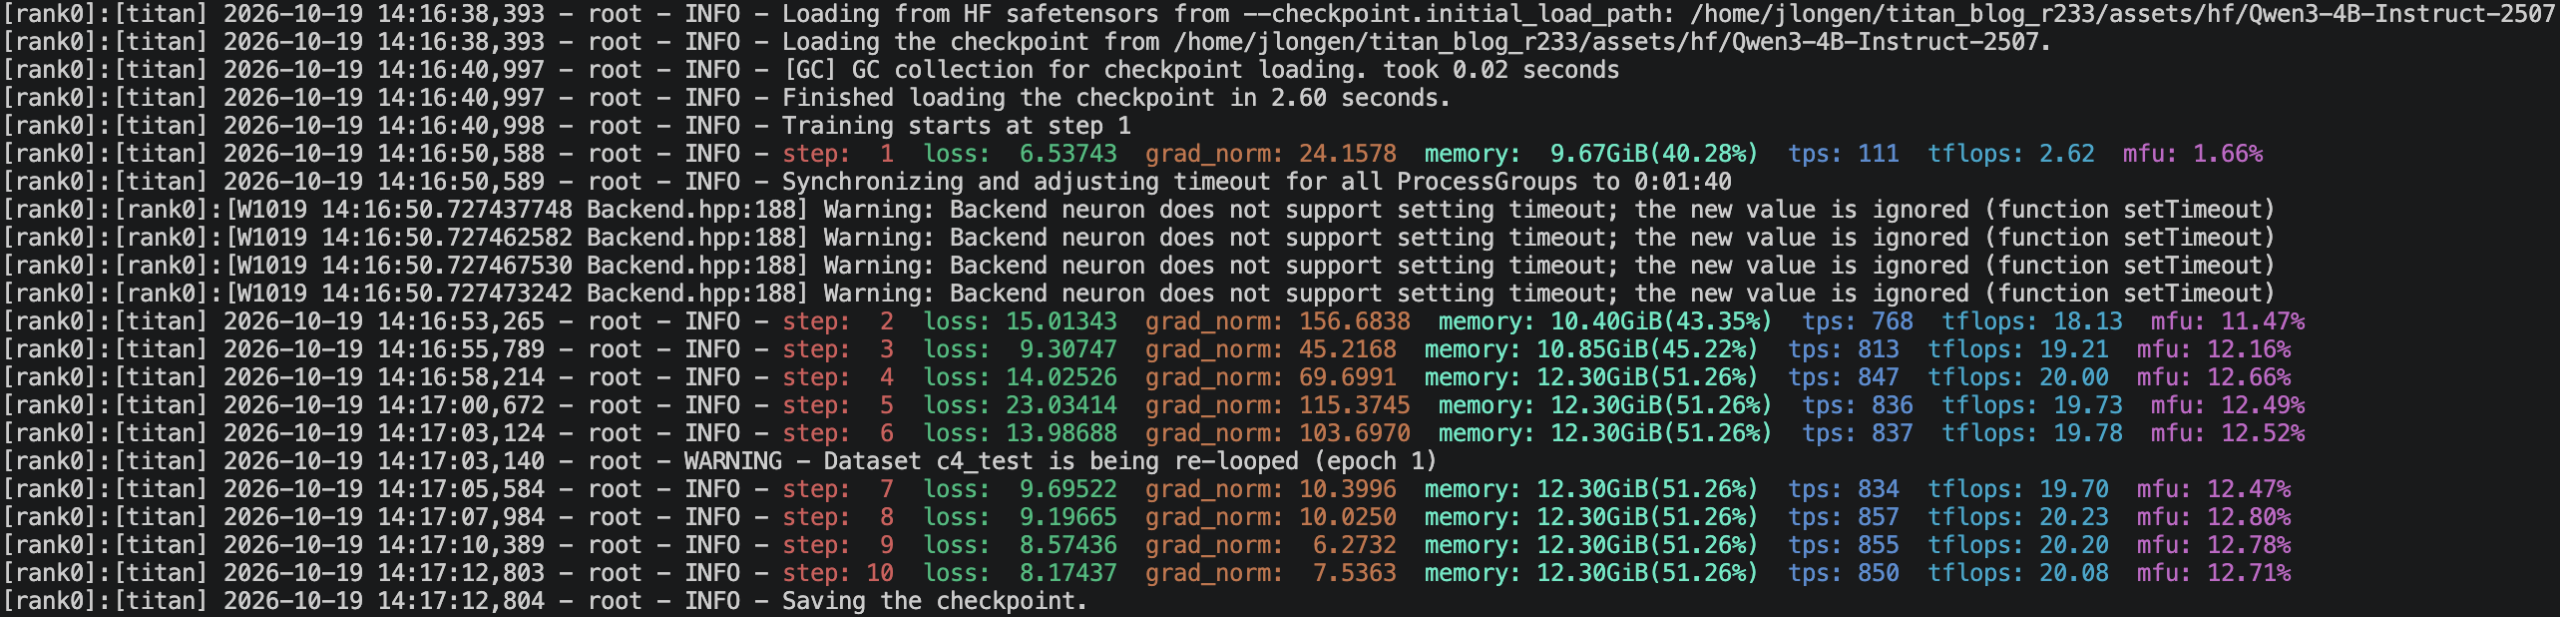
Using torchtitan on AWS Trainium means using it the way you always have. TorchNeuron registers Trainium as a native PyTorch device, which lets torchtitan use it through standard PyTorch interfaces. You can use these configurations to pre-train from random initialization or fine-tune published weights. You can also customize the model implementation and kernels for your … Read more

How U.S. Hunger connects leaders and data using Amazon Quick

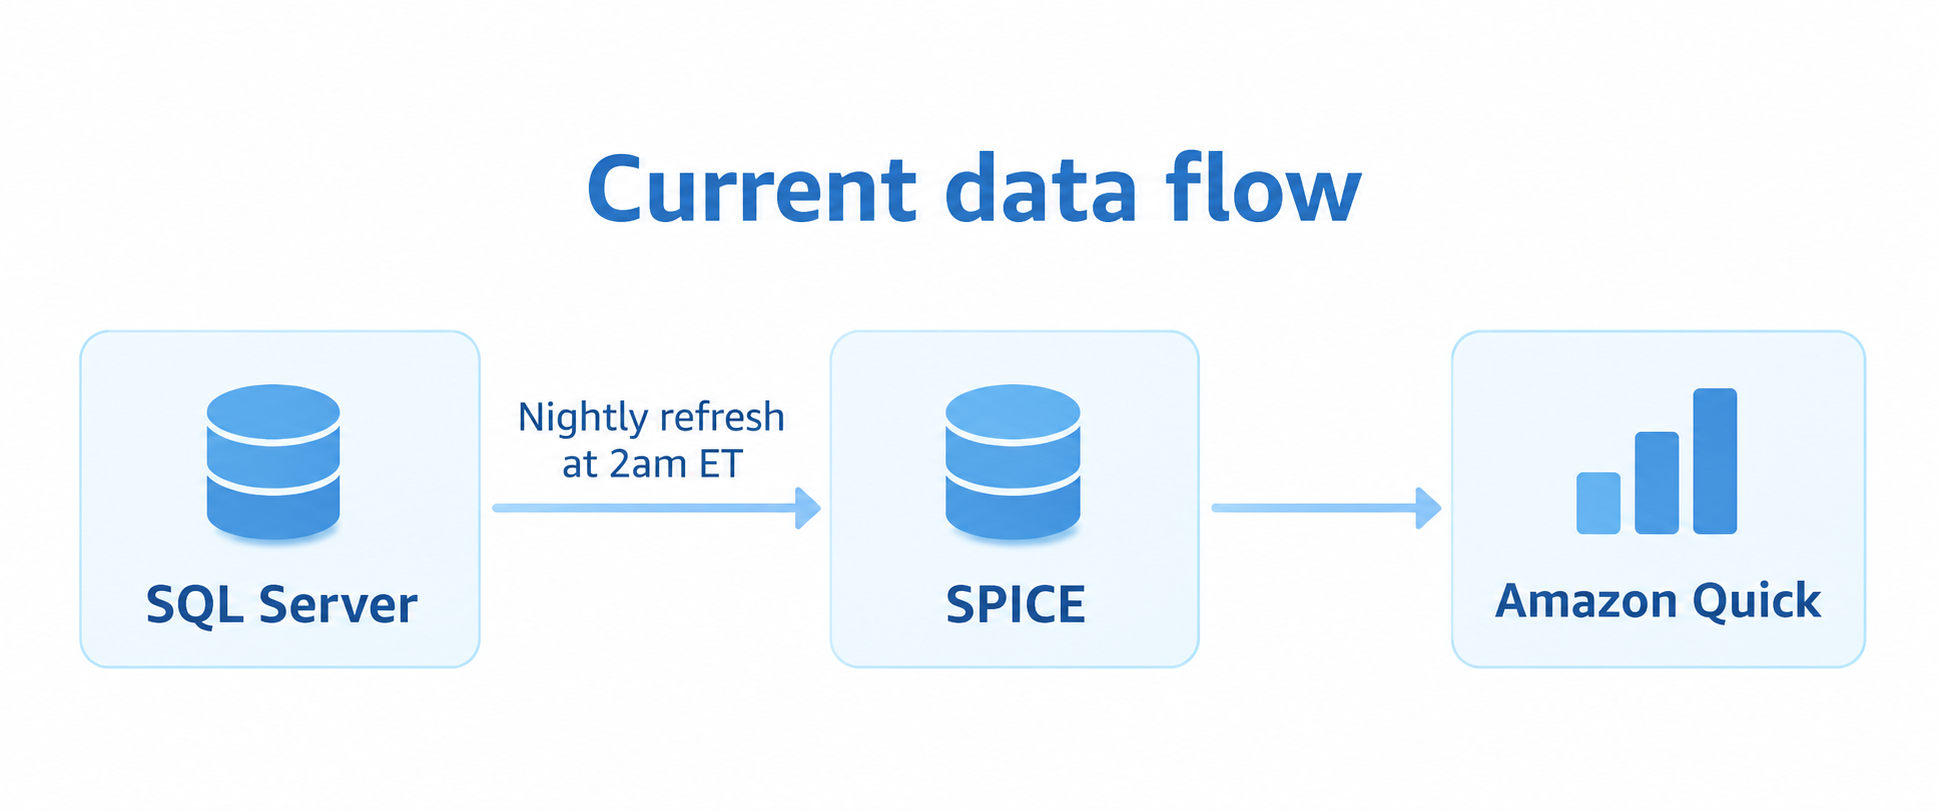
For U.S. Hunger, feeding families takes more than delivering food to them. It takes understanding the people behind each request, the pressures they face, and the business that makes the mission possible. That means connecting information across the organization. Its mission is to feed families today and unite them to a healthier tomorrow. U.S. Hunger … Read more

Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch

Most large language models (LLMs) use transformer architectures with softmax attention. During inference, their key-value (KV) cache grows with the conversation or document context. This can reduce concurrency, increase serving cost, and force agentic applications to discard useful history. i14 designed Laplace 3B as a linear attention alternative. Its recurrent state stays at 29.5 MB … Read more

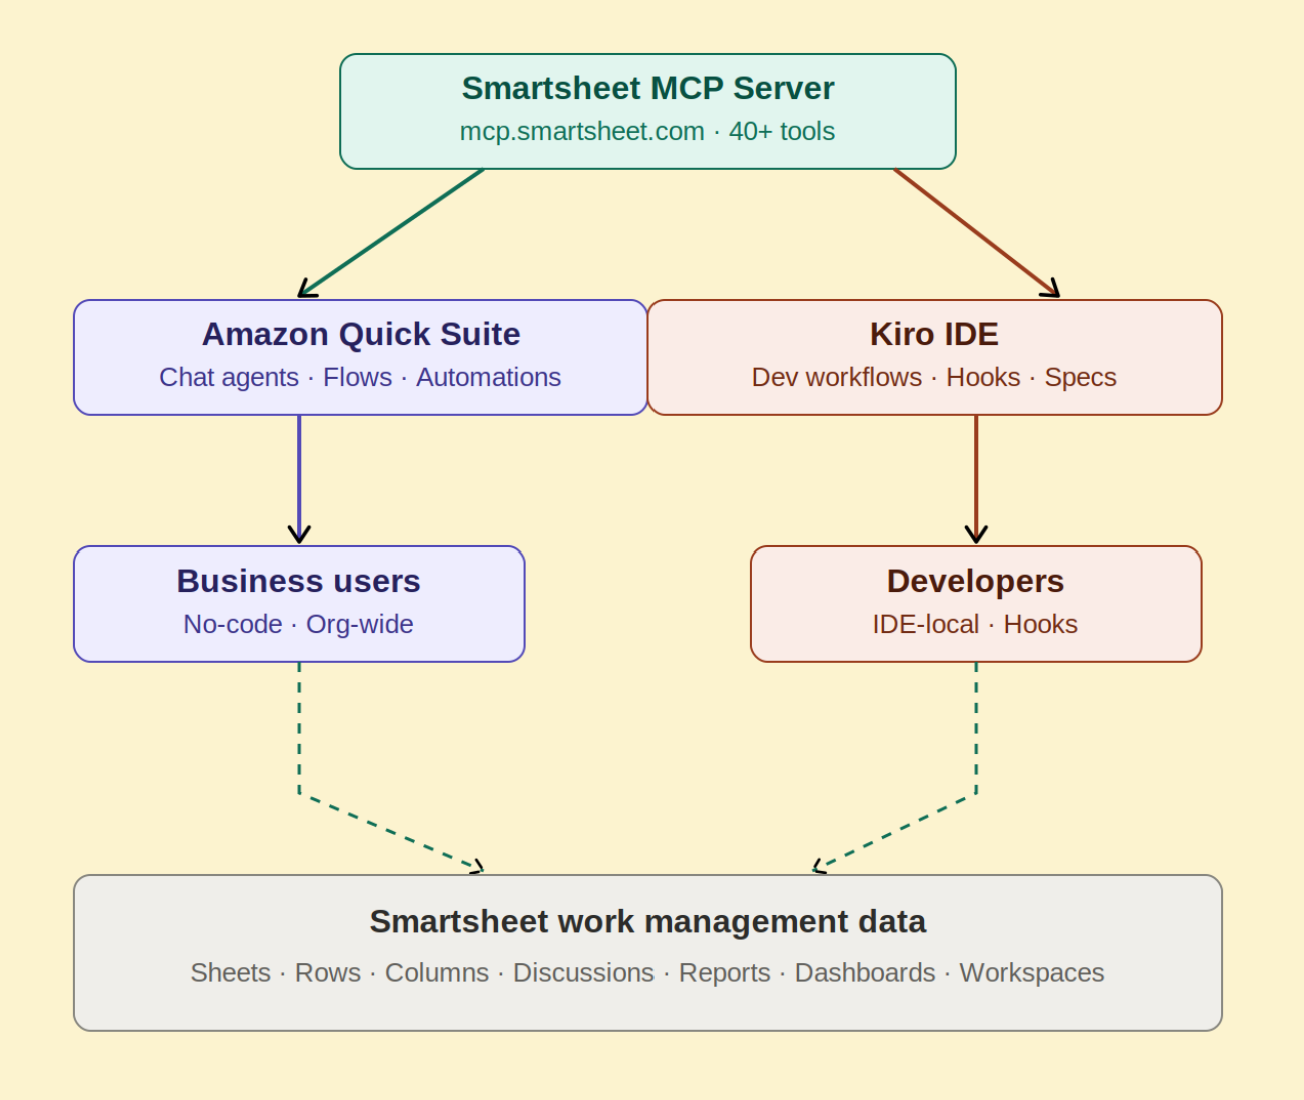
Work management context for AI agents with Smartsheet MCP on AWS

AI agents are most useful when they can act on the real work happening across your organization. Work management involves complex, cross-functional tasks such as updating project timelines, reassigning tasks, and surfacing status. AI agents can support you with these without anyone switching tools. Smartsheet, the work management platform for managing projects, portfolios, and operations, … Read more

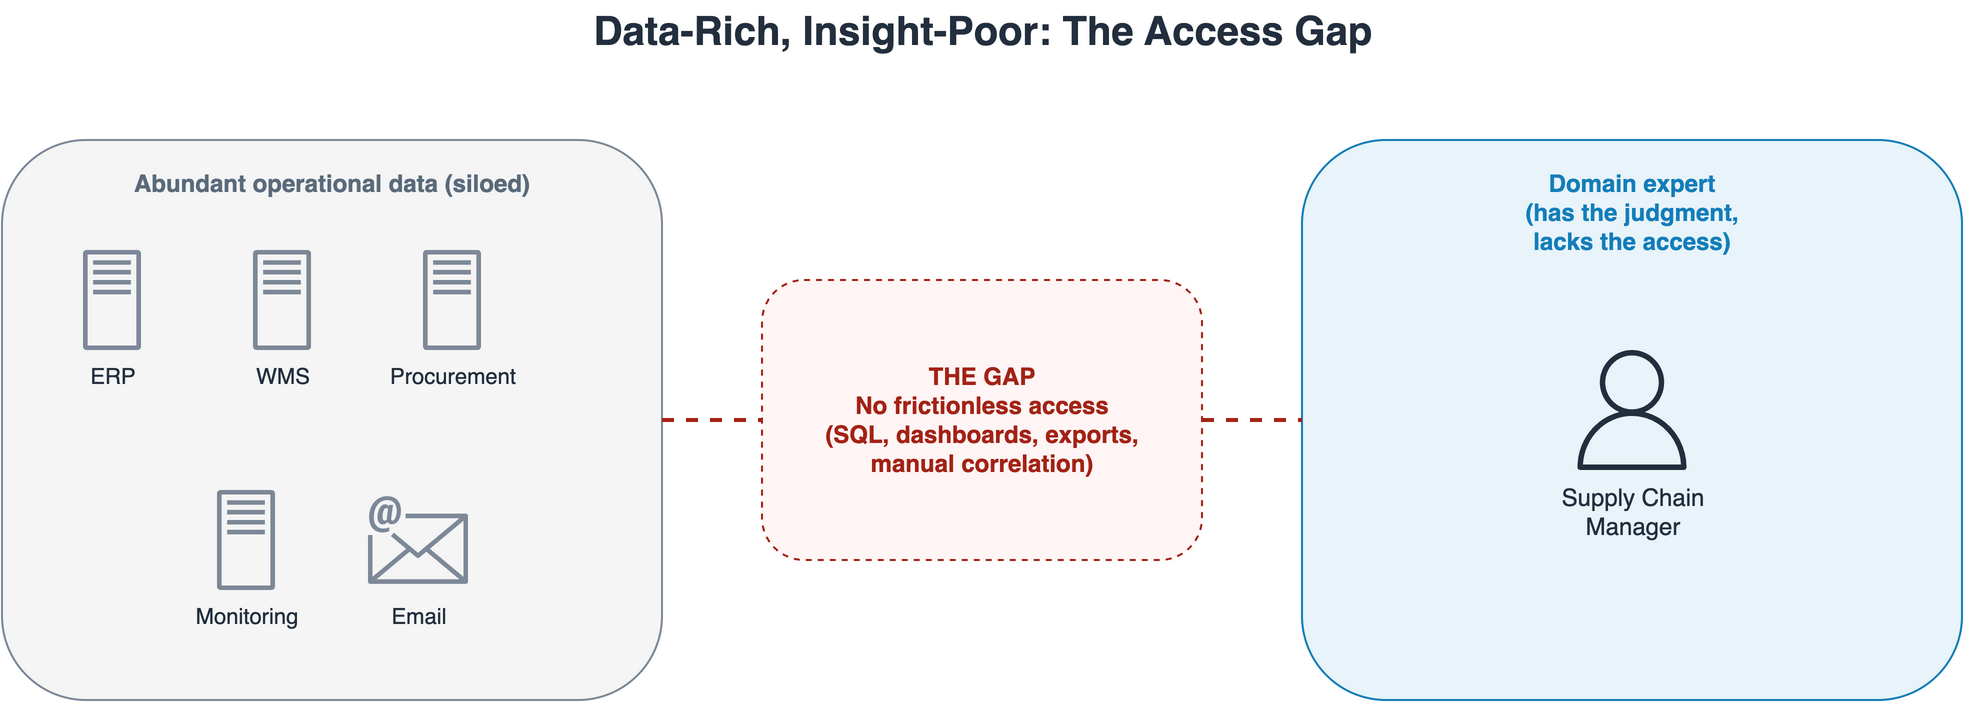
From data to decisions: Conversational supply chain intelligence with Amazon Quick and Amazon Bedrock AgentCore

Giving supply chain teams direct access to the systems behind their decisions. Every supply chain generates constant signals: orders in approval, shifting lead times, slowing ports, drifting prices, disruptions. The problem isn’t scarce data. It’s the distance between the data and the decision-maker. Answering “which top-revenue SKUs are exposed to the current port closure, and … Read more

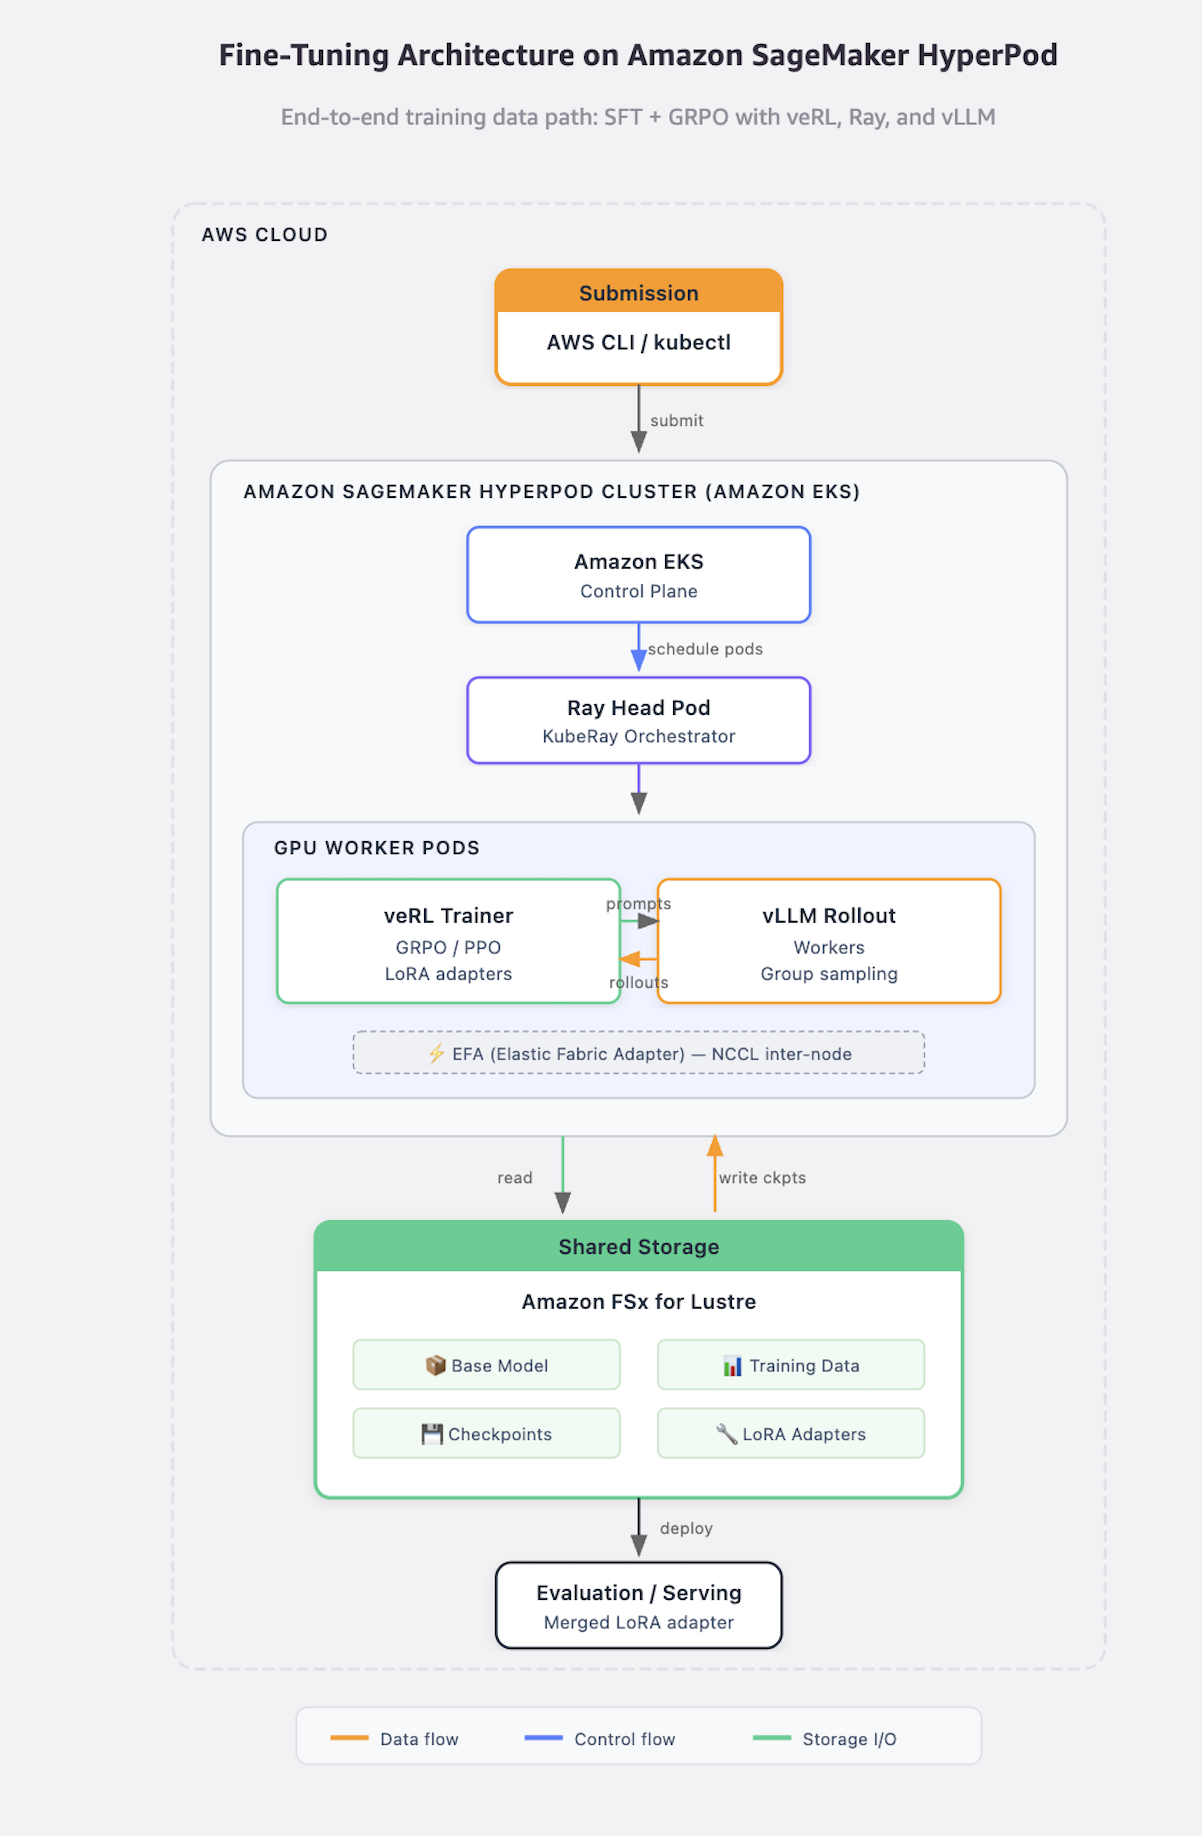
Fine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod

GPT-OSS-20B is an open-weight reasoning model that thinks in English. Ask it to reason in French, German, Spanish, or Italian and it acknowledges the instruction, then produces its chain-of-thought in English anyway. On a 50-example multilingual reasoning test, the base model reasoned in the correct target language only 22 percent of the time. That 22 … Read more

How Octave built a secure multi-tenant AI foundation on Amazon Bedrock

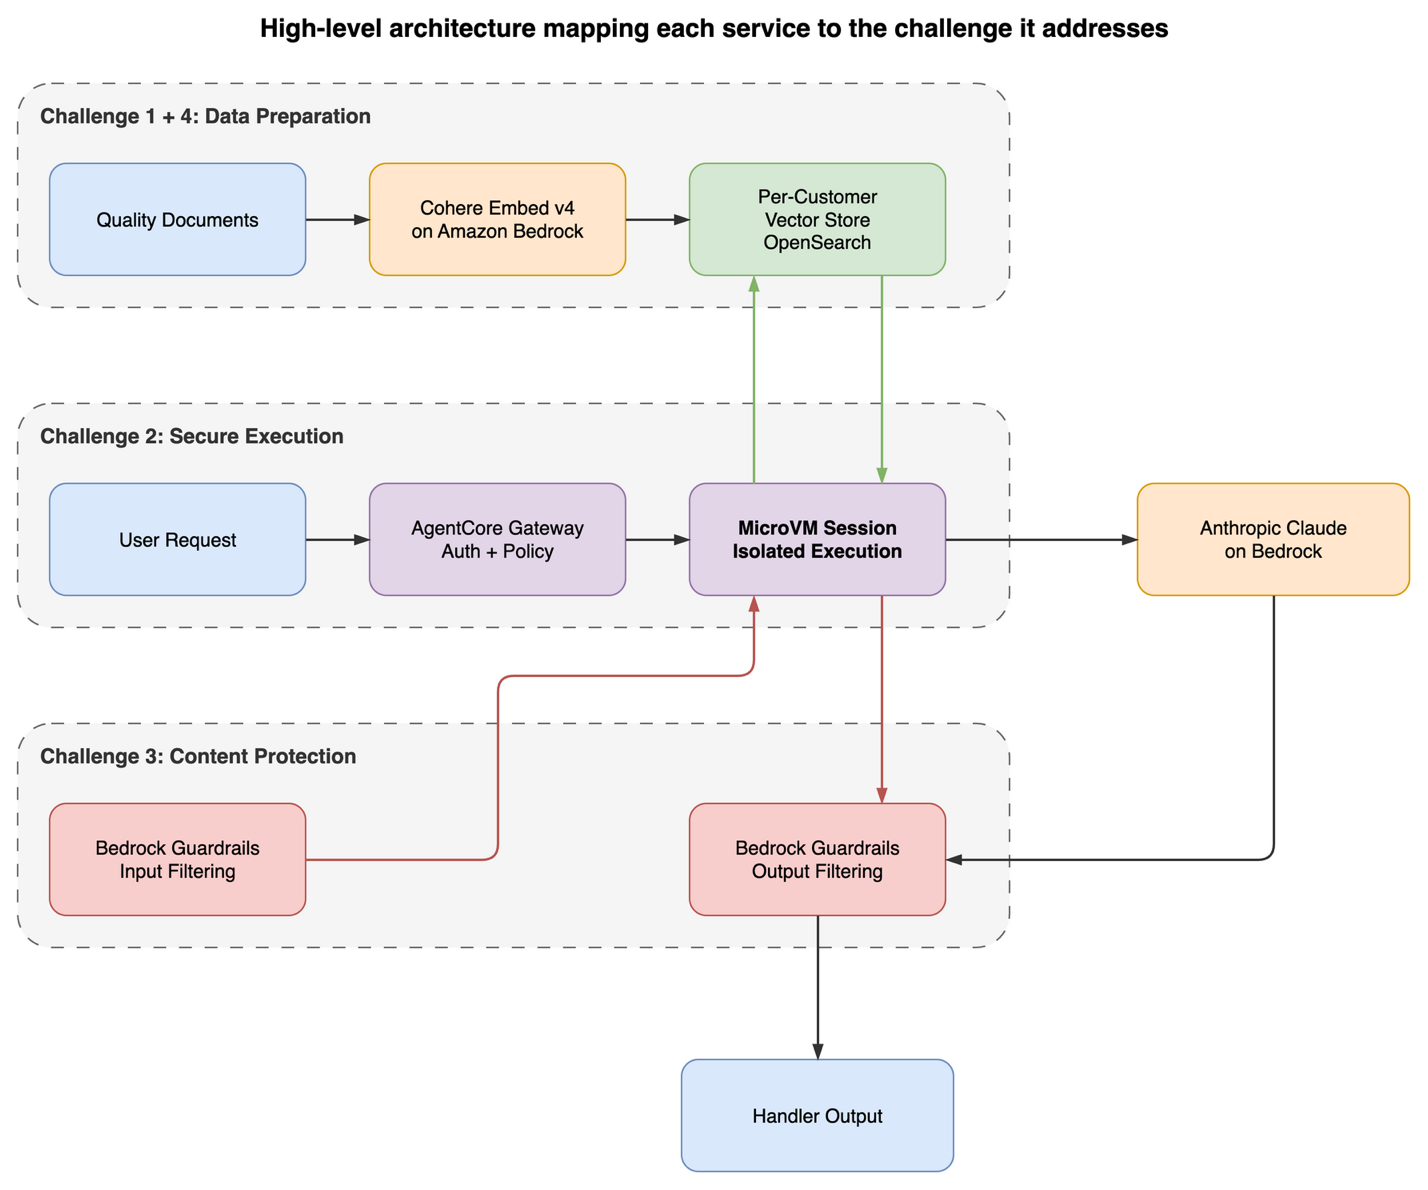
In quality management for regulated industries, the institutional memory that resolves a problem is almost always buried somewhere in a customer’s history. A similar defect investigated last year, a Corrective and Preventive Action (CAPA) that fixed the root cause, an audit finding that flagged the same gap. That knowledge sits in billions of documents no … Read more

Access OpenAI GPT models on Amazon Bedrock from Canada with cross-Region inference

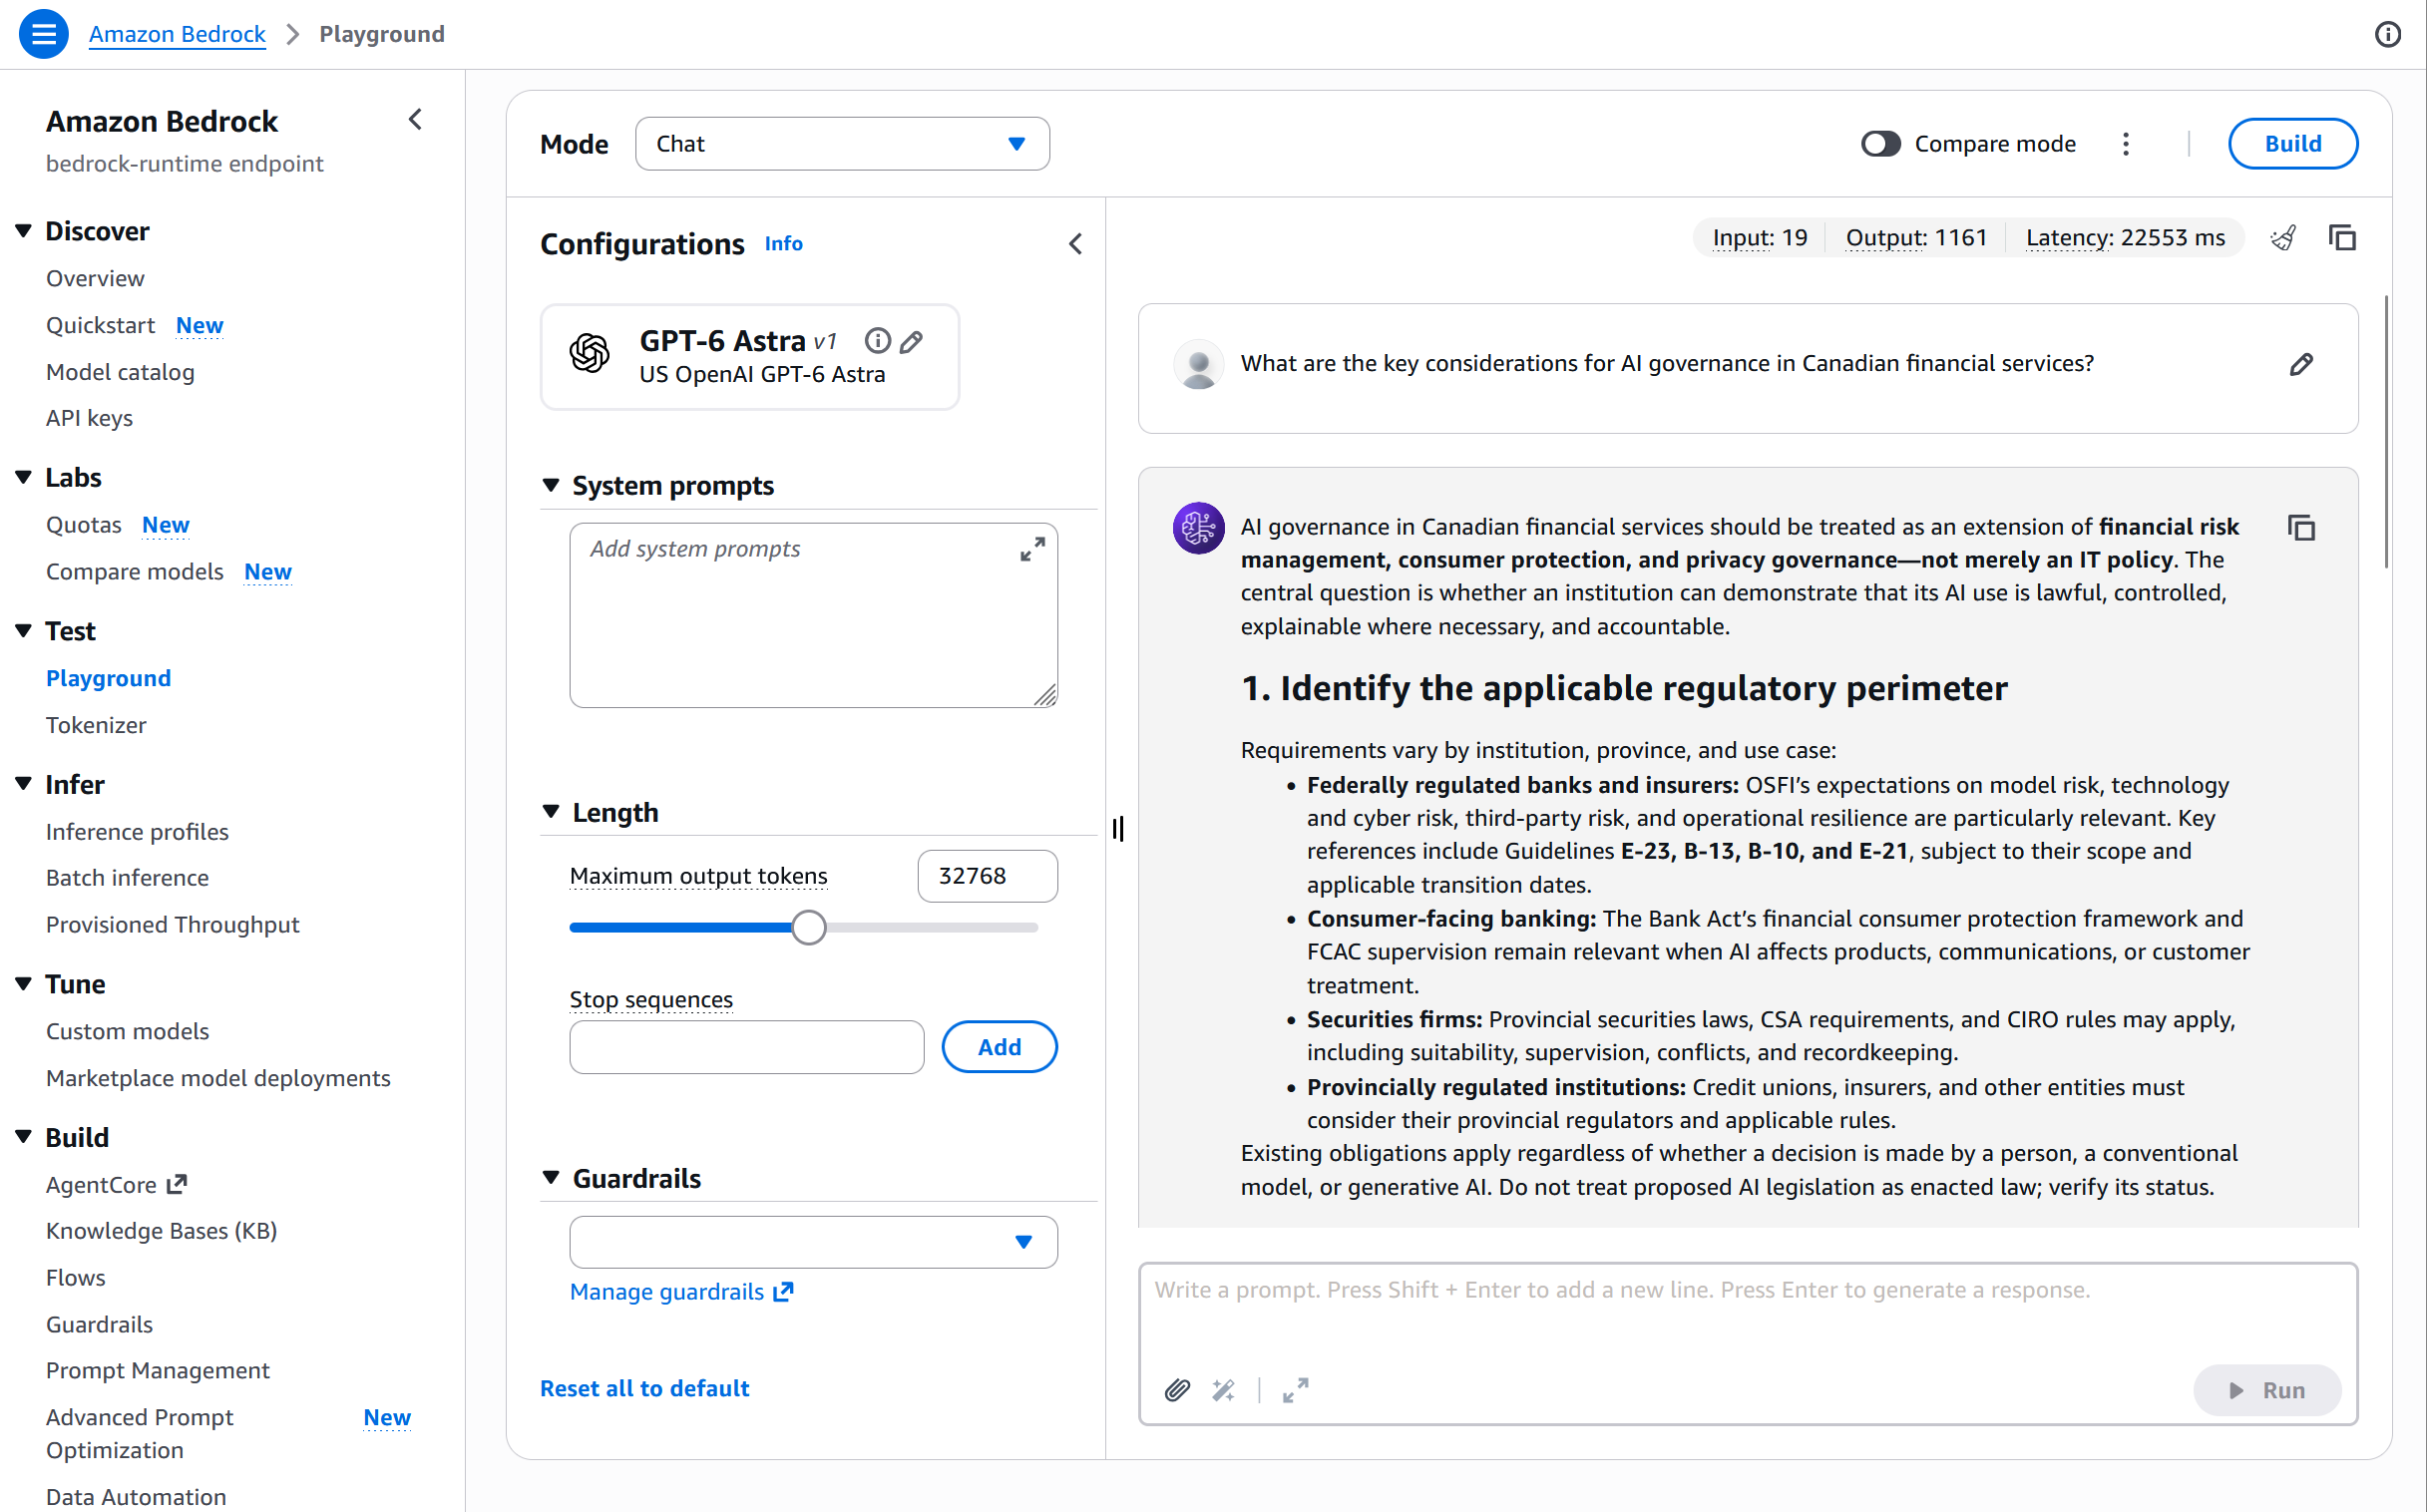
Canadian organizations building generative AI applications on Amazon Bedrock often need the latest foundation models (FMs), such as OpenAI GPT-6.1, OpenAI GPT-6, and GPT-5.6, accessible from the Canadian AWS Regions. With Amazon Bedrock cross-Region inference (CRIS), you can now access these models from Canada. OpenAI GPT-5.6 models (Sol, Terra, and Luna), GPT-6 (Astra, Sol, and … Read more

Build a semantic layer for agentic AI on AWS with Denodo and Amazon Bedrock AgentCore

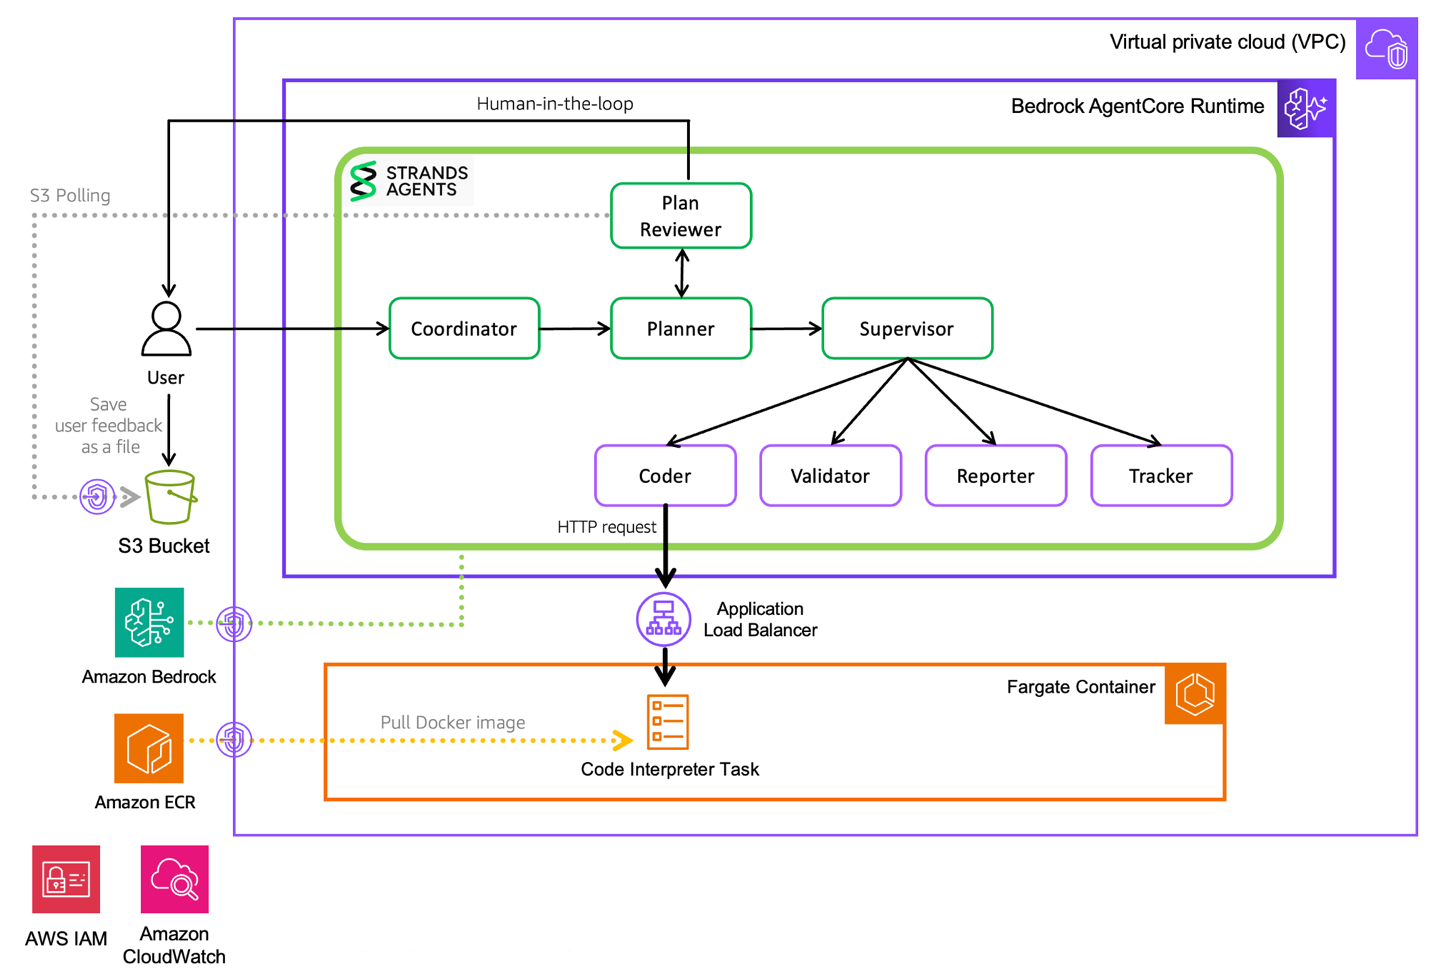
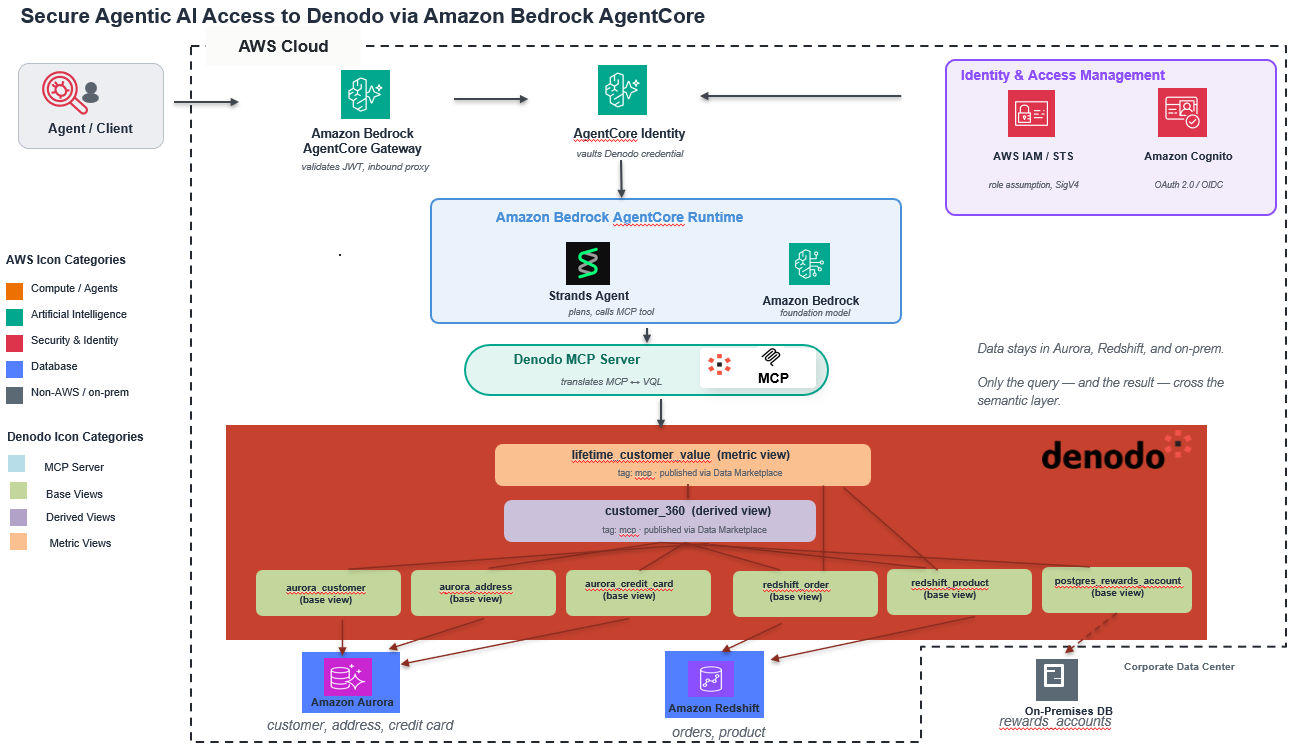
Agentic AI applications need governed access to live enterprise data. That data can live in operational systems, analytical warehouses, SaaS applications, other clouds, or on premises. In the previous post in this series, we built a semantic layer on AWS using Stardog’s knowledge graph over Amazon Aurora and Amazon Redshift. A Strands agent on Amazon … Read more

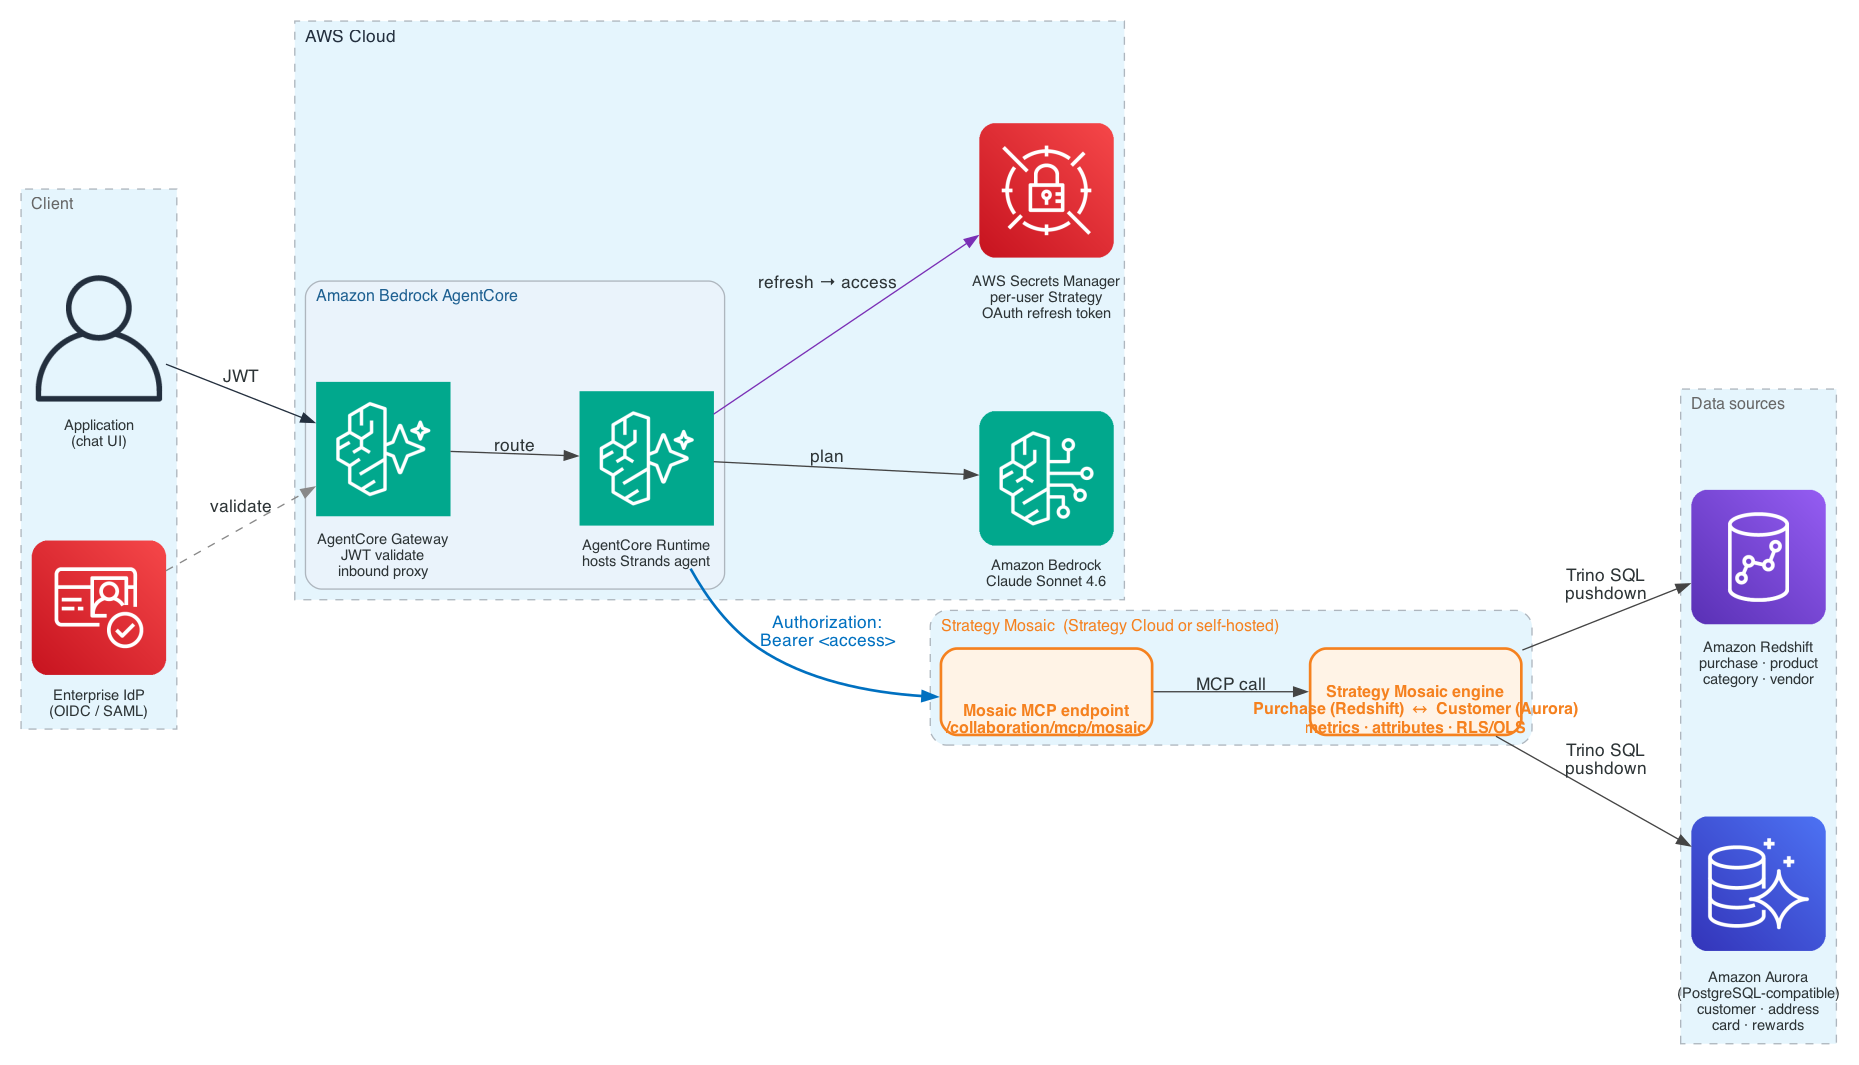
Build a semantic layer for agentic AI on AWS with Strategy Mosaic and Amazon Bedrock AgentCore

This post is co-written with Zhili Cheng, Principal Product Manager, George Earle, Director, AI Engineering, and Kyler K, Sales Engineer of Strategy. In the first post in this series, we built a semantic layer on AWS using Stardog’s knowledge graph over Amazon Aurora and Amazon Redshift and ran a Strands agent on Amazon Bedrock AgentCore … Read more

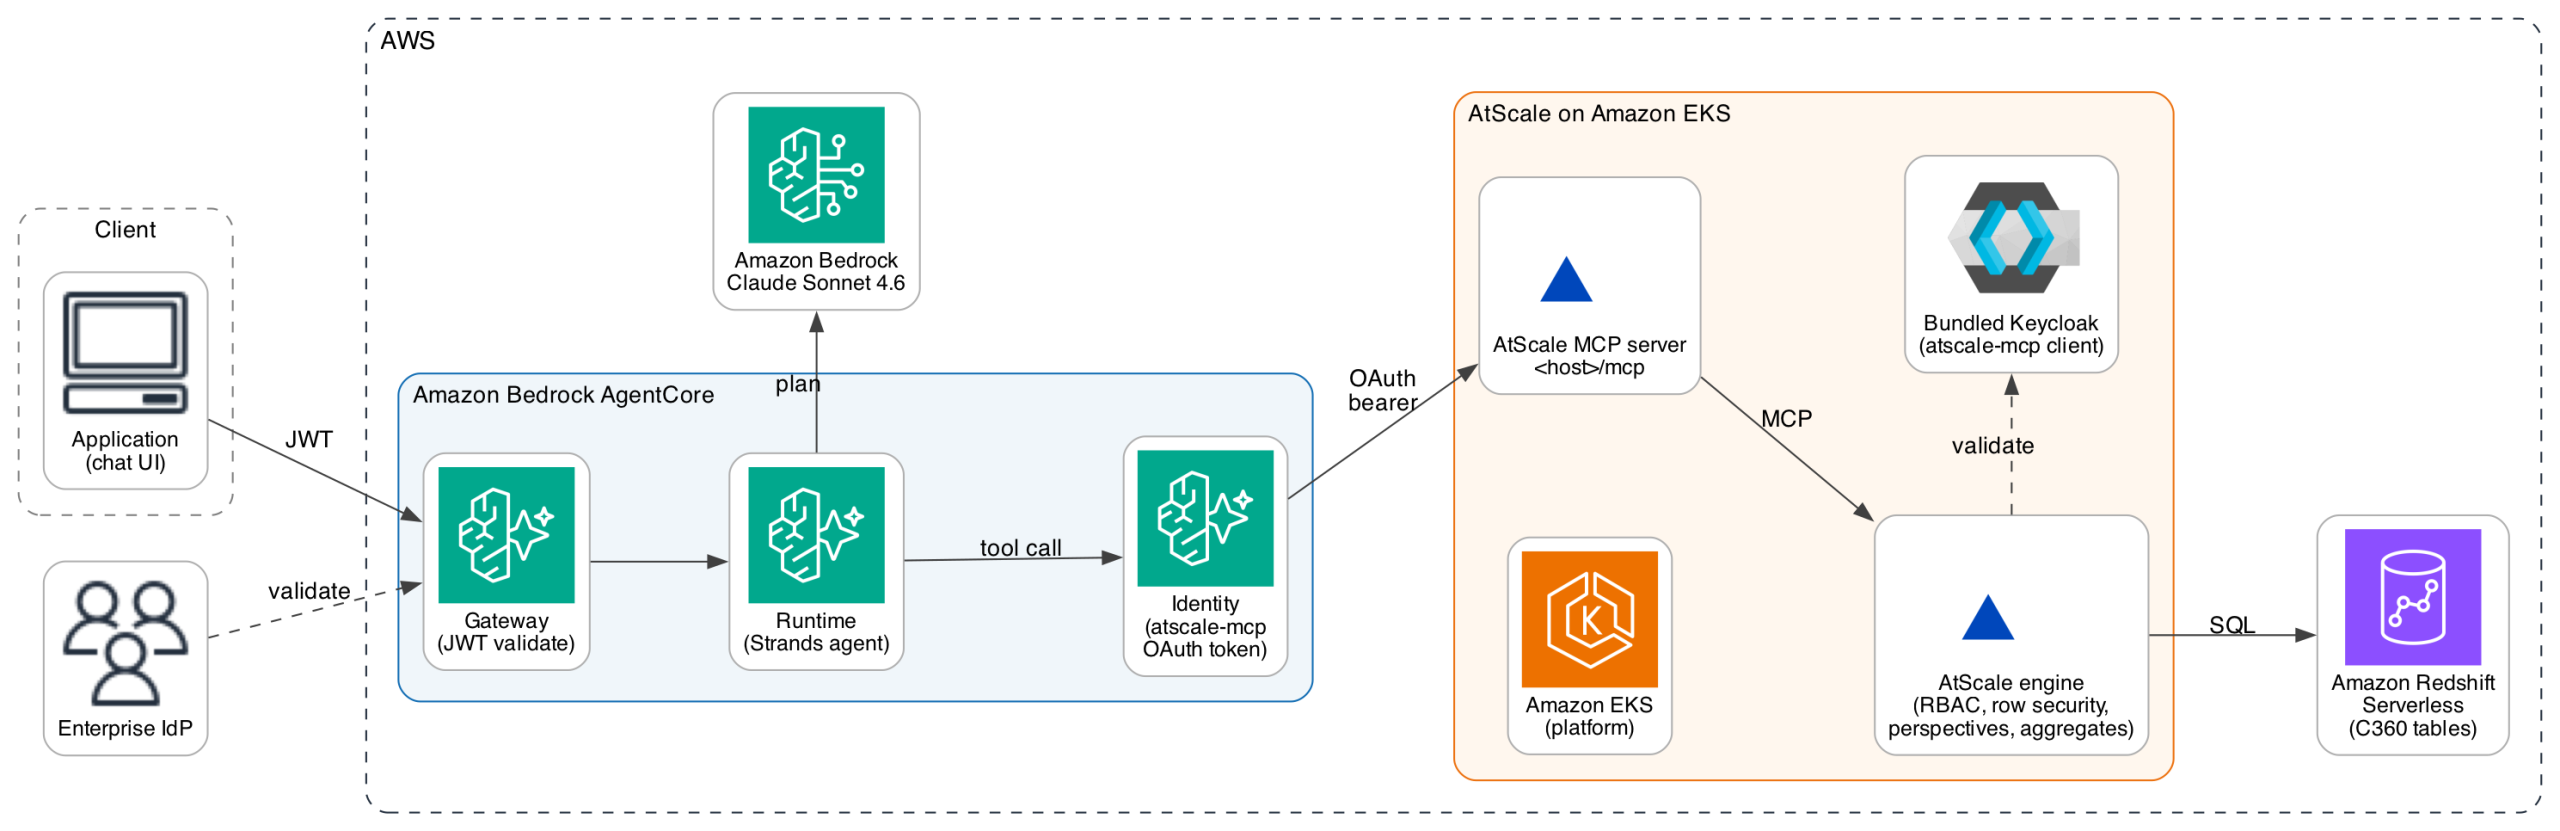
Build a semantic layer for agentic AI on AWS with AtScale and Amazon Bedrock AgentCore

In the first post in this series, we built a semantic layer on AWS using Stardog’s knowledge graph over Amazon Aurora and Amazon Redshift. We ran a Strands agent on Amazon Bedrock AgentCore against that layer. The second post kept the same customer 360 (C360) pattern and swapped in Denodo’s data virtualization platform, extending the … Read more

Structured outputs for Anthropic Claude models on Amazon Bedrock

Amazon Bedrock now supports structured outputs for all Anthropic Claude models, on both the bedrock-runtime and bedrock-mantle endpoints, where the model is available. Whether you call Claude through Boto3 and the bedrock-runtime APIs or through the Messages API and the bedrock-mantle endpoint, you can now receive schema-compliant JSON responses that conform to a defined structure. … Read more

Pegasus 1.5 from TwelveLabs is now available in Amazon Bedrock

On Oct 9, 2026 we announced the availability of TwelveLabs’ Pegasus 1.5 on Amazon Bedrock. Pegasus 1.5 is a video language model that turns long-form video into structured, timestamped metadata. You describe the moments that matter to your workflow, and the model returns every matching segment as JSON. Video represents a significant and complex category … Read more

How Deepgram optimized voice AI at scale with AWS Trainium

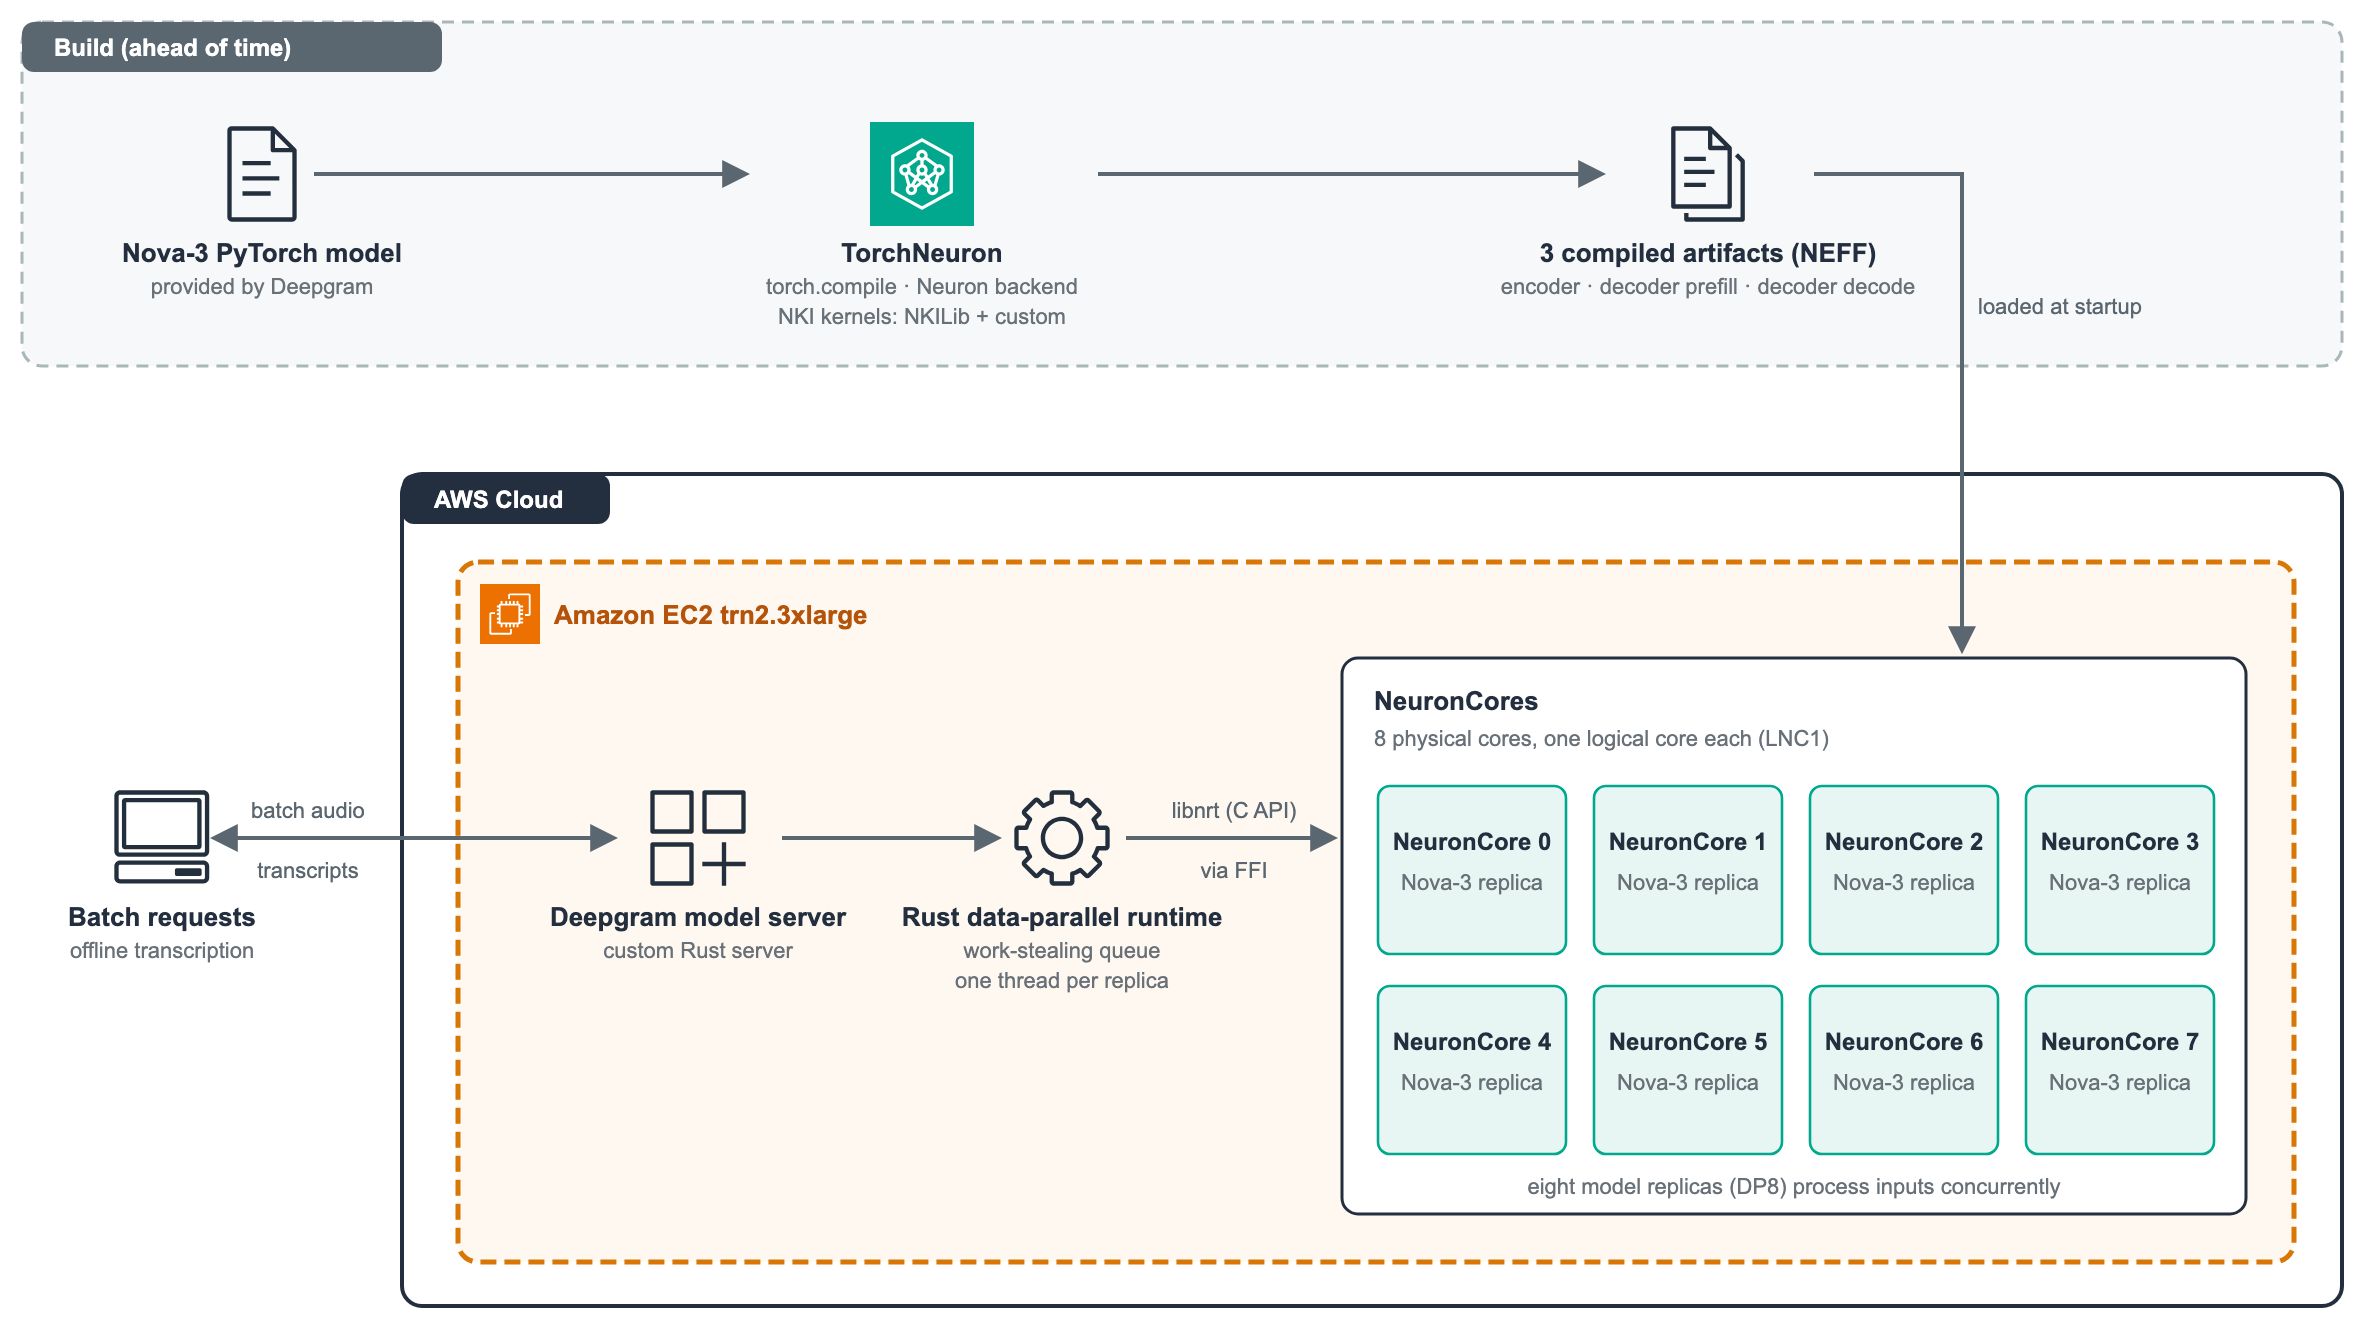
As voice becomes a first-class modality for AI, Deepgram’s models span speech-to-text, text-to-speech, and voice agents. They now process quadrillions of audio tokens a year for more than 200,000 developers and 1,400 organizations. Customers use them through the Deepgram API or run them in their own environments, including on Amazon SageMaker AI. For Deepgram, serving … Read more

Push-based KV transfer to improve TTFT and TPOT for disaggregated inference in vLLM

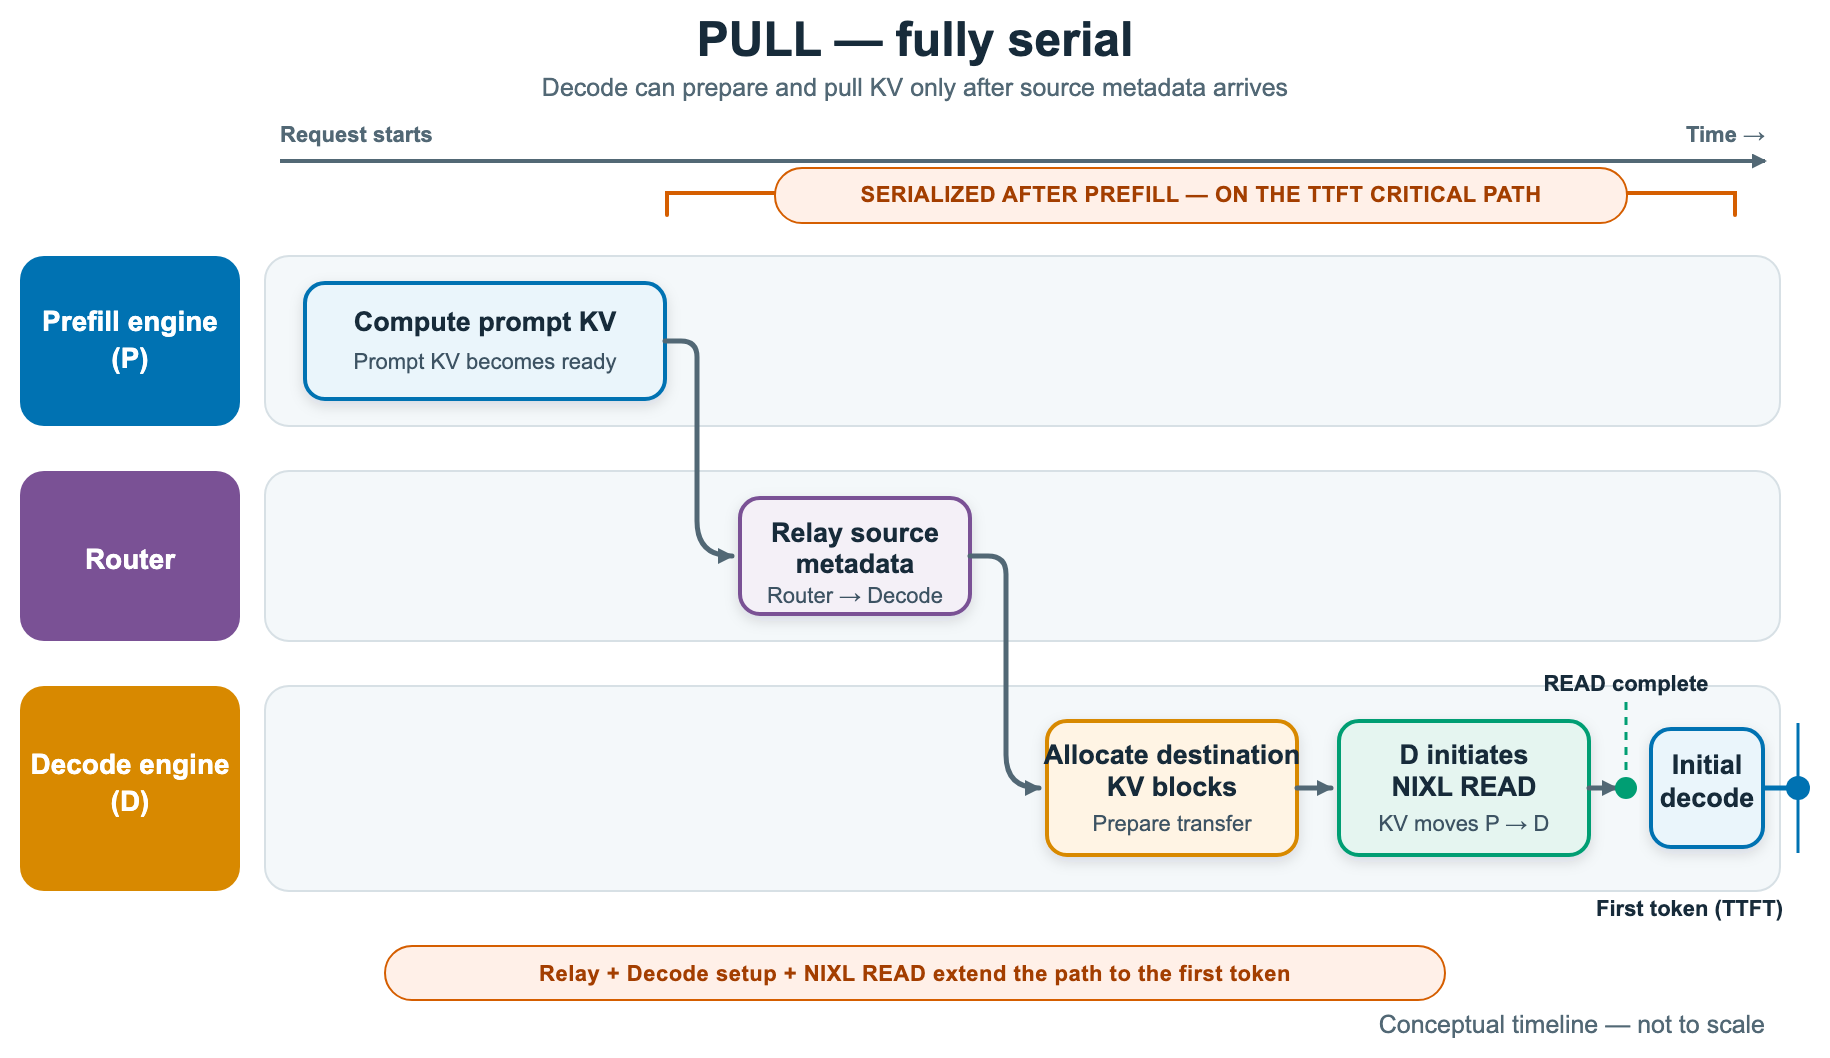
vLLM is an open-source inference and serving engine for large language models (LLMs). LLM inference has two distinct phases: prefill, which processes the input prompt and builds the key-value (KV) cache, and decode, which uses that cache to generate output one token at a time. These phases have different compute, memory, and scaling characteristics. Prefill-decode … Read more

Improve TTFT for multi-turn agentic workloads with bi-directional KV transfer in vLLM

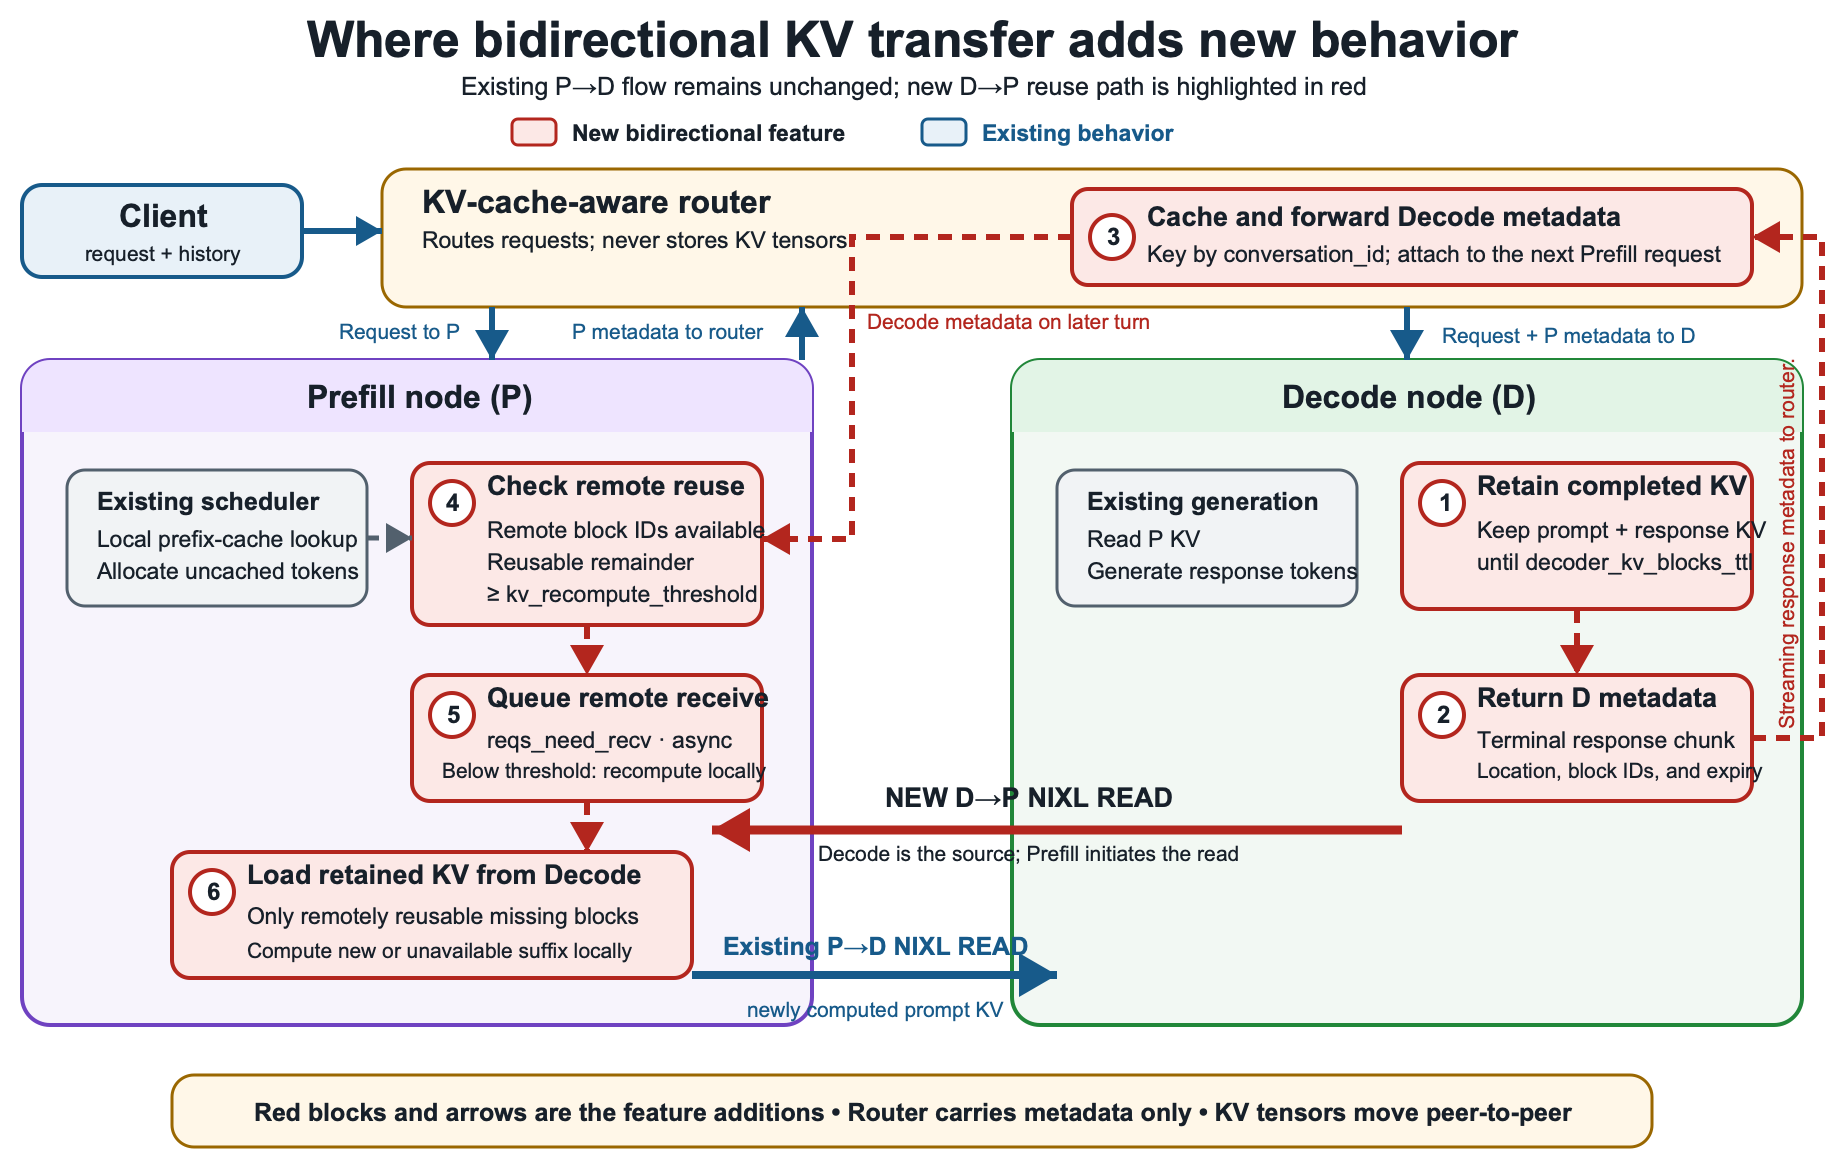
Multi-turn agentic workloads build on accumulated context as an agent reasons, invokes tools, and incorporates earlier results. With each new turn, the client resends the conversation history, including system instructions, prior prompts, tool results, and model responses, causing the growing context to be processed repeatedly. In Prefill-decode (P-D) disaggregation, each request is split across specialized … Read more

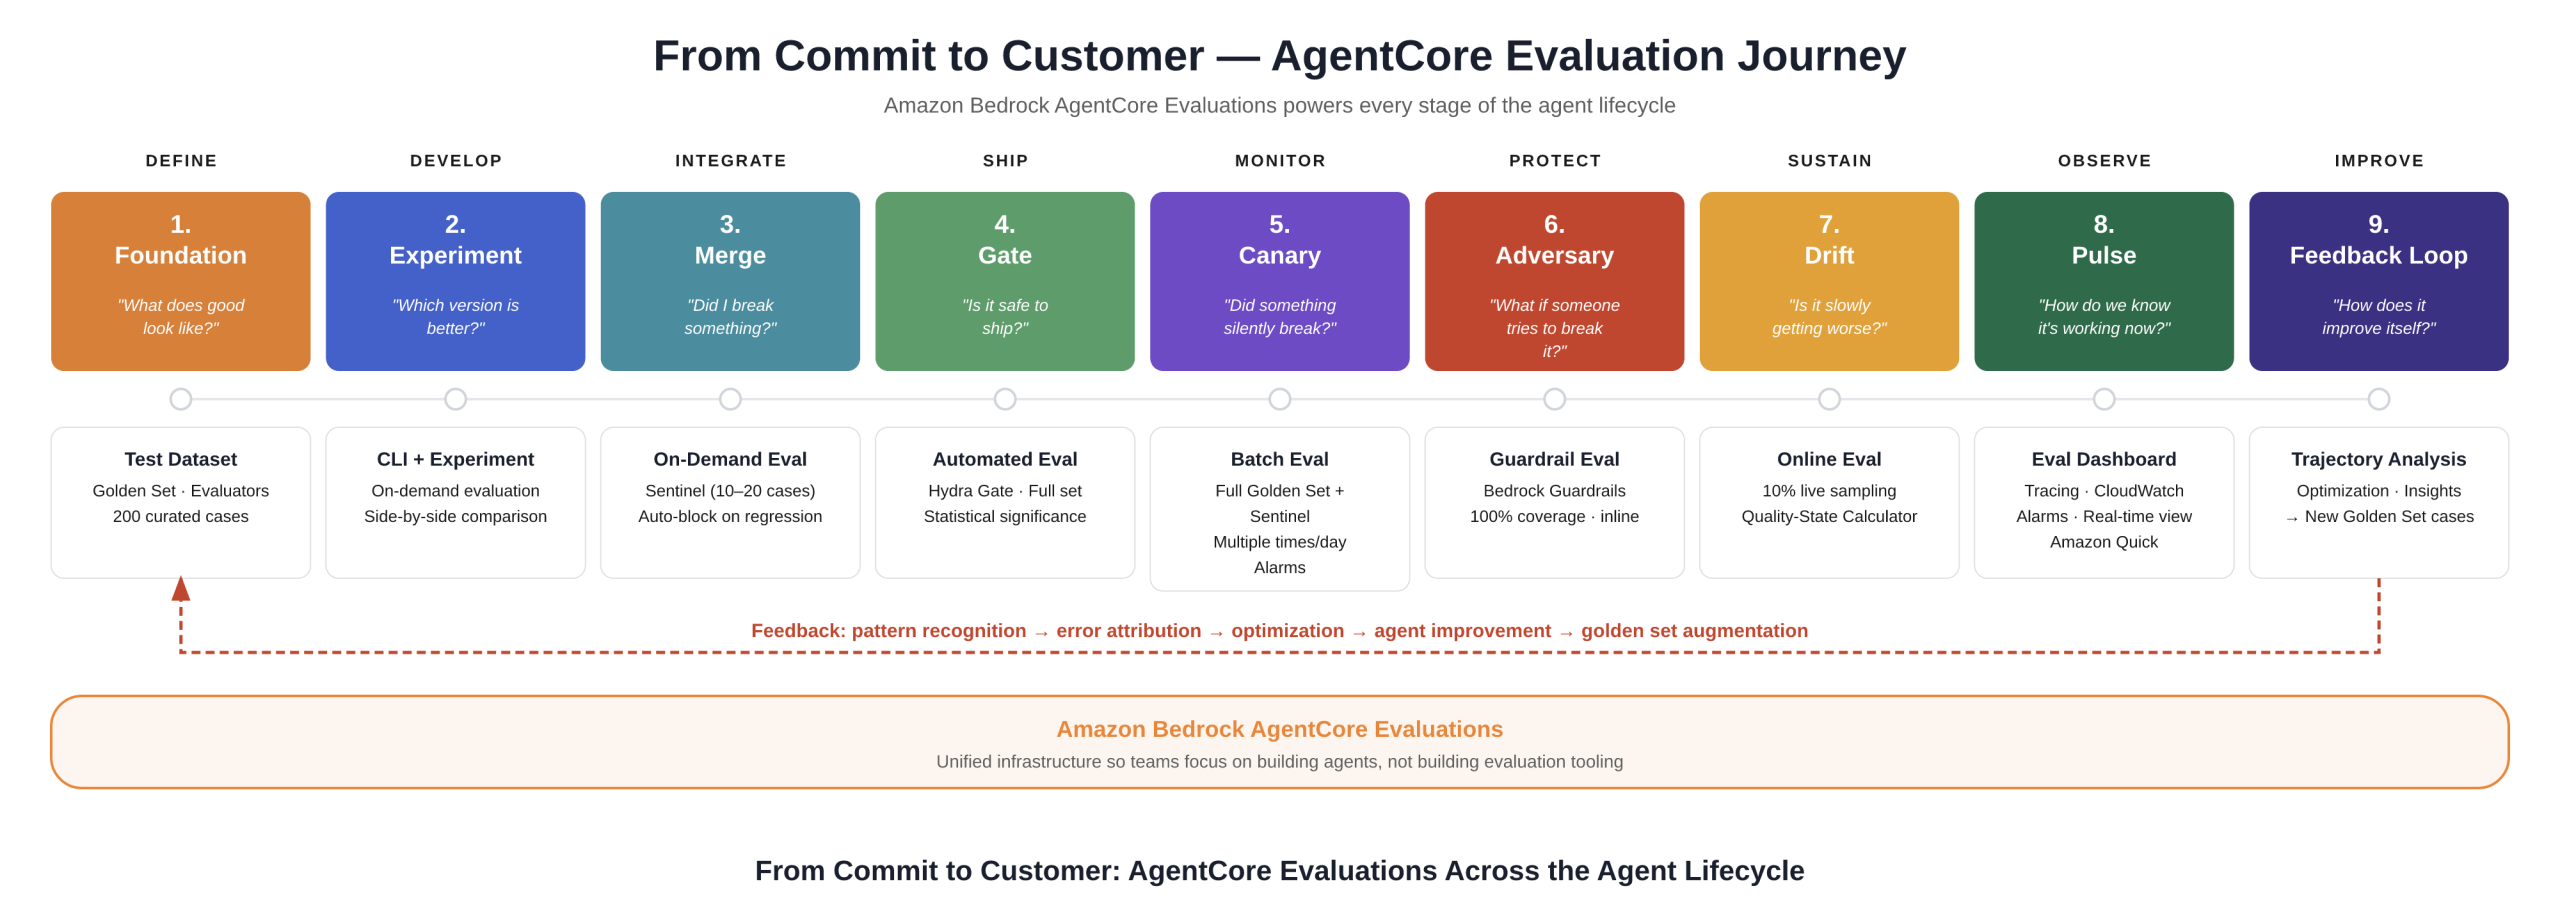
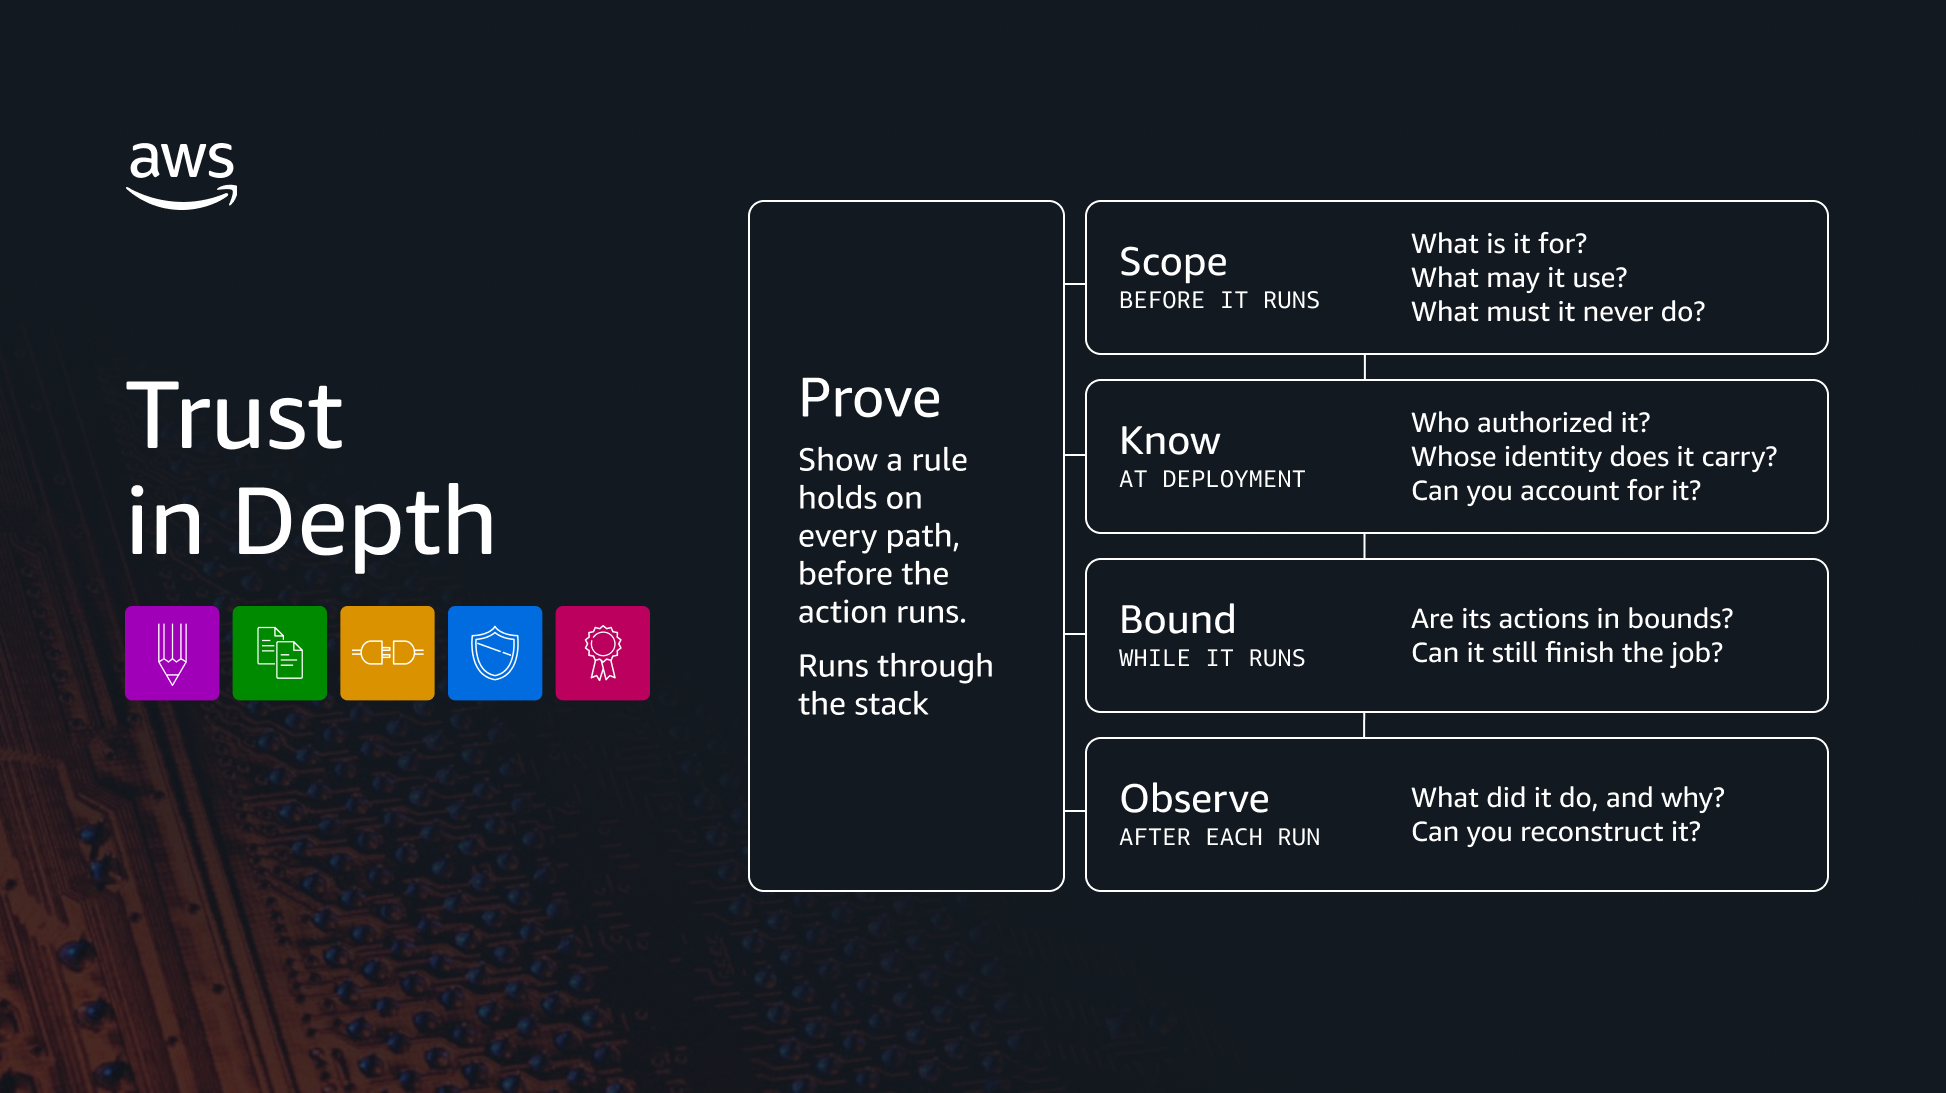
Building trust in AI agents: A production-ready evaluation framework with Amazon Bedrock AgentCore

The North Star Every organization racing to deploy AI agents faces the same reckoning: an agent that demos beautifully can quietly degrade in production, and by the time a human notices, the trust is already broken. Where traditional software fails loudly, agents fail softly. They return an answer that looks confident, reads fluently, and is … Read more

Introducing Reflection Beam: an open-weight model for agentic coding on AWS

Reflection AI introduced Beam, an open-weight model for agentic coding and long-horizon tasks such as maintaining code, using tools, interpreting results, and completing multi-step workflows. The open-weight release gives developers and researchers control over the runtime, deployment environment, and customization process. In this post, we explain Reflection’s vision and show how you can deploy Beam … Read more

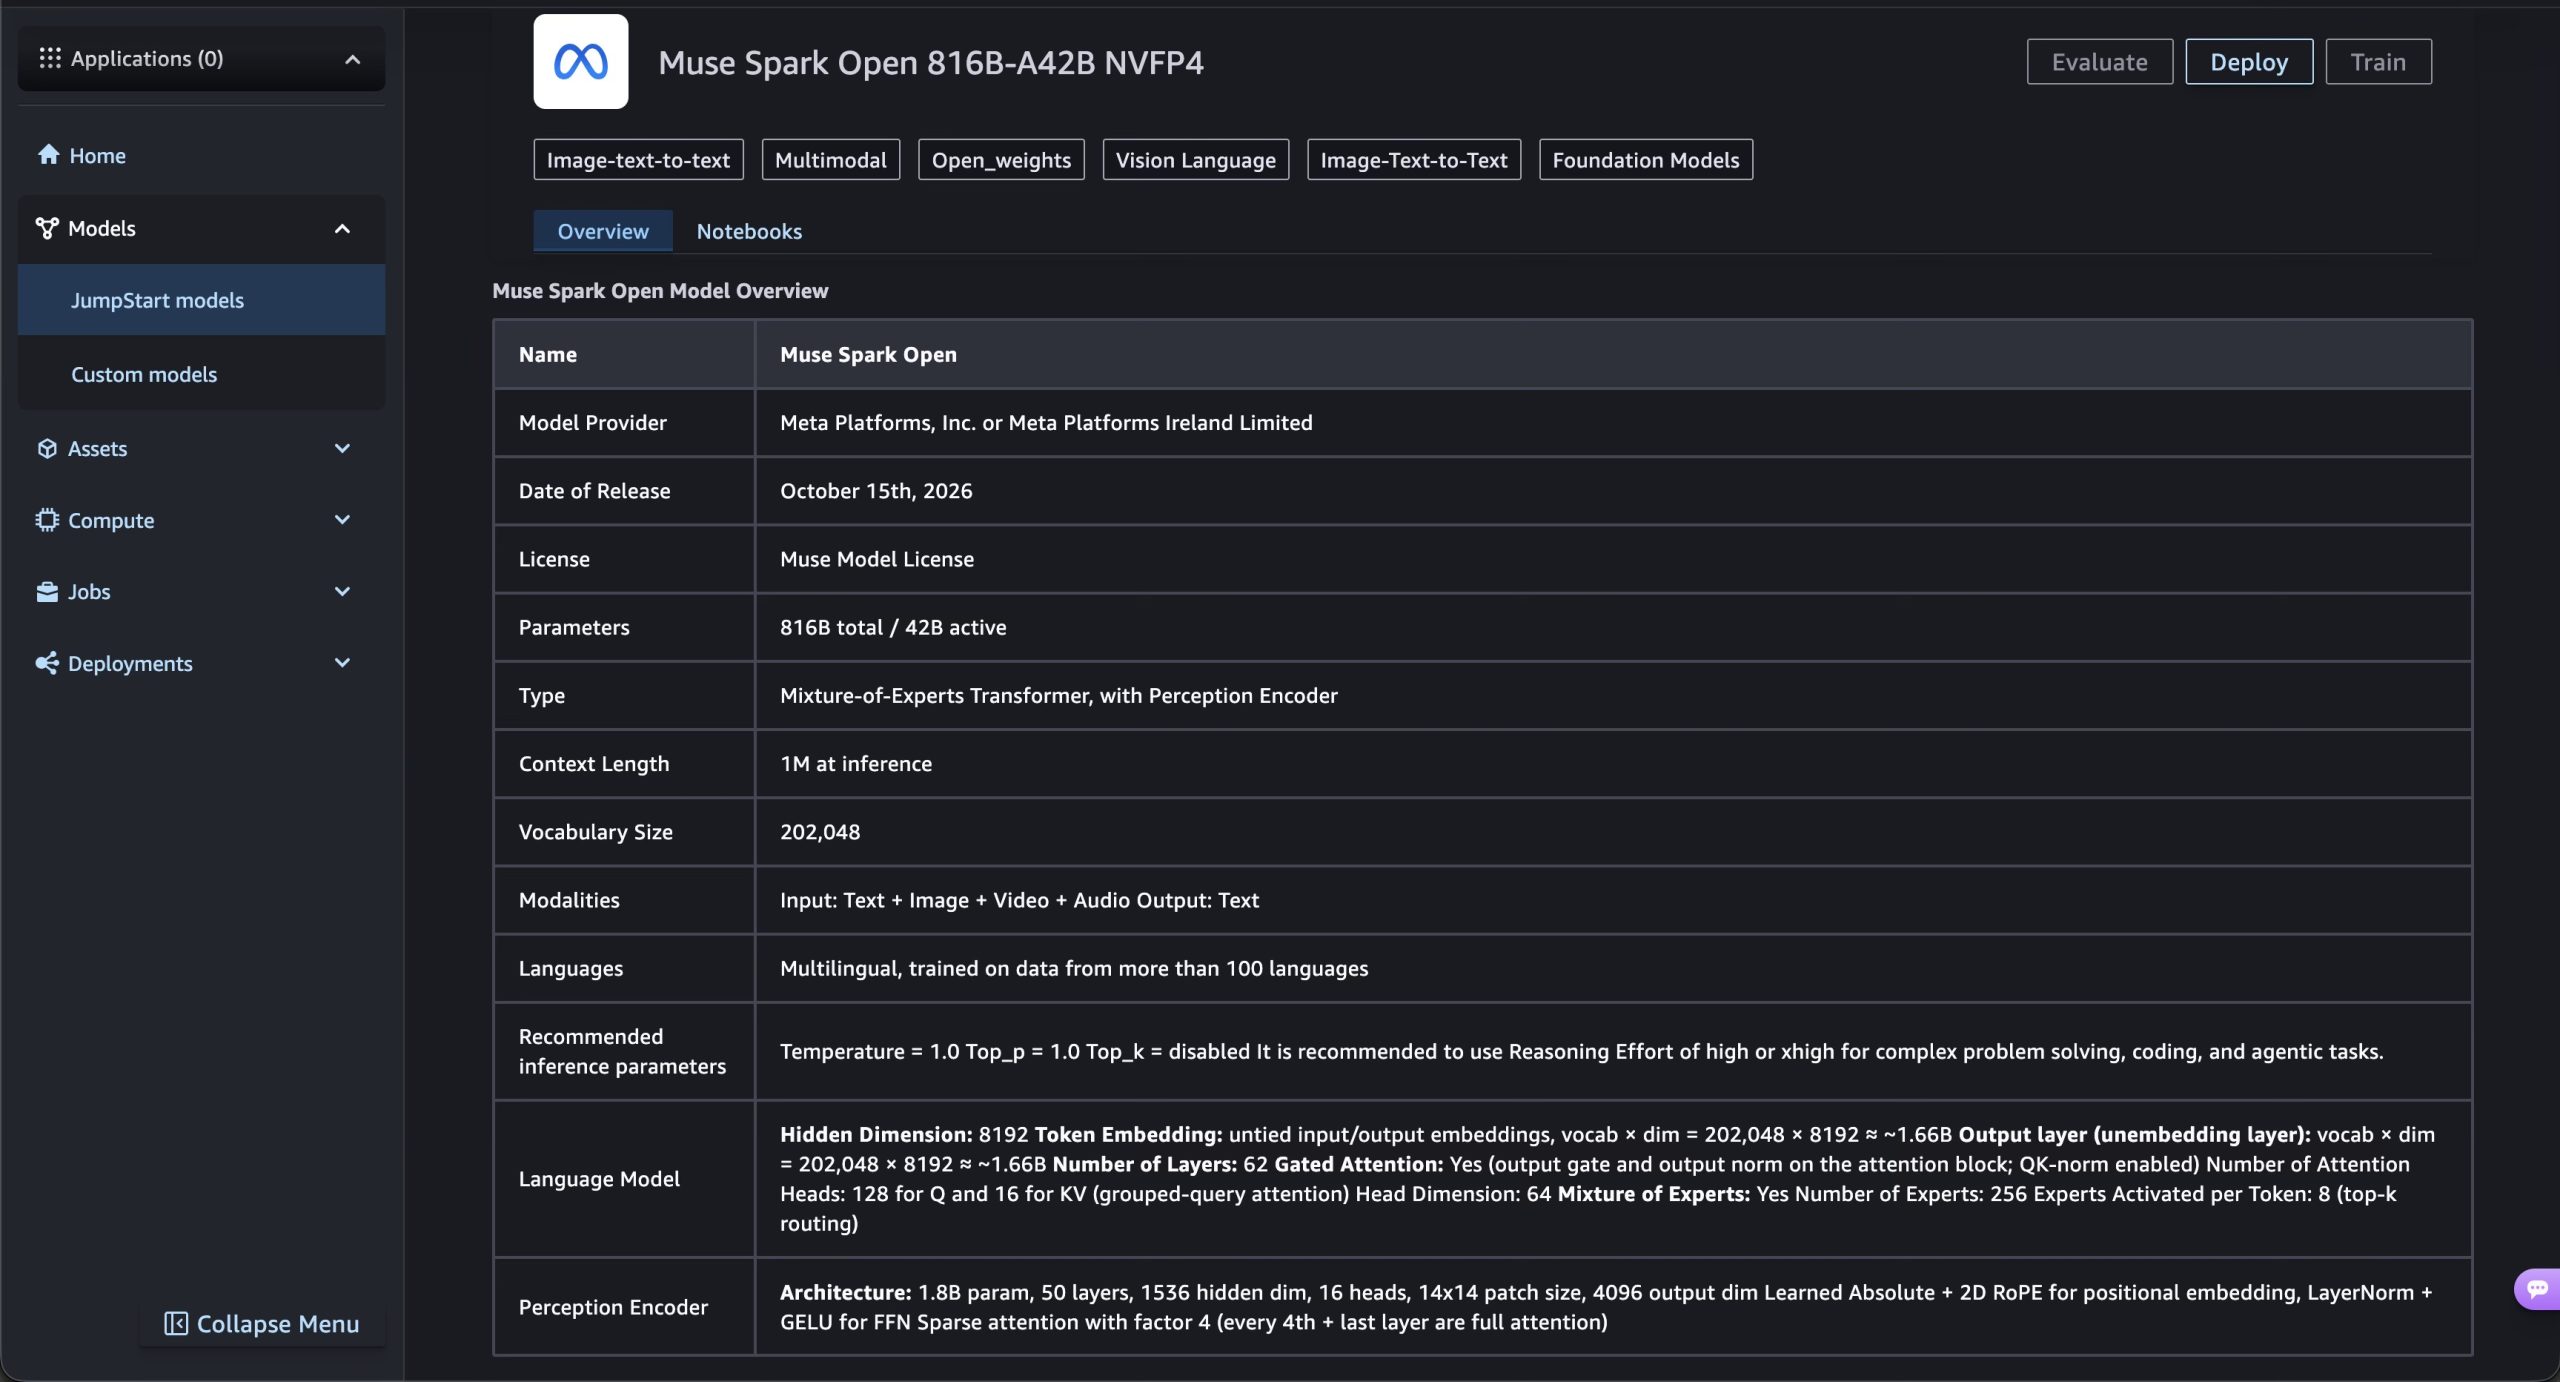
Meta’s Muse Spark Open now available in Amazon SageMaker JumpStart

Muse Spark Open, Meta’s coding-optimized open-weight model, is now available in Amazon SageMaker JumpStart, the machine learning (ML) hub of Amazon SageMaker AI. The model was trained on real developer workflows, such as multi-file refactors and long debugging sessions, and it supports a context window of 1 million tokens. You can deploy it to a … Read more

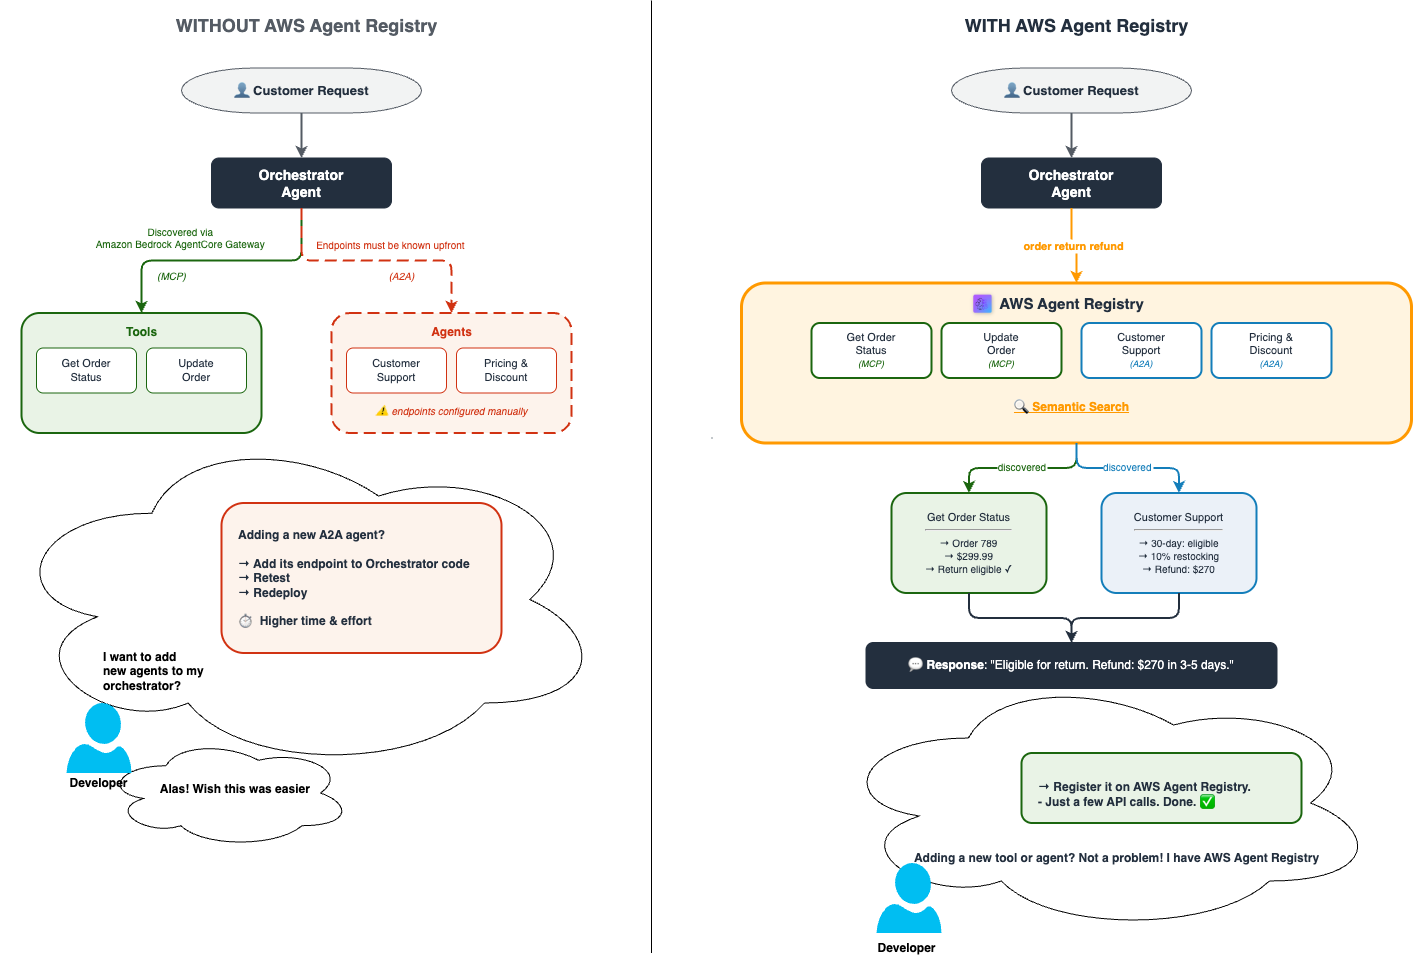
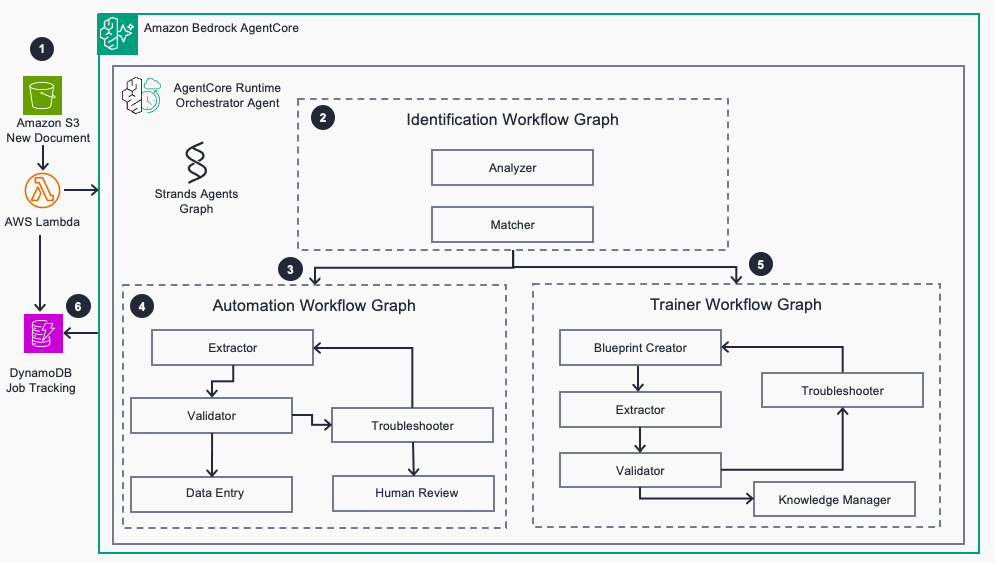
Build self-improving document processing using Amazon Bedrock AgentCore

IDC research shows that document-related challenges cost organizations $19,732 for each information worker annually and reduce productivity by 21.3 percent. Organizations receiving invoices from hundreds of suppliers often face layouts that vary by issuer and change without notice. Template-based systems require constant maintenance at this scale. Staff can spend up to 30 percent of their … Read more

Generate presentations with Amazon Bedrock AgentCore

A financial services team spends significant time each week manually creating client PowerPoint presentations from quarterly reports, compliance documents, and market analyses. Each presentation requires reading hundreds of pages, extracting key data points, structuring slides, and generating supporting visuals. This post walks you through building an AI agent system using Amazon Bedrock AgentCore that automates … Read more