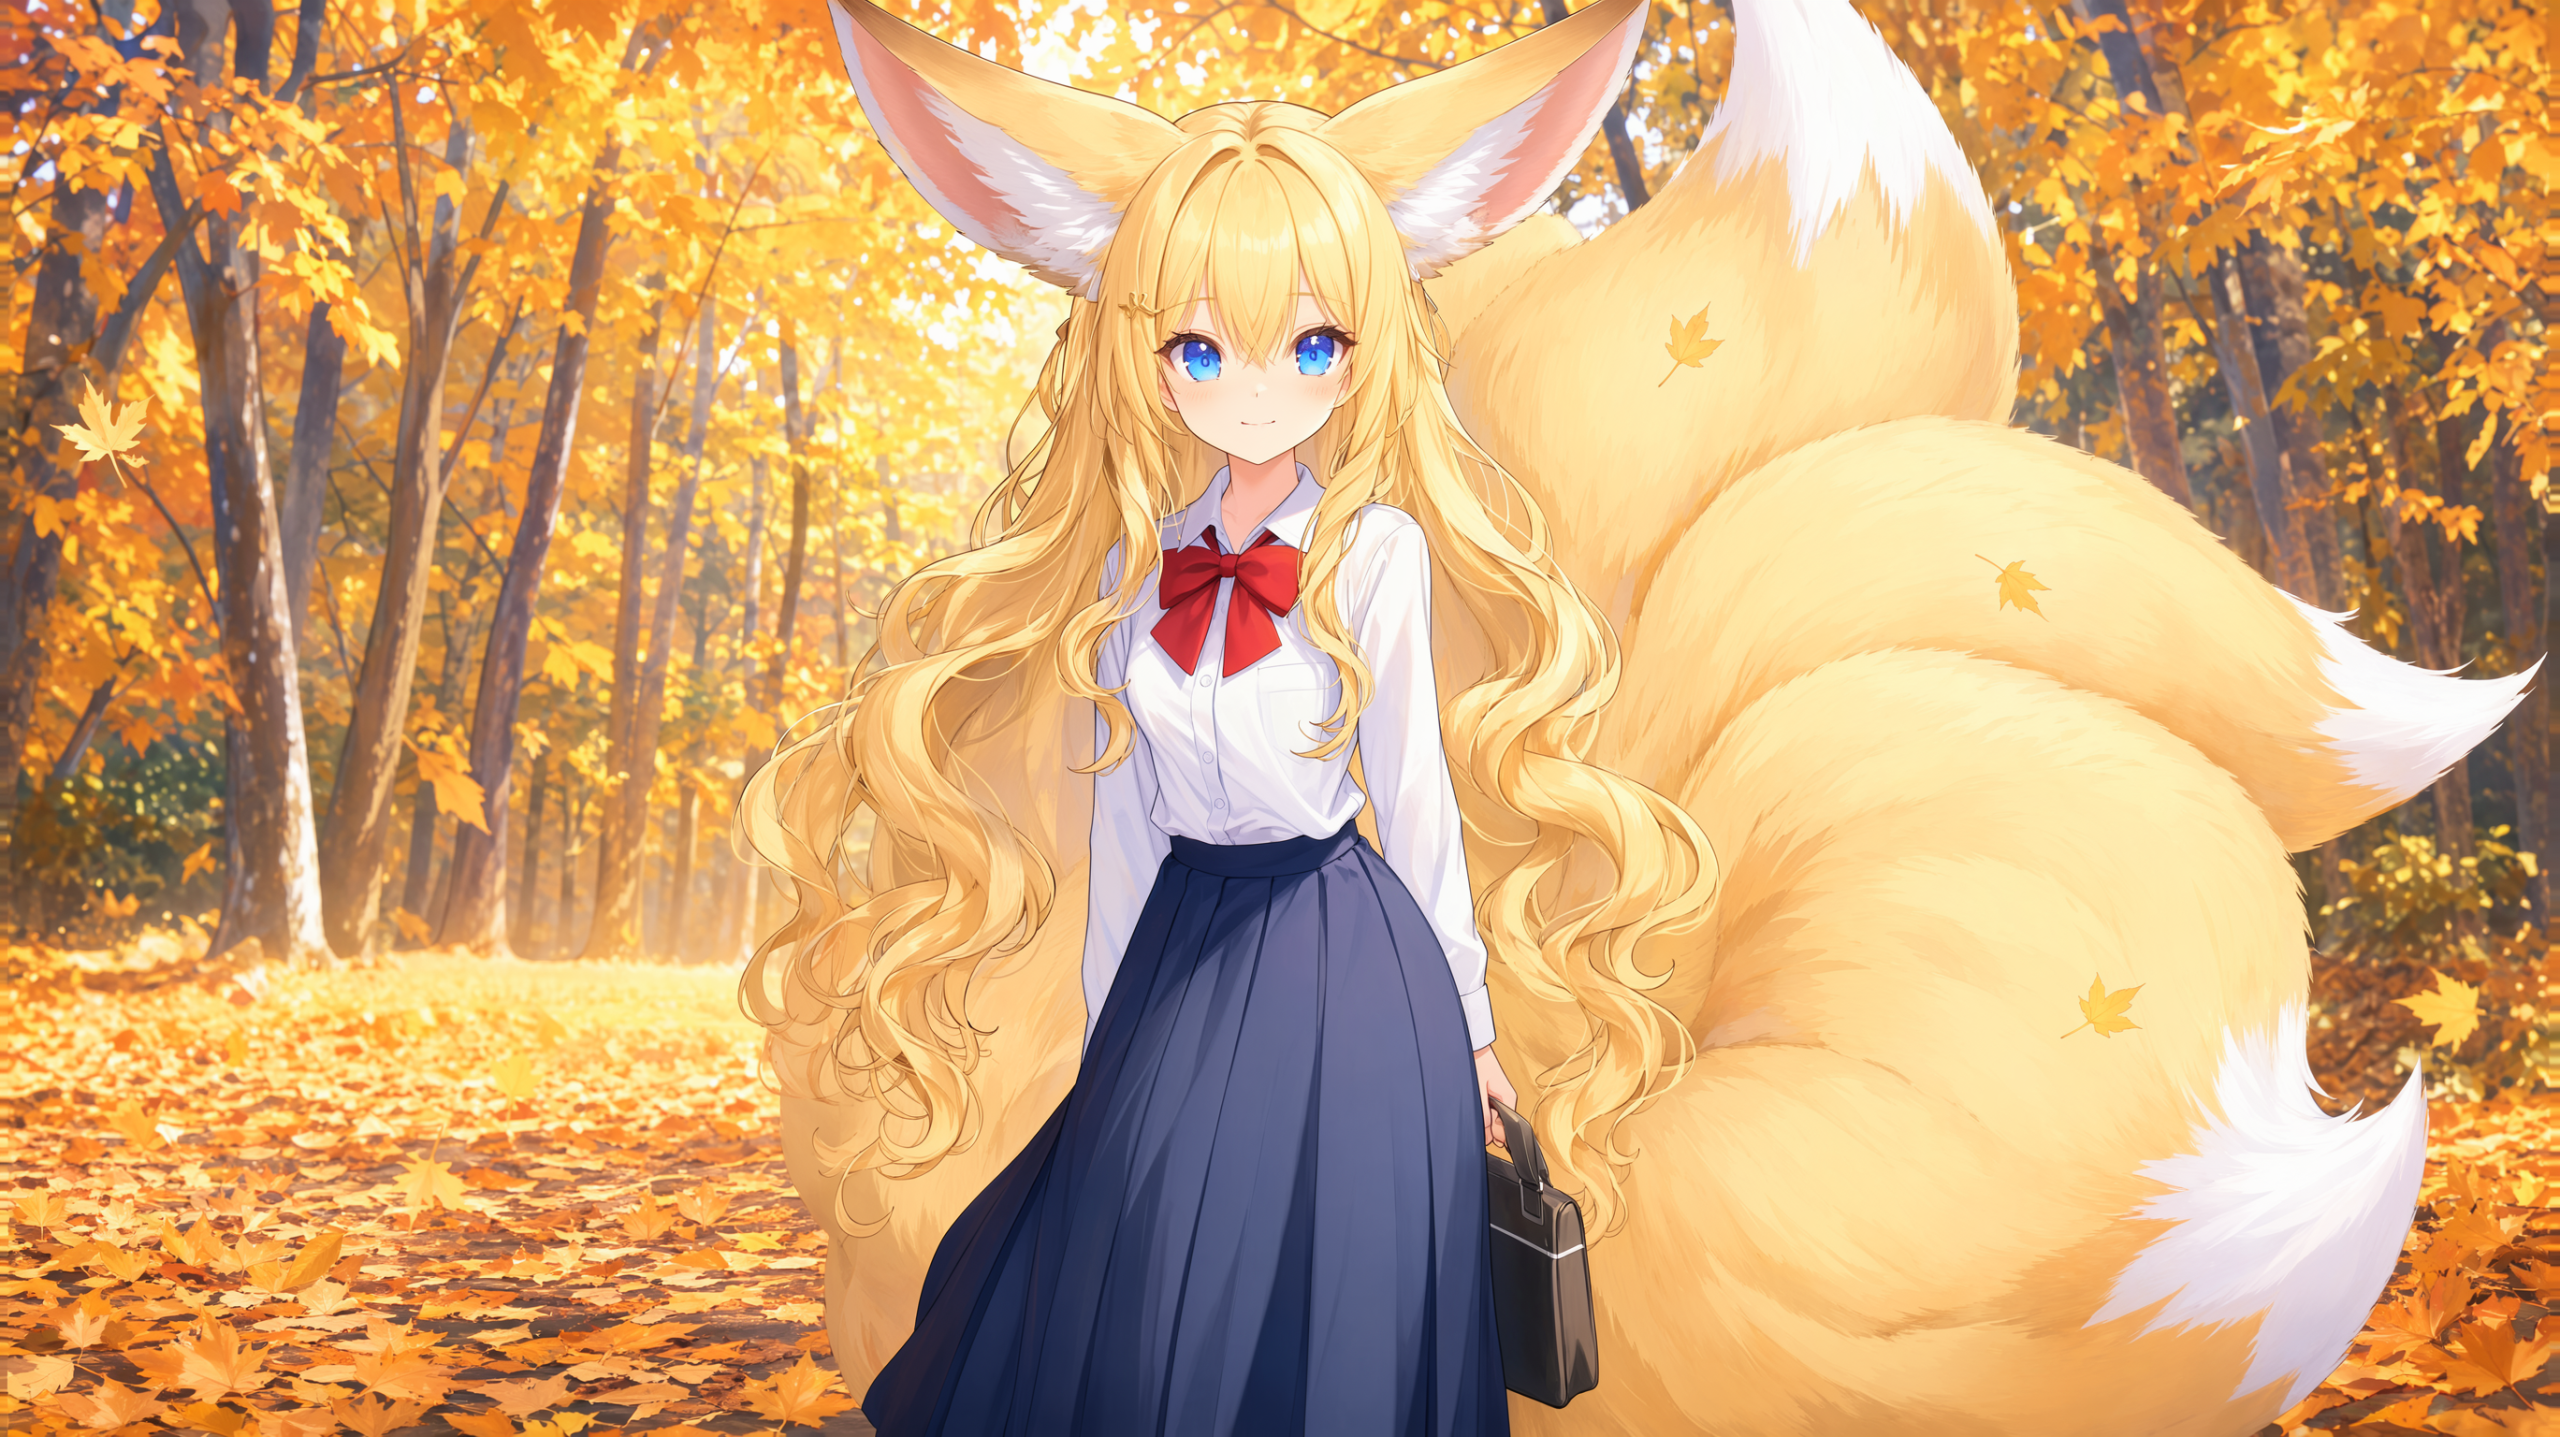
Overview
MOSS_image_MAX_ULTRA_hires_lora_test is a LoHa adapter for Comfy-Org’s MOSS-Image-Base, intended to improve text-to-image generation at 4 megapixels and above. Its maintainer is comfyanonymous.
Best use cases
Use it with its MOSS-Image-Base model for high-resolution text-to-image generation, particularly at 4 MP or higher. The stated training mix includes anime and photographs at 3.5–10 MP.
Limitations
The maintainer describes the training mix as containing possibly too much anime, which may matter for users seeking a different image balance. No license, quantitative evaluation, supported resolution ceiling, or usage example is supplied.
How it compares
The repository shows 9 MP examples for adapter versions v0.1, v0.2, and v0.3 alongside a no-adapter example; these are examples, not measured evaluations. The supplied alternatives target different models or purposes: SD3.5-Large-Photorealistic-LoRA, Moss-image-nsfw-uncensored-lora, Fashion-Hut-Modeling-LoRA, and flux-RealismLora. Their descriptions do not establish direct performance comparisons.
Technical specifications
Type: LoHa adapter; task: text-to-image; base model: MOSS-Image-Base by Comfy-Org. Training images are described as 3.5–10 MP, and the intended improvement is generation at 4 MP and higher. The repository presents three adapter versions and 9 MP examples. Parameter count, file format, training hardware, and quantitative performance are not provided.
Model inputs and outputs
Inputs
Text prompts are supported by the text-to-image task designation. The adapter is intended for use with MOSS-Image-Base; no prompt controls or other input formats are documented.
Outputs
Generated images are the supported output. The examples are labeled 9 MP, but no output format or maximum resolution is specified.
Frequently asked questions
Q: What is this model?
A: It is a LoHa adapter for MOSS-Image-Base, intended for high-resolution text-to-image generation.
Q: What resolution is it intended to improve?
A: The description says 4 MP and higher. The repository also shows examples labeled 9 MP.
Q: What was it trained on?
A: The description says a mix of anime and photographs at 3.5–10 MP, and notes that the anime share may be too high.
Q: Which base model does it require?
A: It is described as an adapter for MOSS-Image-Base by Comfy-Org.
Q: Are there multiple versions?
A: The examples are labeled LoRA v0.1, v0.2, and v0.3. The supplied information does not explain their differences.
Q: Is there a code example or license information?
A: No reliable usage example or license information is supplied.
Original post: Read on AIModels.fyi
This is a simplified guide to an AI model called MOSS_image_MAX_ULTRA_hires_lora_test maintained by comfyanonymous. If you like these kinds of analysis, join AIModels.fyi or follow us on Twitter.